
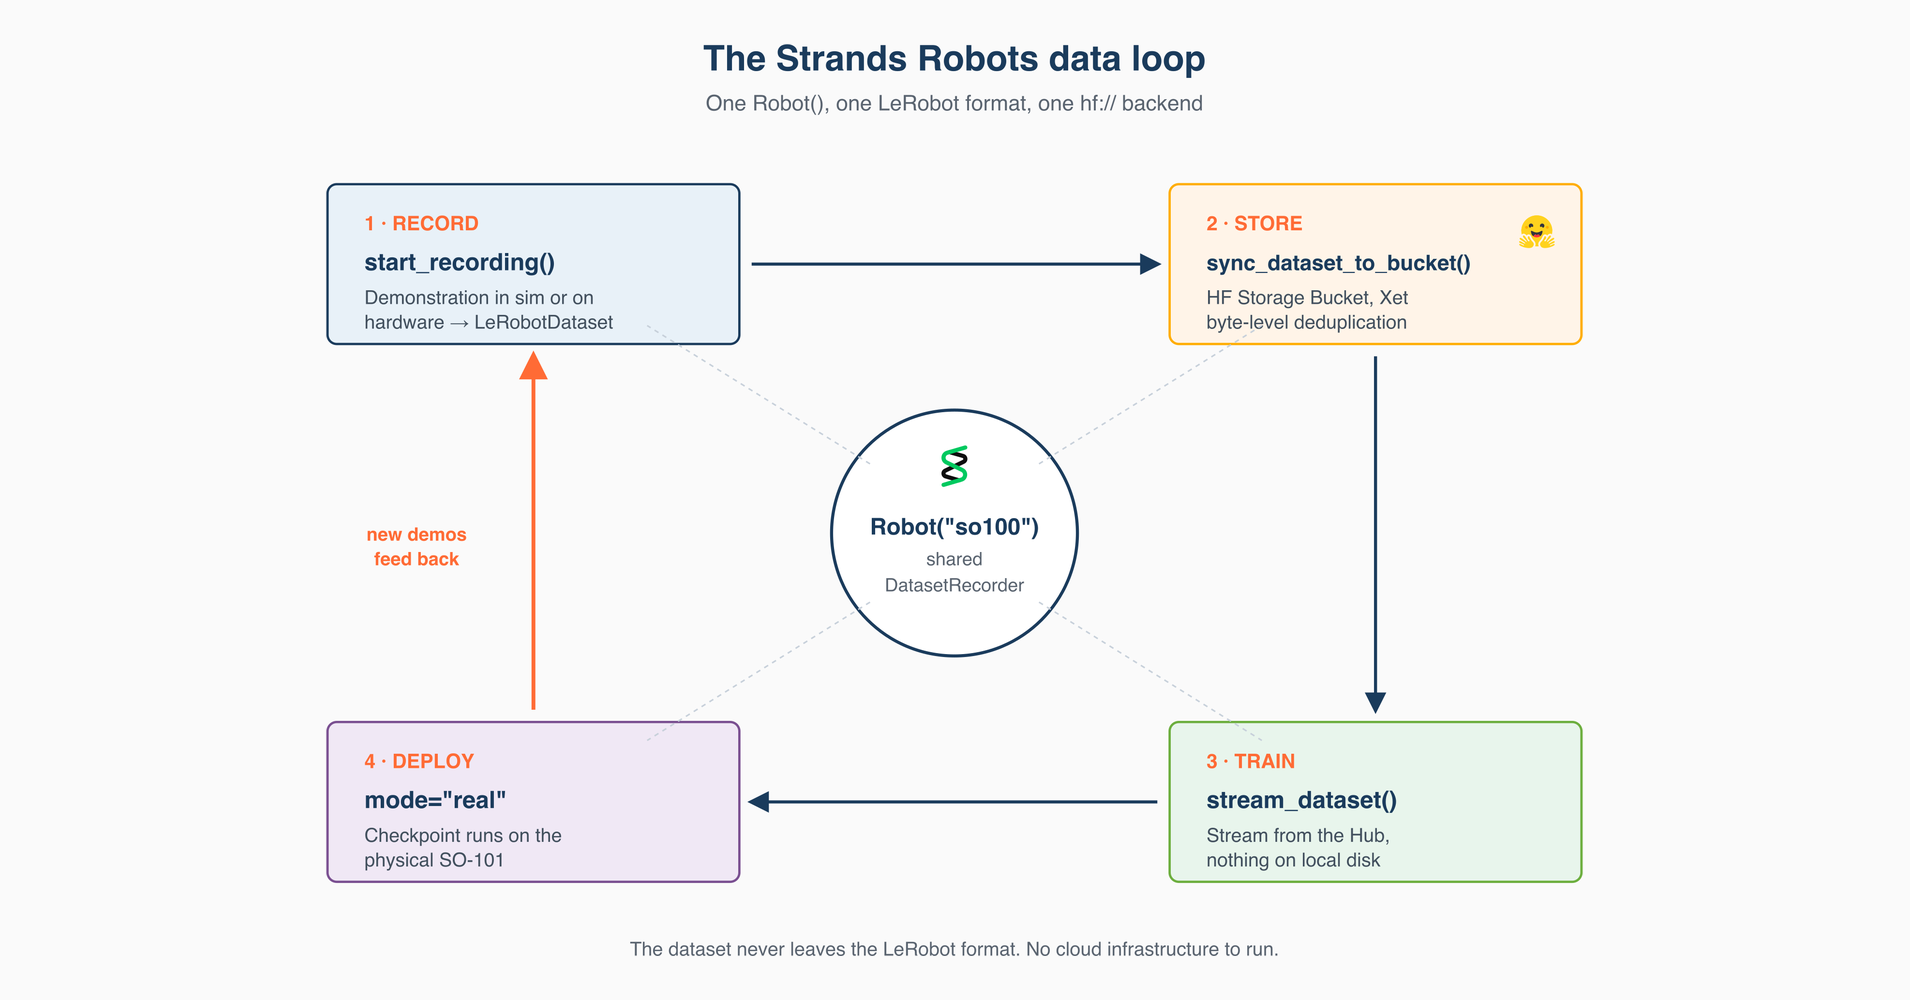
Record, train, and deploy from one place with Strands Agents, LeRobot, and Hugging Face Storage Buckets
A Blog post by Amazon on Hugging Face
More from the blog
State of Supply Chain Sustainability Report finds corporate commitment at record high, but governance lags behind
MIT's Center for Transportation and Logistics finds sustainability commitments are strong, but governance gaps and external disruptions prevent execution.
Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint
Putting Earth AI to work: Geospatial agents for our planet's biggest challenges
Earth AI
Researchers improve weather forecasts looking two to six weeks out
A new machine-learning approach broke records for weather forecasting for an important time frame in emergency planning.
Related papers
What Drives Success in Physical Planning with Joint-Embedding Predictive World Models?
This work characterize models from this family of methods as JEPA-WMs and investigates the technical choices that make algorithms from this class work, and proposes a model that outperforms two established baselines, DINO-WM and V-JEPA-2-AC, in both navigation and manipulation tasks.
StarVLA-α: Reducing Complexity in Vision-Language-Action Systems
This work introduces StarVLA-$\alpha, a simple yet strong baseline designed to study VLA design choices under controlled conditions that deliberately minimizes architectural and pipeline complexity to reduce experimental confounders and enable systematic analysis.
A Very Big Video Reasoning Suite
The Very Big Video Reasoning (VBVR) Dataset is introduced, an unprecedentedly large-scale resource spanning 200 curated reasoning tasks following a principled taxonomy and over one million video clips, approximately three orders of magnitude larger than existing datasets.
Show-Harness: Just a VLM Agent Can Play Robots
Foundation vision-language models (VLMs) exhibit broad intelligence about the world, yet translating this intelligence into robot control remains challenging. We present Show-Harness, an Embodied Harness that enables VLMs to"play"robots through a compact semantic interface linking intent to action. Show-Harness exposes...