LLM agents can now run causal discovery algorithms on a dataset and report what comes out. Whether they do more than that, such as noticing where an algorithm went wrong and fixing it with further tests, is hard to tell from current benchmarks. Most of them give the variables meaningful names, and an LLM shown only the...
Coarsened-consistent panel operators with a closed-form Dirichlet-multinomial realization, learned completion, and rater-count transfer are defined, with modest and corpus-dependent gains, with several small or null partial-revelation differences.
Bin Wen, Dai-Qiao Zhang, Tien-Ping Tan· 0 citations
A prominent family of low-rank LLM optimizers, pioneered by GaLore, performs gradient-subspace projection: at each step, they project the gradient into a low-dimensional subspace and map the update back to the full model. Most existing work either recomputes the gradient subspace at certain intervals, or performs post-...
Xin-Yu Luo, Jin-Cheng Zhou, Meng-Bo Wang et al.· 0 citations
Standard autoregressive decoding advances one token at a time, even when several upcoming tokens can be predicted together. We propose CADENCE (Context-Adaptive DEcoding), a generation method that learns both what to draft and how far to draft. Gaussian prediction heads represent future spans as continuous latent vecto...
Sai Sreenivas Chintha, Chidera Biringa, Rishab Sharma et al.· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Scale calibration learns an update for one model representation. We study how much of that update can be reused by another representation of the same pretrained model. Our transfer procedure extracts positive group-wise gains and installs them in the recipient's weights or native quantization scales without recipient-s...
Bayesian optimization (BO) over discrete spaces is challenging due to missing gradients and the sparsity of valid solutions. Latent-space BO sidesteps both issues by fitting a surrogate in the latent space of a generative model, which however substantially complicates the direct incorporation of domain knowledge that i...
Tommaso Ancilli, Thomas Wedenig, Henry Moss et al.· 0 citations
LLM safety evaluations via jailbreaking typically index on attack success rate (ASR): whether a generated response violates safeguards. However, ASR only evaluates sampled outputs and provides little information on the underlying generation process. Autoregressive language models define distributions over possible outp...
Parv Kapoor, Teresa Fortes, Claudia Mamede et al.· 0 citations
Do larger models learn increasingly similar representations of the same world? The Platonic Representation Hypothesis (PRH) predicts that they should, but similar can mean native cosine geometry---nearest-neighbour structure induced by cosine similarity before any learned alignment---or linear recoverability: correspon...
Angus Hoy, Austin Lutterbach, Jasper Chong et al.· 0 citations
Findings support incorporating price geometry and volume into generative modeling, with field accuracy and predictive uncertainty evaluated together, in a full-field evaluation framework that combines a transport cost sensitive to price placement and total volume with proper scoring rules and calibration diagnostics.
The Long-Range Ising Model benchmark (LRIM) guarantees long-range dependence by construction: each label is the node's spin times the spin field convolved with a power-law coupling, so any model's distance from the target is measurable. We prove that a readout whose filter is a polynomial in the adjacency, the linear c...
Scalable approaches to learning neural dynamical systems have placed diffusion, flow matching, and few-step generators in flow maps at the forefront of generative modeling. Such state-of-the-art models have limited access to explicit model densities despite evolving from classical generative modeling approaches that le...
Francesco Ruscio, Timothy James Hitge, Fred Zhangzhi Peng et al.· 0 citations
We study personalized LLM routing, where a router selects among heterogeneous models with different costs and capabilities. The router must minimize cumulative inference cost while ensuring reliable realized response quality, even though user preferences are unknown and must be learned from feedback during deployment....
Ameya Anjarlekar, Rasoul Etesami, R Srikant· 0 citations
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
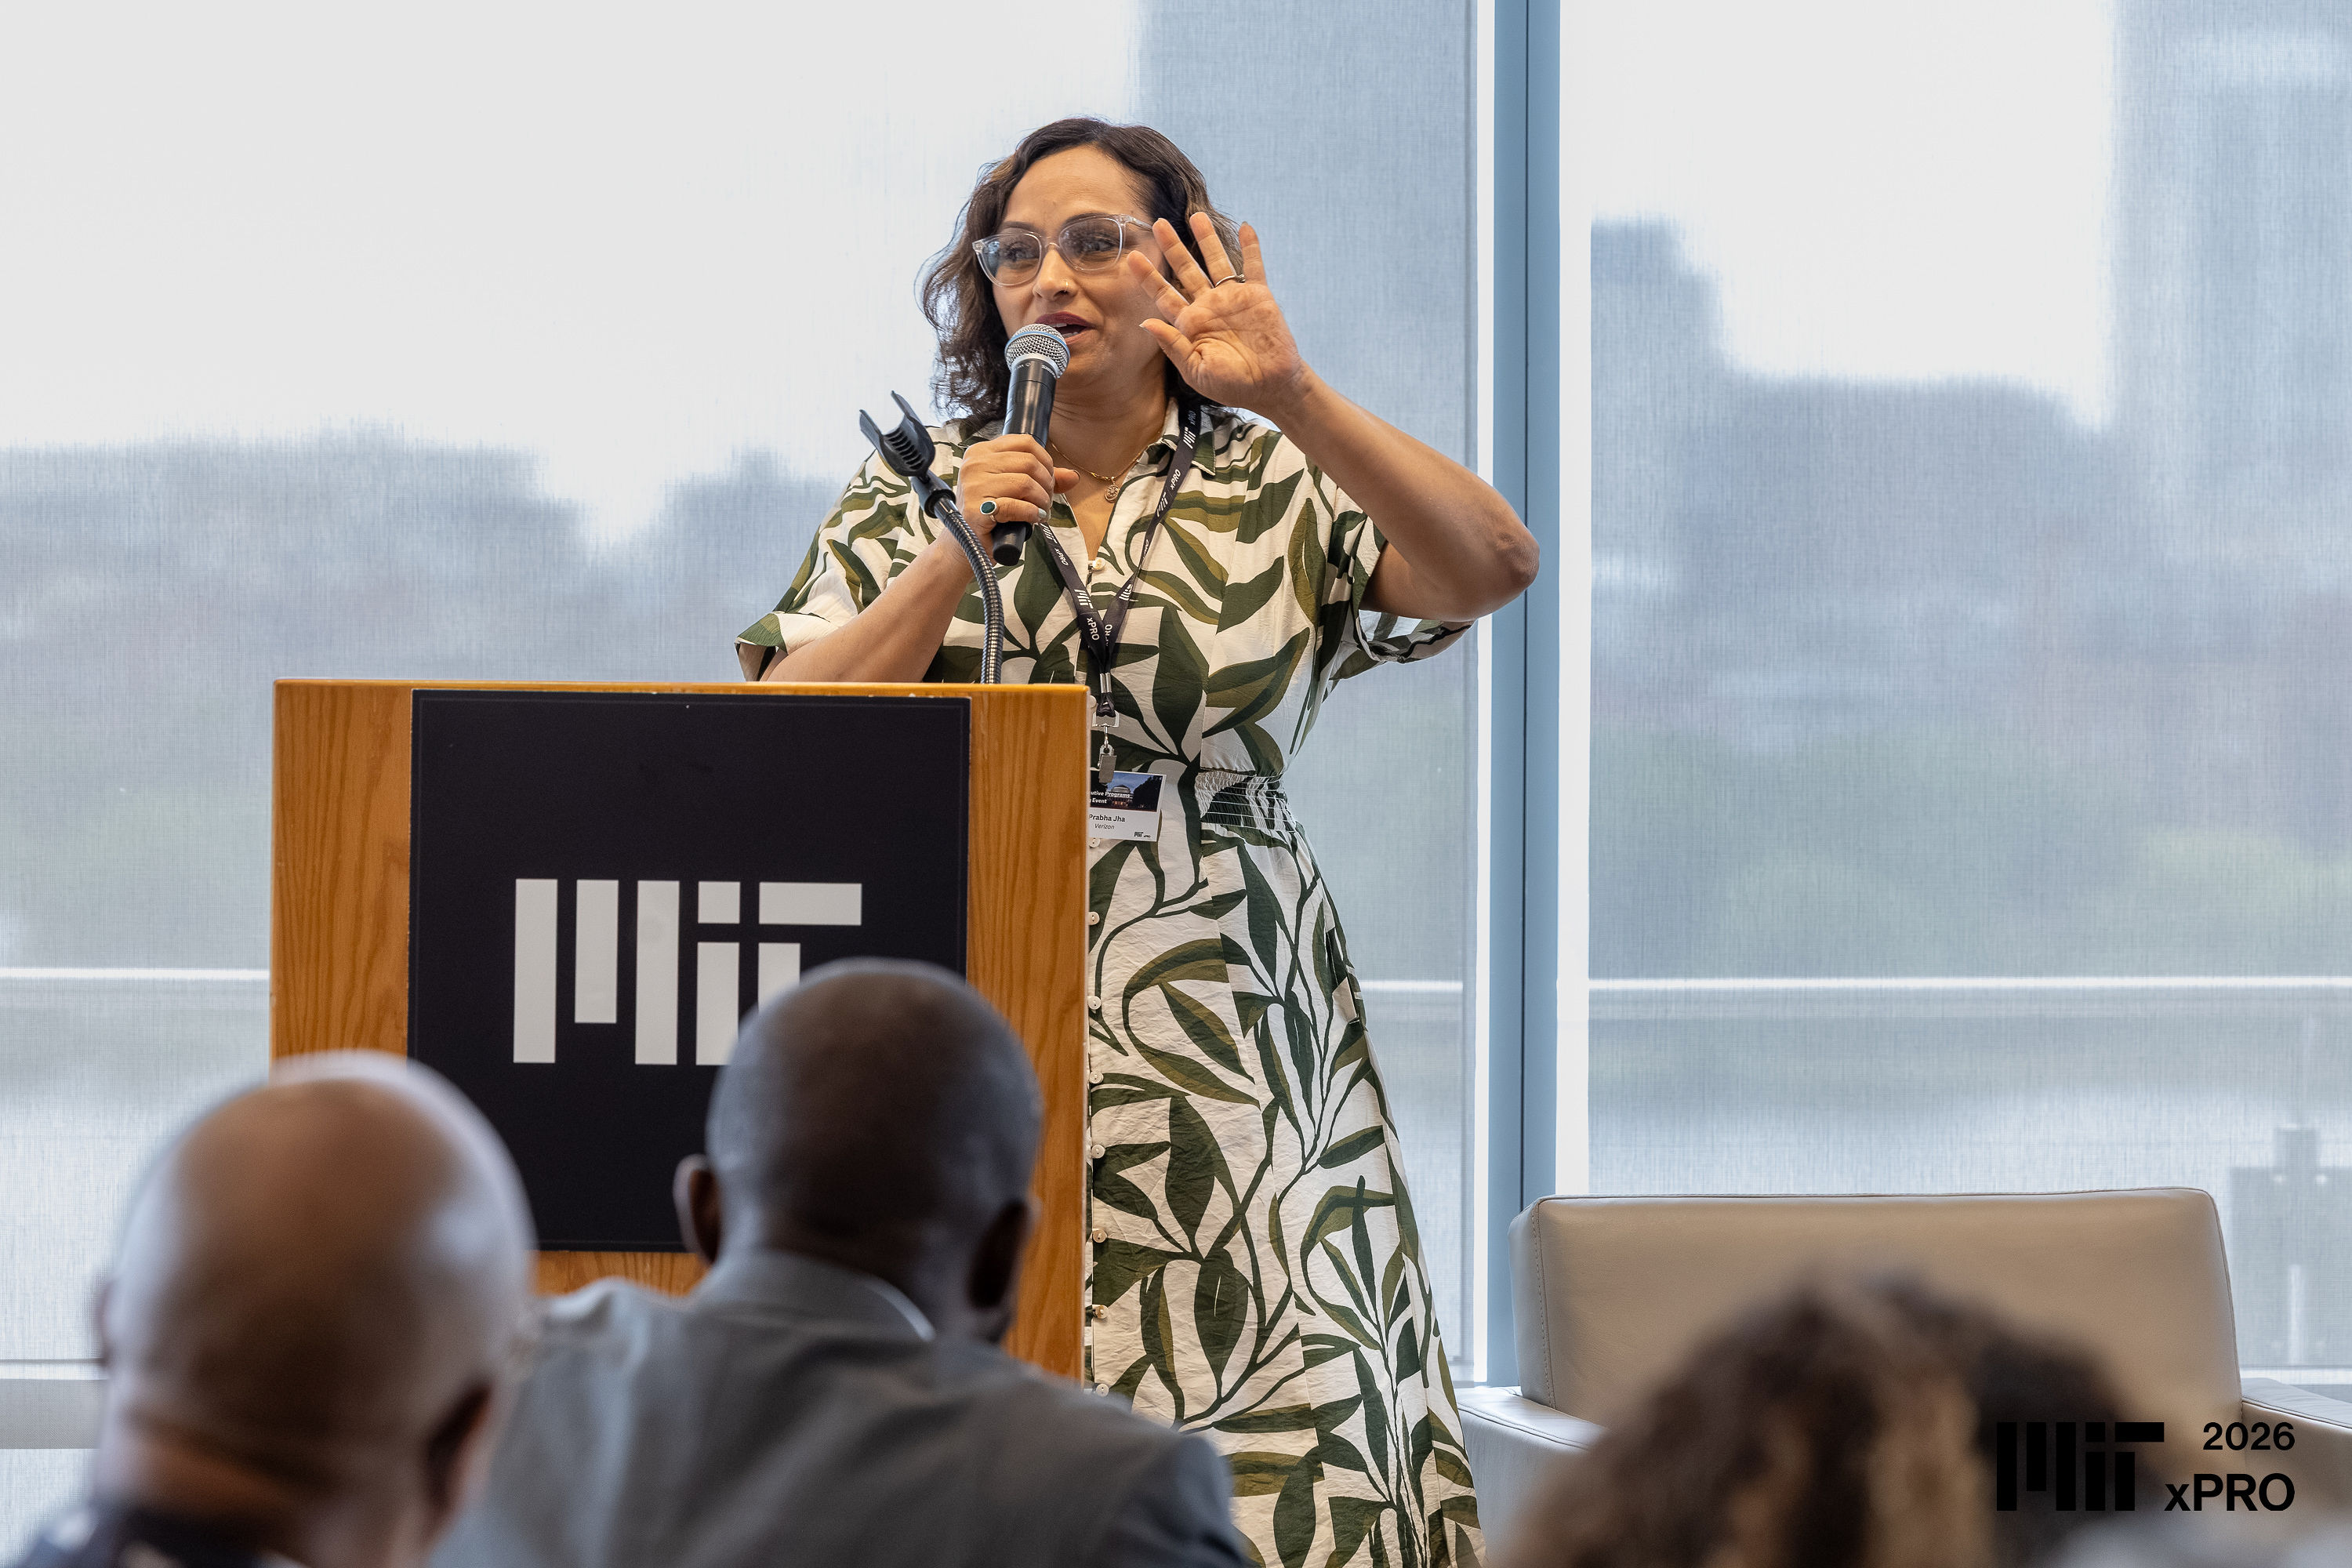
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.