Electroencephalography (EEG)-to-language models offer a promising approach for translating complex neural signals into human-readable descriptions. However, generating plausible language does not necessarily demonstrate that a model has learned to interpret the underlying EEG signal. A direct way to assess such interpr...
Leyuan Jin, Jiahao Mei, Yixuan Yuan et al.· 0 citations
AI models, and time-series models in particular are typically ranked by accuracy and deployed under constraints absent from that ranking. In this paper, we study a real setting where these constraints are explicit and measurable: handover pre- diction in cellular networks, where inference runs on the User Equipment onc...
Shruti Bothe, Illyyne Saffar, Ayush K. Varshney· 0 citations
Offline contextual pricing often relies on logged observational data, but faces challenges from distributional shifts between training and deployment environments. Distributionally robust optimization (DRO) provides a principled approach to off-policy evaluation and learning (OPE/L). However, existing methods are mostl...
Min Xu, Xinyi Yin, Yunfan Zhang et al.· 0 citations
A ground-truth-first framework based on converse optimality is developed, constructing each task with a certified optimal value function and policy withheld from learners and used only for evaluation, and extends beyond smooth affine Gaussian systems to include non-affine raw-action interfaces and finite-covariance non...
Grégoire Ouerdane, Sinan Ibrahim, S. Streif et al.· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Sparse attention reads only a small subset of the key-value cache, and how to treat the unread tail remains a key challenge. Discarding the tail biases the output, and sampling it as previous approaches do fails at reads of 5% and below, where the tail likely holds heavy hitters the selector missed. Our key observation...
Hyunwoo Yu, Jongbeom Lee, Hyunbin Kim et al.· 0 citations
It is suggested that MTSC evaluations should distinguish the effect of pretrained weights from that of the underlying architecture and should include both architecture-matched random initialization and strong non-pretrained baselines.
Chemical AI workflows routinely represent the same molecule through multiple co-referring identifiers, including trivial names, IUPAC names, and SMILES, implicitly assuming that these representations provide interchangeable access to an LLM's knowledge. To test this assumption, we first introduce a controlled benchmark...
PowerPoint presentations (PPTs) are a dominant medium for communication across diverse domains, yet high-quality PPT generation still depends heavily on labor-intensive human effort. Recent advances in large language models (LLMs) for agentic tasks have created both new opportunities and challenges (Chen et al., 2026)...
Yuhang Xie, Cheng Li, Chenliang Li et al.· 0 citations
This work study both hard label distillation, where students train on numbers generated by a biased teacher, and on-policy soft label distillation, where students generate the data and the teacher's logits provide the learning signal, finding transfer persists in both settings across differences in weight initializatio...
Reinforcement learning (RL) is credited with teaching reasoning models to write {wait} before reconsidering a step, yet large RL accuracy gains do not require the word. This view can confuse what RL discovers with what a model inherits from its training data. We trace the word through open models'training histories, re...
Zhi-Zhuo Kou, Si-Zai Hou, Long Chen et al.· 0 citations
On-policy self-distillation (OPSD) improves reasoning by training a model on its own trajectories with dense token-level supervision from a privileged copy conditioned on a reference solution. Existing methods typically use a single teacher distribution conditioned on the complete reference. We identify a limitation of...
Mix-policy optimization incorporates off-policy expert data into the reinforcement learning (RL) loop to transcend the capability boundary of on-policy RL. However, existing methods either provide static full-trace guidance that suppresses self-exploration, or adopt expert prefix guidance without correctness guarantees...
Xuyang Zhong, Jiuding Yang, Yiwen Guo et al.· 0 citations
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
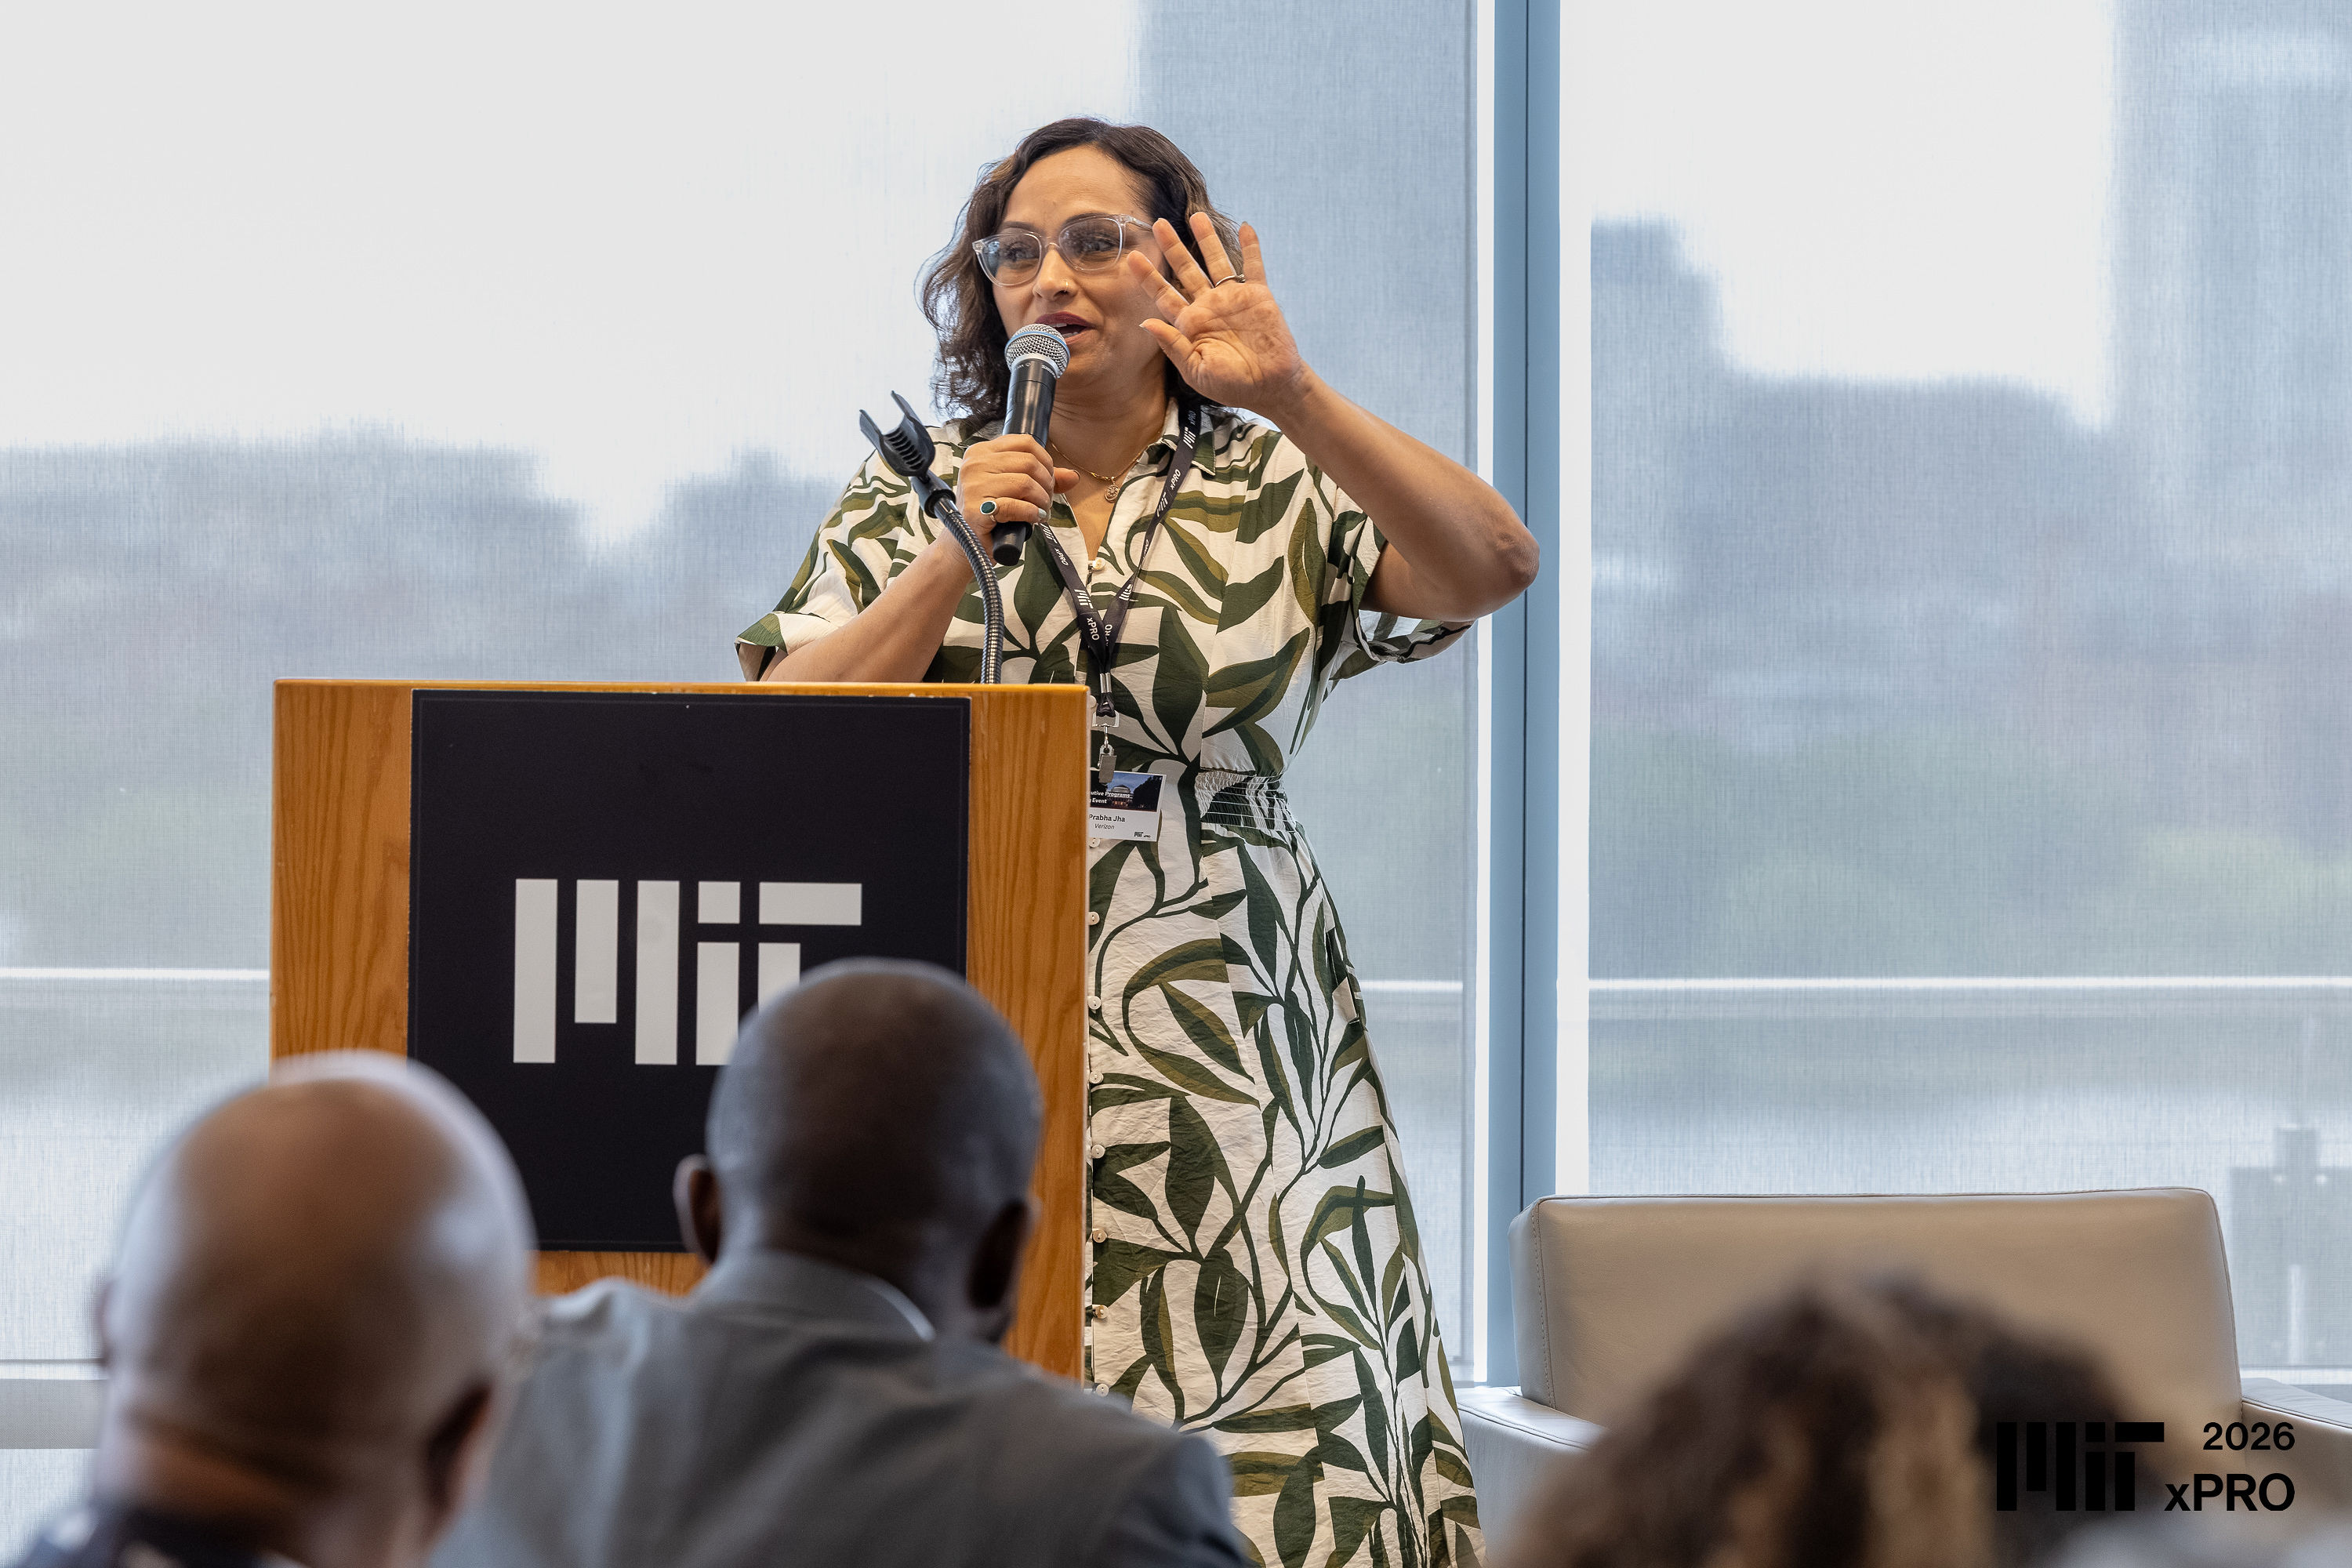
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.