The basal ganglia are central to the selection and execution of actions, integrating diverse information to shape motor, cognitive, and motivational behaviors. Within this network, the striatum occupies a key position where convergent cortical, thalamic, and neuromodulatory inputs are transformed into patterns of activ...
Élodie Fino, Maxime Assous, Marc Vincent Fuccillo· Frontiers in Cellular Neuros...· 0 citations
Integrated sensing and communication (ISAC), semantic communication, and mobile edge computing (MEC) jointly create a high-dimensional, non-convex, and time-coupled resource allocation problem in sixth-generation (6G) networks that existing heuristics and deep reinforcement learning (DRL) methods solve either slowly or...
Abrar S. Alhazmi, M. M. Alenazi· Mathematics· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Closed-loop artificial intelligence is increasingly claimed for metal-fabrication systems that combine reinforcement-learning-based process control with vision-based quality inspection. This review organizes the reinforcement-learning, computer-vision, and production-economics literature bearing on metal cutting around...
Berestov R.· Zenodo (CERN European Organi...· 0 citations
Cascading failures in hybrid AC/DC power systems can propagate rapidly through DC-side disturbances, AC branch overloads, topology changes, and islanding, making emergency mitigation a constrained sequential decision-making problem under evolving network structures. This paper proposes a topology-aware graph reinforcem...
Shuhan Zhao, Zhenghong Tu, Ying Xu et al.· Electric Power Systems Resea...· 0 citations
High renewable energy penetration intensifies net-load ramping and increases the demand for operational flexibility in distribution networks. However, existing hybrid AC/DC distribution network planning studies rarely consider both renewable ramp stress and the network deliverability of available flexibility. Furthermo...
In this paper, we propose a complete mathematical framework for optimizing network slicing and resource allocation at the electronic system-level (ESL) of 6G ultra-reliable low-latency communication (URLLC). We present a multi-dimensional, non-convex mixed-integer stochastic optimization problem that jointly optimizes...
Luma Abd Al-Kareem Hussein· Iraqi Journal for Computers...· 0 citations
Magnetically driven microrobots have shown significant potential in biomedical applications, including endovascular intervention, targeted therapy, and drug delivery, particularly in the treatment of cardiovascular diseases. Conventional vascular interventional procedures typically rely on physicians to manually manipu...
Qihong Duan, Jin Wu, Nat Hsu et al.· Actuators· 0 citations
Reward generation is a central component of reinforcement learning, preference optimization, and self-improvement in large language models (LLMs). Existing approaches have demonstrated that an LLM can evaluate its own outputs and use the resulting judgments to improve its behavior. However, self-rewarding systems may s...
Jincheng Zhang· Zenodo (CERN European Organi...· 0 citations
Large language models (LLMs) can generate candidate answers, evaluate their quality, and use evaluation signals to improve subsequent responses. However, self-evaluation may reinforce a model's own biases and errors, whereas evaluation by other models may introduce evaluator disagreement, capability mismatches, and cor...
Jincheng Zhang· Zenodo (CERN European Organi...· 0 citations
The increasing complexity of real-time electricity markets and fluctuating load demands challenges traditional economic dispatch methods, which often fail to balance cost efficiency and system reliability. This study presents a Deep Reinforcement Learning (DRL) framework for real-time power dispatch, enabling adaptive...
Ekeriance Dominic Evanson, Cherukei Agbara· Iconic Research and Engineer...· 0 citations
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
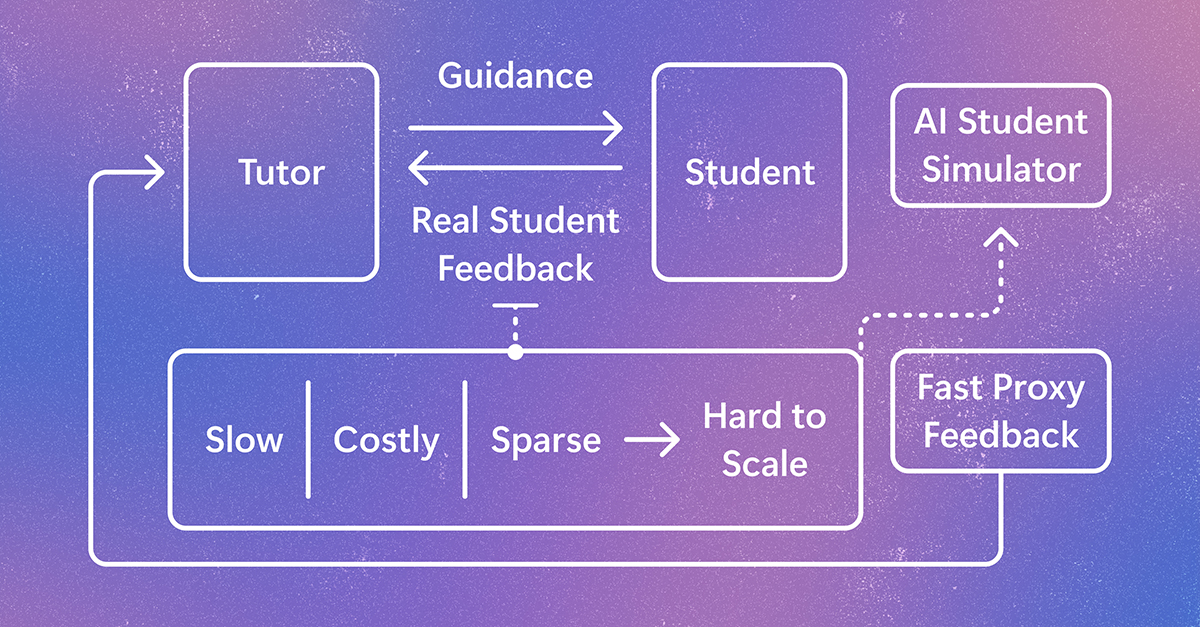
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 7, 2026
Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.