Local model does not mean local software. This first-edition report from Stridenalysis, the research desk of StrideNote, brings together eleven investigations published between June and August 2026 on one question: what does a local AI tool send from the machine it runs on? Seven tools from a working local AI stack wer...
StrideNote· Zenodo (CERN European Organi...· 0 citations
Importing a STEP file into a parametric CAD system yields a single frozen solid: the design history is gone, and no pad depth or hole diameter can be edited. Recovering that history is a well-studied problem — the acceptance criterion used here was stated as a definition by Gupta and Nau in 1995, and commercial impleme...
Daniel Newcome· Zenodo (CERN European Organi...· 0 citations
CDRS-E 0.1.0rc1 is a software-only release candidate for auditablecoordinate-constrained dynamical representation selection. This Zenodo record is designed to archive the exact source-and-tests ZIPassociated with the public GitHub pre-release v0.1.0rc1. The software isbound to commit 892abf572ddbc17bc5370129cd755640e67...
Antonio Clim· Zenodo (CERN European Organi...· 0 citations
PooledScreenAudit 0.4.0 is an installable Python implementation for auditing control-associated prediction in pooled variant-effect screens. Starting from prepared variant–condition and residue-level matrices, it provides matched prediction with and without control features, rank-aware representation geometry, size-mat...
niu niu, Wei Fang, Wenjuan Li et al.· Zenodo (CERN European Organi...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
This repository contains the code, experiment workflows, and collected test data for reproducing safety attack experiments on isolated Binance Smart Chain (BSC) test networks. The artifact covers four experiment families: a warm-up attack, a committee divergence attack, parameter-adjustment experiments, and a geo-distr...
Rujia Li· Zenodo (CERN European Organi...· 0 citations
Importing a STEP file into a parametric CAD system yields a single frozen solid: the design history is gone, and no pad depth or hole diameter can be edited. Recovering that history is a well-studied problem — the acceptance criterion used here was stated as a definition by Gupta and Nau in 1995, and commercial impleme...
Daniel Newcome· Zenodo (CERN European Organi...· 0 citations
In an ever-evolving, high-demand, and resource-constrained healthcare environment, it is imperative that healthcare administrators and policy makers understand both theoretically and practically the influence of organizational practices on employees’ behaviour. This study, drawing on Resource-Based View (RBV), AMO-Fram...
Waseem Ahmed, Abang Azlan Mohamad, Lo May Chiun· International Journal of Aca...· 0 citations
Final data and study-trained models supporting Diagnosing reference support and selection failures in enzyme annotation, version 2.6.0. The archive includes historical candidate-support and restoration results, sequence-separated evaluation, paired CLEAN comparisons, query/component diagnoses, saved scores and final fi...
Yugeng Liu· Zenodo (CERN European Organi...· 0 citations
This record contains the data, code, trained model artifacts, and evaluation outputs supporting the manuscript “Event-based Rainfall–Runoff Modeling with Hydrology-Aware Temporal Convolutional Networks: A Single-Basin Case Study.” The study evaluates an event-based hydrology-aware Temporal Convolutional Network (TCN) u...
Sidar Aksakal, Recep Çelik· Zenodo (CERN European Organi...· 0 citations
Benchmark software, a preregistered protocol, completed five-model primary artifacts, controls, a StarCoder2 stopping-rule ablation, and a technical report testing whether the HumanEval ranking in Qwen2.5-Coder Table 5 survives local deployment.
Jaiveer Bassi· Zenodo (CERN European Organi...· 0 citations
0.14.0 — checkpoints, witness cosignatures, split-view and freshness (2026-09-19) Two limits declared in the README since 2026-08-17 — split-view / equivocation and rollback / freshness were "future work" — are now measured features, built with the transparency ecosystem's own formats so that the ecosystem's own softwa...
robertolocatelli81-dev· Zenodo (CERN European Organi...· 0 citations
Versioned software and reproducibility materials for fail-closed regional eQTL–GWAS integration. Version 0.2.0 includes synthetic verification, locked protocols, tests, aggregate audit outputs, a multi-signal robustness experiment, LD-GuardNet signed-LD graph anomaly triage with model checkpoints, and a frozen multi-ti...
Zhiyong Tao, Yi Wei Zhang, Chulin Zhong et al.· Zenodo (CERN European Organi...· 0 citations
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
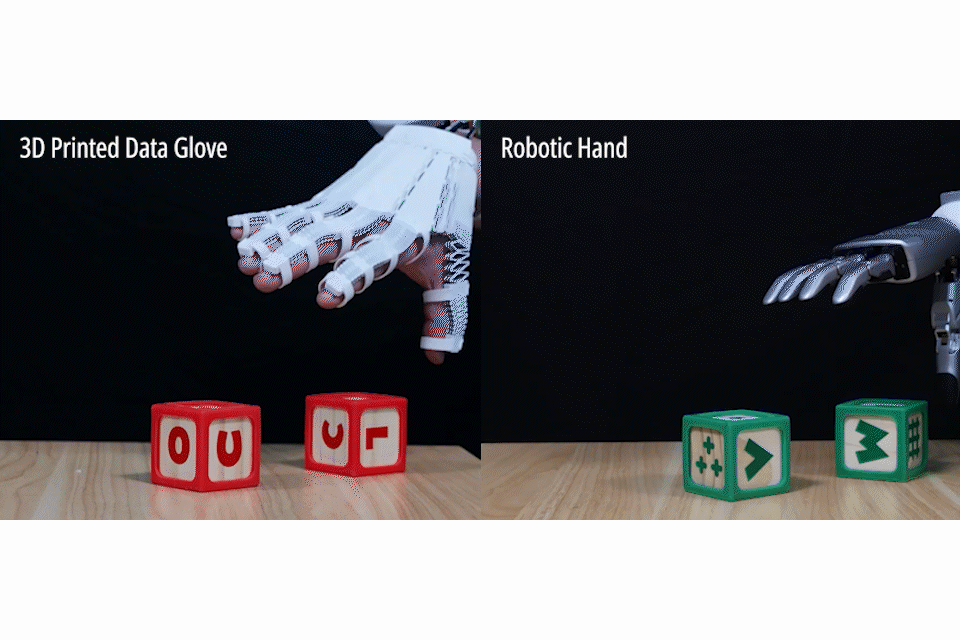
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
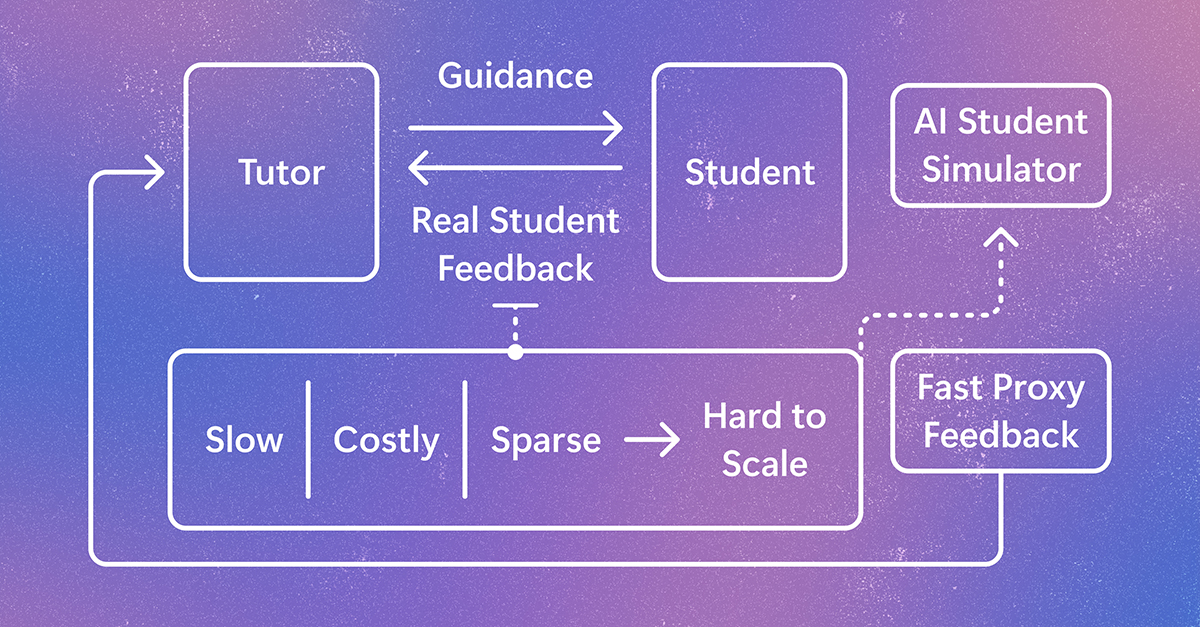
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.