FairLint-DL, a Visual Studio Code extension that implements a shift-left approach to fairness testing by enabling pre-training, IDE-native bias detection directly on tabular datasets, demonstrates the feasibility of integrating fairness analysis into the developer workflow without significant overhead.
Archit Rathod, Saeid Tizpaz-Niari· Proceedings of the 41st IEEE...· 0 citations
This article describes an open image dataset for developing and evaluating active-fire segmentation methods in satellite imagery. The dataset contains 2,148 image-mask pairs from 25 California wildfires, with acquisitions spanning July 2020 to August 2026. Each image is a 512x512-pixel, three-channel composite derived...
Shreyan Mitra, Mohammadreza Narimani, Parastoo Farajpoor· Data in Brief· 1 citation
A channel-informed neural network is introduced for physical-layer key generation that derives binary key features directly from received IQ measurements while explicitly grounding the learned representation in the underlying multipath channel.
Jose Angel Sanchez Viloria, G. Sklivanitis, D. Pados et al.· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
It is demonstrated that REVOLVE transforms real-world deployment into a closed-loop learning process that continually accumulates and uses execution experience, enabling continual evolution of both the policy and supervisory model with substantially less human intervention.
Han-Yu Liu, Qian Li, Yi-Zhu Ding et al.· 0 citations
LLMSuite is proposed, a hybrid test generation framework that integrates self-refinement prompting with class-level LLM reasoning into the search-based testing process and complements manually written test suites by exercising domain-specific behaviors that are often left untested.
Amirhossein Deljouyi, Annibale Panichella, Andy Zaidman· 0 citations
MatLAB-based software models of the matrix multipliers are developed for each architecture and validated for bit-level reproducibility against hardware using a randomized test suite consisting of 10 million sets of random input vectors.
Faizan A. Khattak, M. Mikaitis, Carlo Graziani· 0 citations
This study aims to determine the influence of Domestic Direct Investment (DDI) and Foreign Direct Investment (FDI) on Poverty through the labor force participation rate (LFPR) in districts/cities of East Kalimantan Province. This study uses a quantitative approach. The data used are secondary data obtained through publ...
L. Sari, Muhammad Bayu, A. Putri· Dinasti International Journa...· 0 citations
The deterministic machine-learning method for denoising candidate signals from all-sky searches for continuous gravitational waves from rotating neutron stars recovers the correct sky-position-dependent pattern for signal-to-noise ratios, demonstrating that deterministic diffusion-based denoising may serve as a consist...
It is shown that the best-performing compilation strategy varies across the tested circuits and network configurations, and that both network topology and intra-QPU connectivity substantially affect the entanglement cost of execution.
Luke Andreesen, Shobhit Gupta, Sean E. Sullivan et al.· 0 citations
These findings provide an empirical characterization of recurring security patterns across the open-source onboard satellite software ecosystem, helping quantify their prevalence and prioritize areas that warrant the greatest security attention.
Roee Idan, T. Galor, A. Shabtai et al.· 0 citations
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
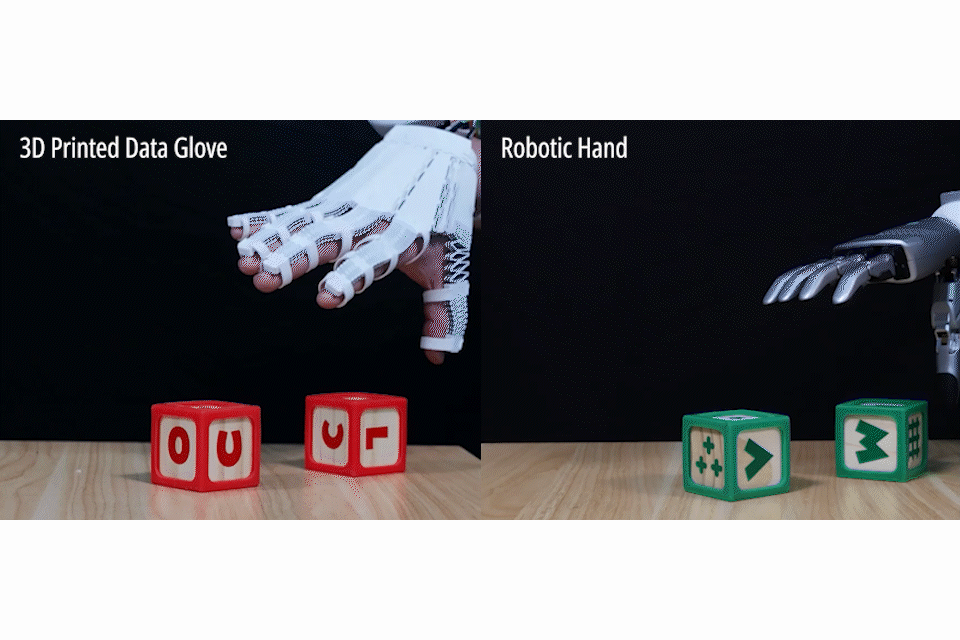
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
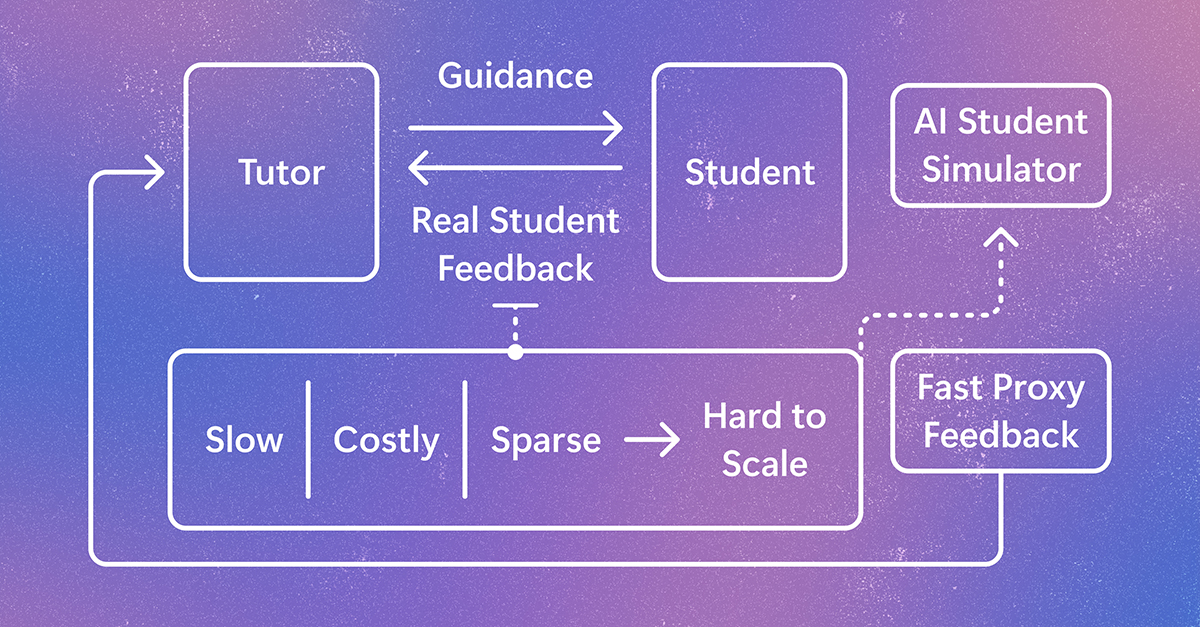
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.