Execution Governance for Physical AI v1.1.0 presents a cumulative EG1–EG6 research profile for governing consequential physical effects produced by robots, autonomous machines, smart spaces, vehicles, drones, industrial automation, and other cyber-physical systems. Physical AI moves AI-mediated decisions across a bound...
Ho Wa Ku· Zenodo (CERN European Organi...· 0 citations
Reproducibility scripts and data for the paper "The Naive–Power Law Blend as a Robust Baseline for Bitcoin Price Forecasting" by Carlos Baquero and Daniel Tinoco. This package contains all evaluation scripts, Bitcoin price data, and on-chain activity signals needed to reproduce the paper's results, including: the multi...
Carlos Baquero· Zenodo (CERN European Organi...· 0 citations
A methodology is given to choose an airfoil for a fixed wing UAV, and evaluate based on the mission constraints, and to efficiently optimize the airfoil by using multi-fidelity software such as XFLR5 and ANSYS FLUENT. The analysis solvers are validated for the wind tunnel test data of E387 and CAL2463m airfoil. Then, t...
Preety Kumari, Ashok Kuppusamy, Arnob Das Rudra· 0 citations
Code-only archive for the manuscript on the stability of machine-learning algorithm, feature and hyperparameter selection across random training-test splits in a coronary artery disease cohort. The archive contains selected analysis sources, recorded environment requirements, English-directory path-adaptation and prove...
Meng Li, Xiuze Zhang, Juan Bai et al.· Zenodo (CERN European Organi...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Code-only archive for the manuscript on the stability of machine-learning algorithm, feature and hyperparameter selection across random training-test splits in a coronary artery disease cohort. The archive contains selected analysis sources, recorded environment requirements, English-directory path-adaptation and prove...
Meng Li, Xiuze Zhang, Juan Bai et al.· Zenodo (CERN European Organi...· 0 citations
The developed framework is intended as a decision-support tool for pathologist support and screening and prioritisation of suspicious microscopic images and not as a replacement for slide-level diagnosis or immunohistochemistry.
Sourendra Nath Basu, J. Augustine, N. Chaudhary et al.· Journal of Microscopy· 0 citations
Regression testing in continuous integration (CI) helps preserve delivered software value by exposing regressions early, but limited feedback windows make test order consequential. This study evaluates a leakage-safe dynamic test case prioritization framework that reconstructs job–build–commit provenance, combines stri...
Abstract—Programming activities, such as automatic debugging and program repair, are increasingly being supported by Generative Artificial Intelligence (GenAI). However, a rigorous empirical evaluation of the efficacy of various large language models (LLMs) across several debugging phases is necessary. Using a benchmar...
Muhammad adrevi zaki rukmana, Sasmoko Sasmoko, Novtryananda M.S Ghunu et al.· Mendeley Data· 0 citations
It is suggested that while LLMs may offer support in structuring and initiating power analysis, they cannot substitute for expert judgment and underscores the importance of critically evaluating LLM performance in statistically demanding tasks.
Hajung Kim, Jia Qi, Zhe Feng et al.· Journal of Behavioral Data S...· 0 citations
The results demonstrate that EXCODER provides an effective, though imperfect, solution to this problem in automated code generation, offering developers the first way to implement ERC following test-driven development.
Ling-Tao Zhong, Jiyang Zhang, Jayanth Srinivasa et al.· 0 citations
This work presents a hardware-aware deep learning framework for multiclass detection of electrical faults and power quality disturbances in a 400 Hz aerospace power system, establishing simulation-based, accelerator-level feasibility for embedded edge AI in aircraft electrical health monitoring and motivating future en...
Ian Guzmán, R. Babiceanu, Berker Peköz· IEEE Transactions on Aerospa...· 0 citations
Ensuring the dependable operation of modern software systems under dynamic and non-stationary operating conditions remains a major challenge in software reliability engineering. Although recent deep reinforcement learning (DRL)-based approaches have demonstrated promising capabilities for closed-loop adaptation of soft...
Sudhakar Kambhampati, G. V. Krishna· Ceylon Journal of Science· 0 citations
Is your company’s AI sovereign? A practical guide for CIOs on AI vendor lock-in, EU Data Act switching, cloud sovereignty, and testing your exit plan before you need it. The post Sovereignty Is the Option to Leave appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comOct 30, 2026
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
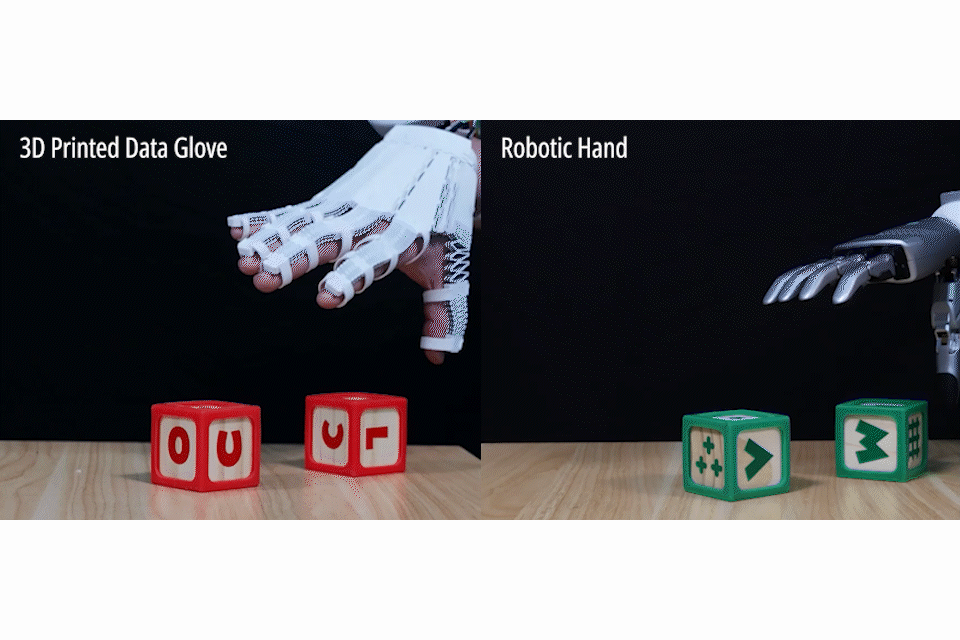
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.