This paper uses reinforcement learning and importance sampling to outperform previous work at all scales and reduces the logical error rate by 25.9\% and 71.7\% on average, respectively.
Abstract
A key subtask of quantum error correction is to extract a syndrome that, if nontrivial, signals an error. The number of possible ways to extract a syndrome grows exponentially with the syndrome size, and these implementations vary greatly in fault tolerance, as measured by their logical error rates. This creates a natural search problem: find an implementation with a low logical error rate. Previous work solves this problem but sacrifices either solution quality or scalability. In this paper, we use reinforcement learning and importance sampling to outperform previous work at all scales. Compared with the state of the art automatic scheduling tools AlphaSyndrome and PropHunt, our tool reduces the logical error rate by 25.9\% and 71.7\% on average, respectively, culminating with a reduction of 97.8\% for a surface code with distance 15.
This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
A weeklong summer workshop brought higher education faculty to campus to explore how AI and machine learning materials can be adapted for their classrooms.
MIT News · Artificial Intelligence· news.mit.eduAug 27, 2026
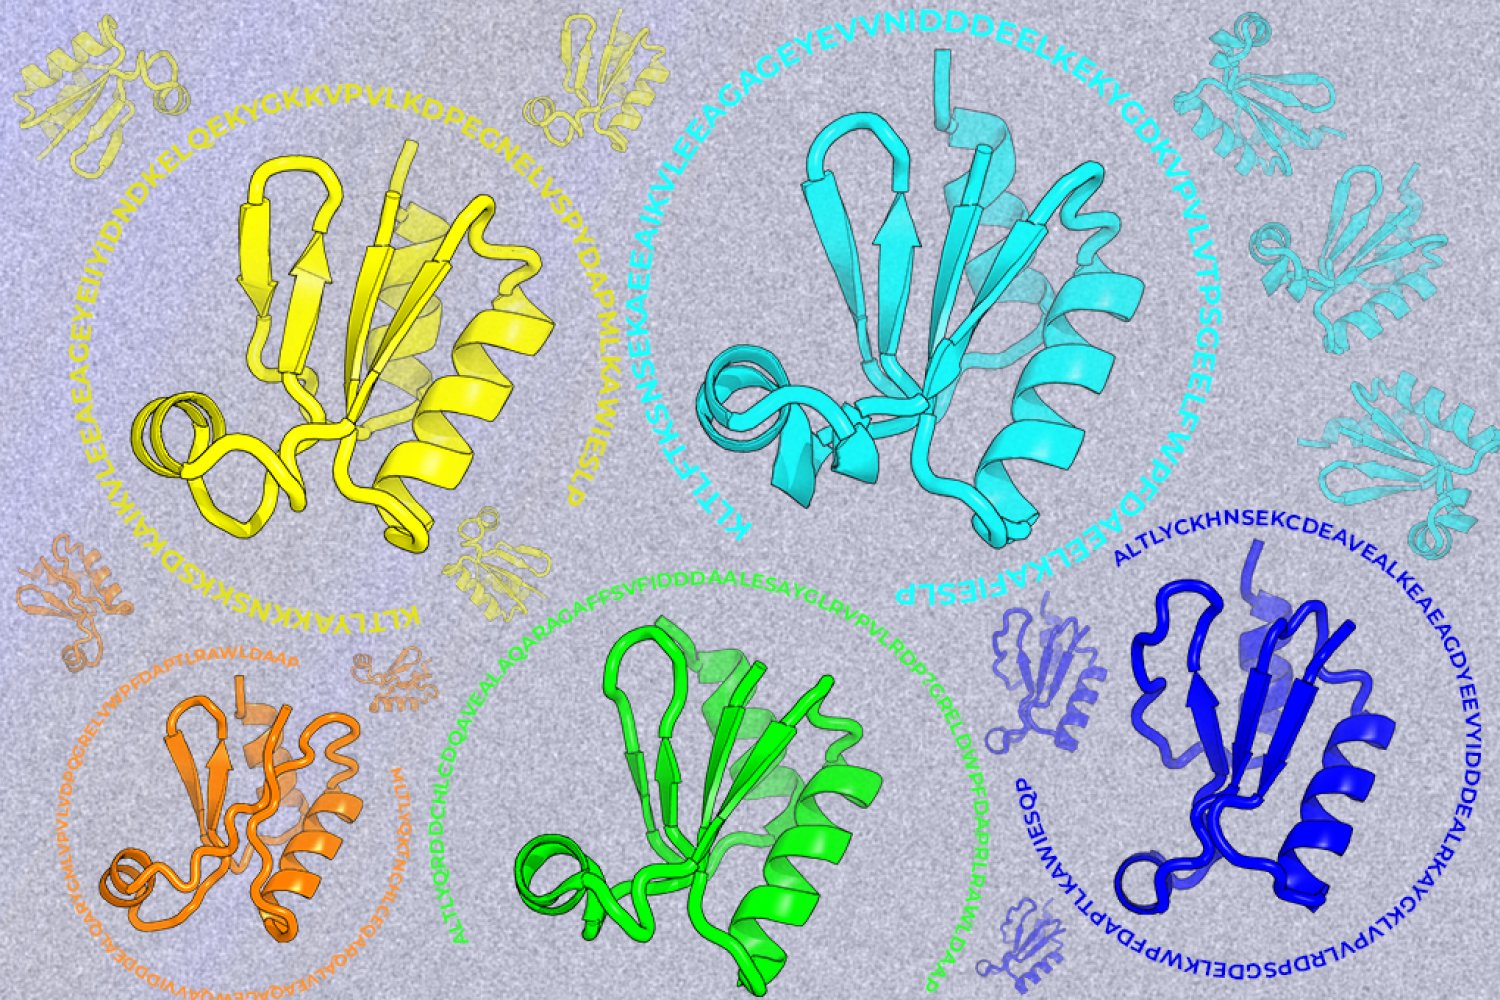
A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.
Microsoft Research Blog· microsoft.comAug 20, 2026
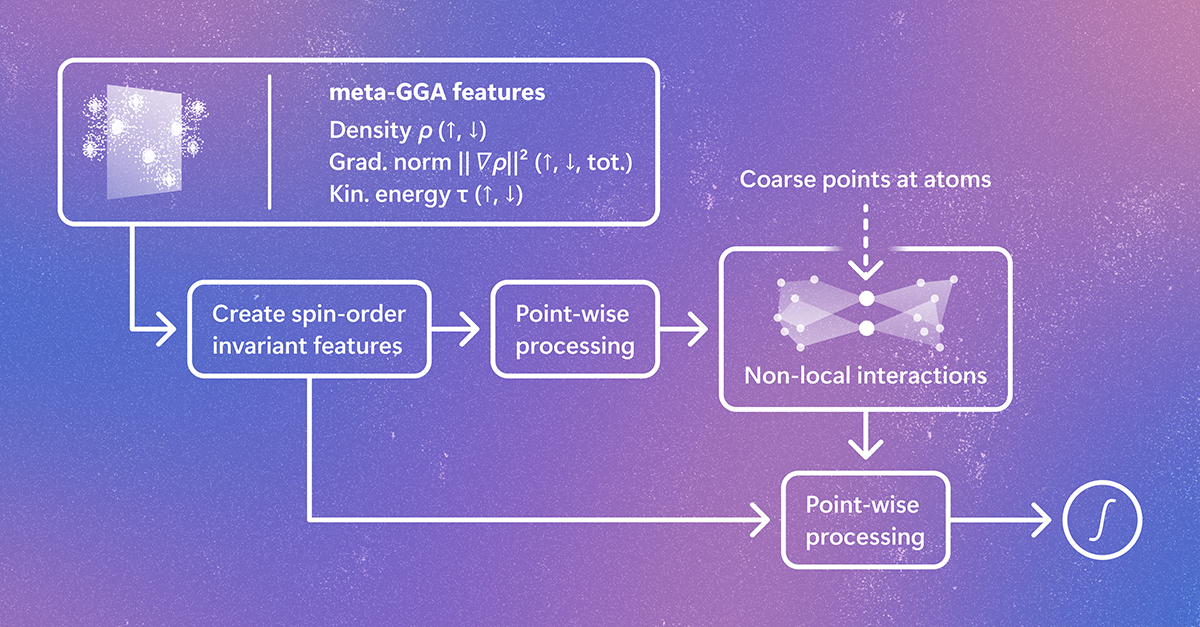
Skala 1.1, the updated deep-learning exchange-correlation functional from Microsoft Research, provides greater accuracy, expanded accessibility across the computational chemistry ecosystem, and a living benchmark to track computational performance. The post Broadening access to Skala creates a faster path to predictive DFT appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.