STAG is introduced, to the authors' knowledge the first post-hoc framework for token-level spectro-temporal grounding of captions generated by audio-based MLLMs, and provides behavioral support for the faithfulness and selectivity of the explanations.
Abstract
Audio-based Multimodal Large Language Models (MLLMs) can generate detailed natural-language descriptions of complex acoustic scenes, yet it remains unclear which parts of the input audio support each generated token. This is particularly challenging because acoustic evidence is distributed across time and frequency, and concurrent sound events may overlap temporally while occupying different spectral regions. We introduce STAG, to our knowledge the first post-hoc framework for token-level spectro-temporal grounding of captions generated by audio-based MLLMs. STAG estimates the temporal support for each generated token using target-token-specific vocabulary projections of the encoded audio representations, measures frequency-band relevance through controlled spectral occlusion, and combines the two signals into a spectro-temporal relevance map. We evaluate STAG against ten post-hoc explanation methods across four grounding benchmarks, where it achieves the best event-localization performance on every dataset, and apply it to eight audio-language backbones without parameter updates. Counterfactual deletion further shows that removing the identified evidence selectively reduces confidence in the corresponding event and frequently removes it from the regenerated caption. These results provide behavioral support for the faithfulness and selectivity of the explanations.

Large audio-language models can produce fluent and musically plausible responses, yet it often remains unclear whether those responses are grounded in the audio input. We introduce temporal music grounding, a task in which a model returns one or more time spans corresponding to a queried musical note, event, or pattern...
This work augments the LALM with a dedicated frame-level grounding model while leveraging its semantic modeling capability to represent the event query, and shows that the grounding model can provide temporal evidence to support downstream reasoning.
Mizar, a 159.3M-parameter ALM, is introduced, a recipe that brings together architecture, data, and three-stage training to build Mizar, a 159.3M-parameter ALM that surpasses the previous best-performing ALM below 200M parameters on all three benchmarks.
Kai-Yang Li, Shaobo Han, Yue Tian et al.· 0 citations
VGBench is introduced, a 1,018-item diagnostic benchmark for action-level addressedness across side-talk, self-talk, and speaker-switch scenarios that measures multi-cue acoustic-context gating rather than isolated speaker identity.
This work presents TEMPO (Temporally-grounded Multi-task Post-training), the first unified model to handle audio, speech, and music timestamping tasks and introduces the first application of reinforcement learning to unified audio timestamping, using GRPO with verifiable temporal rewards that directly optimize the eval...
Apoorva Kulkarni, Kaousheik Jayakumar, Sreyan Ghosh et al.· 2 citations
ST-Omni-R1 is proposed, which integrates FOA-derived semantic and trajectory representations with panoramic visual context and is trained through progressive curriculum learning and reasoning-tree reinforcement learning, and results on three public spatial-audio benchmarks indicate that its learned spatial and motion r...
Zhi Zeng, Cheng Zhang, Ze-Sheng Yang et al.· 2 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
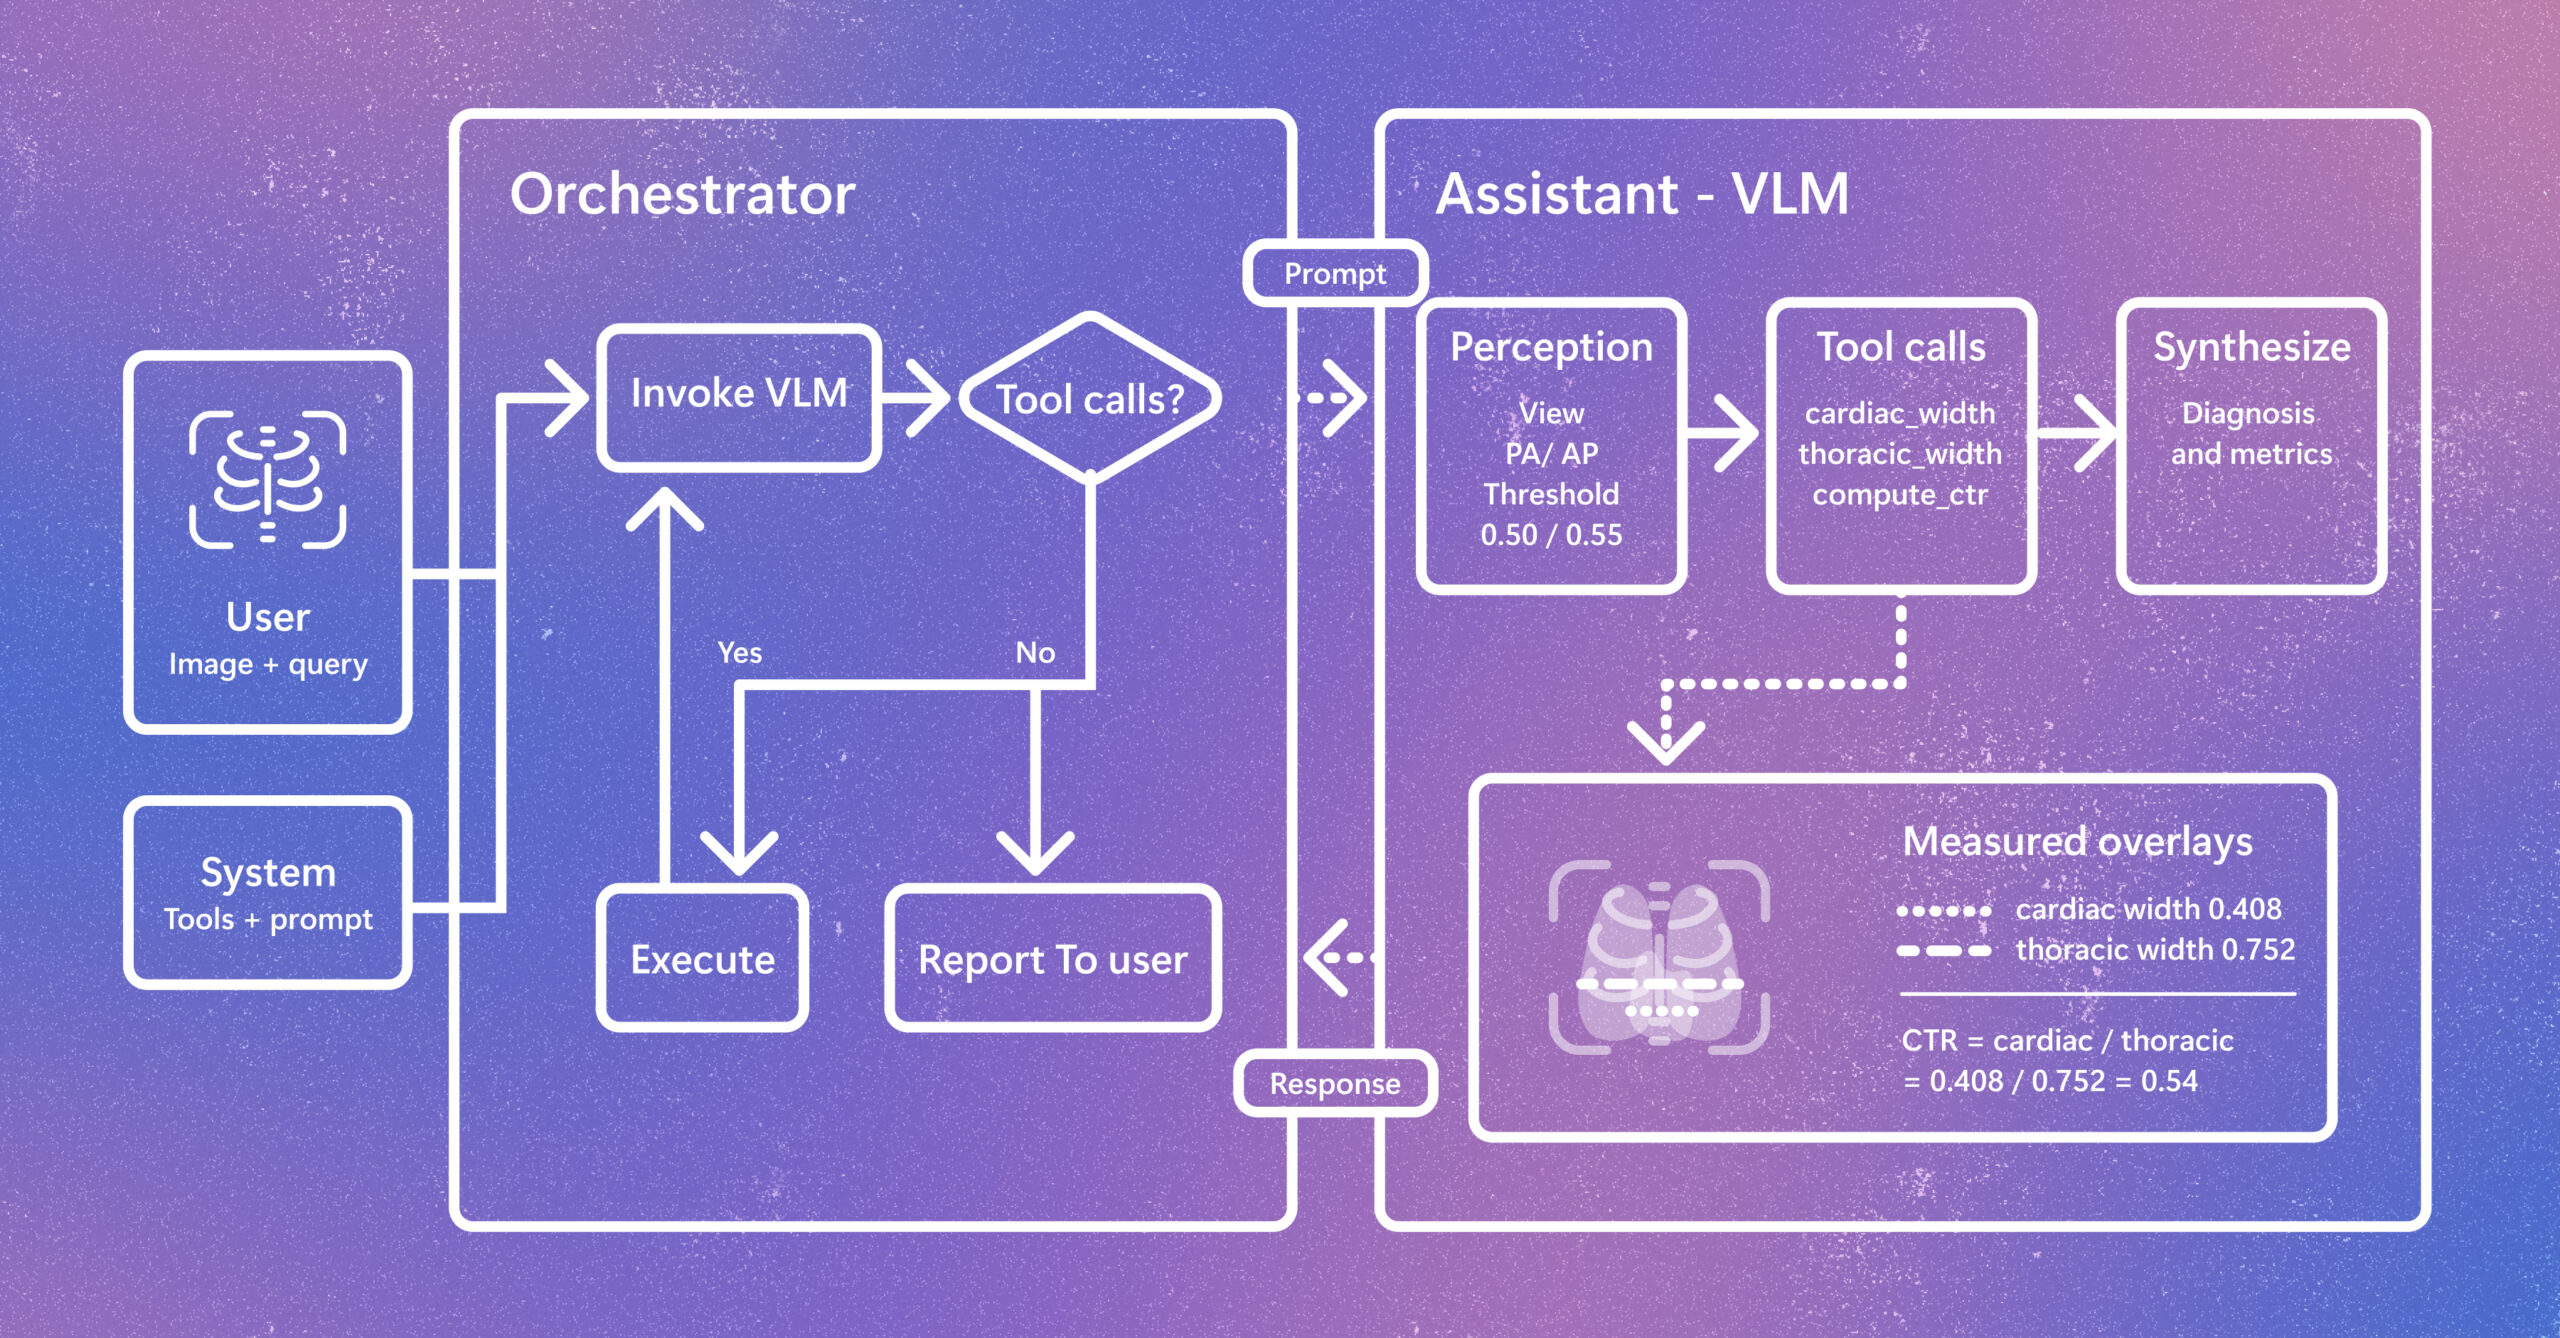
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.