Oct 2026· IEEE Transactions on Mobile Computing· Vol 25, pp. 17701-17713· 0 citations· 40 references
Abstract
Hybrid-float quantization has emerged as a promising solution for efficient deep neural network inference on mobile platforms, but its practical deployment is still limited by three challenges: compute–transmission imbalance, rapidly growing mapping complexity, and the tradeoff between intermediate-data movement and hardware cost under tight memory constraints. To address these issues, we propose a DRL-enabled polymorphic acceleration framework for hybrid-float inference in mobile computing. The framework integrates three tightly coupled modules: a Graph Builder that constructs a compute–transmission-aware parameterized DAG to expose workload imbalance, a ScaleCore Designer that provides a retargetable hybrid-float hardware template with flexible low-bit floating-point support and a three-level memory hierarchy, and a DRL Scheduler that jointly optimizes deployment and hardware-parallelism decisions under feasibility constraints and normalized multi-objective costs. Experiments on three FPGA platforms across complex CNNs and Bert show that the proposed framework achieves 16.36%–20.25% lower EPF or 19.92%–25.44% higher energy efficiency than state-of-the-art accelerators. These results demonstrate a practical path toward flexible, energy-efficient, and scalable hybrid-float deployment for future mobile intelligence systems.
This work analyzes the Vitis AI compiler and proposes an XIR-level splitting framework that generates independently compilable .xmodel fragments while preserving the context required for DPU mapping, and restores correct DPU mapping by addressing boundary-context loss and incomplete dependency collection.
Federico Buccellato, Luca Mannini, C. De Sio· WiPiEC Journal - Works in Pr...· 0 citations
With the rapid growth of deep learning models, compiler optimization for heterogeneous accelerators has become critical to improving execution efficiency. Compared with GPUs, Neural Processing Units (NPUs) offer stronger domain-specific computing capability but impose more complex on-chip resource constraints. Existing...
Jia-Nan Li, Lin Han, Xiao-Nan Chai et al.· IEEE Access· 0 citations
A flexible and scalable hardware/software framework for training CNNs on Ethernet-connected FPGA clusters using tightly pipelined layer parallelism, highlighting the potential of FPGA-based, layer-parallel training for separable-convolution-dominated CNNs.
Philipp Kreowsky, Justin Knapheide, B. Stabernack· ACM Transactions on Reconfig...· 1 citation
HDA-MoE is presented, a framework that optimizes MoE execution on NMP architectures through hybrid parallel deployment and runtime scheduling and integrates an offline hybrid parallel mapping algorithm with an online dynamic and adaptive scheduling mechanism to reduce communication overhead while improving computation...
Hao-Chen Huang, Shu-Zhang Zhong, Sheng-Xuan Qiu et al.· IEEE Transactions on Compute...· 0 citations
Machine learning inference is moving to the edge due to latency, energy, and privacy constraints. The growing complexity of edge workloads places increasing pressure on memory hierarchies, making data movement a major limitation for both performance and energy efficiency. Fixed-function accelerators inherit the memory...
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
MIT News · Artificial Intelligence· news.mit.eduJul 15, 2026
Assistant Professor Pat Pataranutaporn describes a new interface that lets everyday users glimpse inside an AI's neural network before their chatbot ever says a word.
Microsoft Research Blog· microsoft.comJul 13, 2026
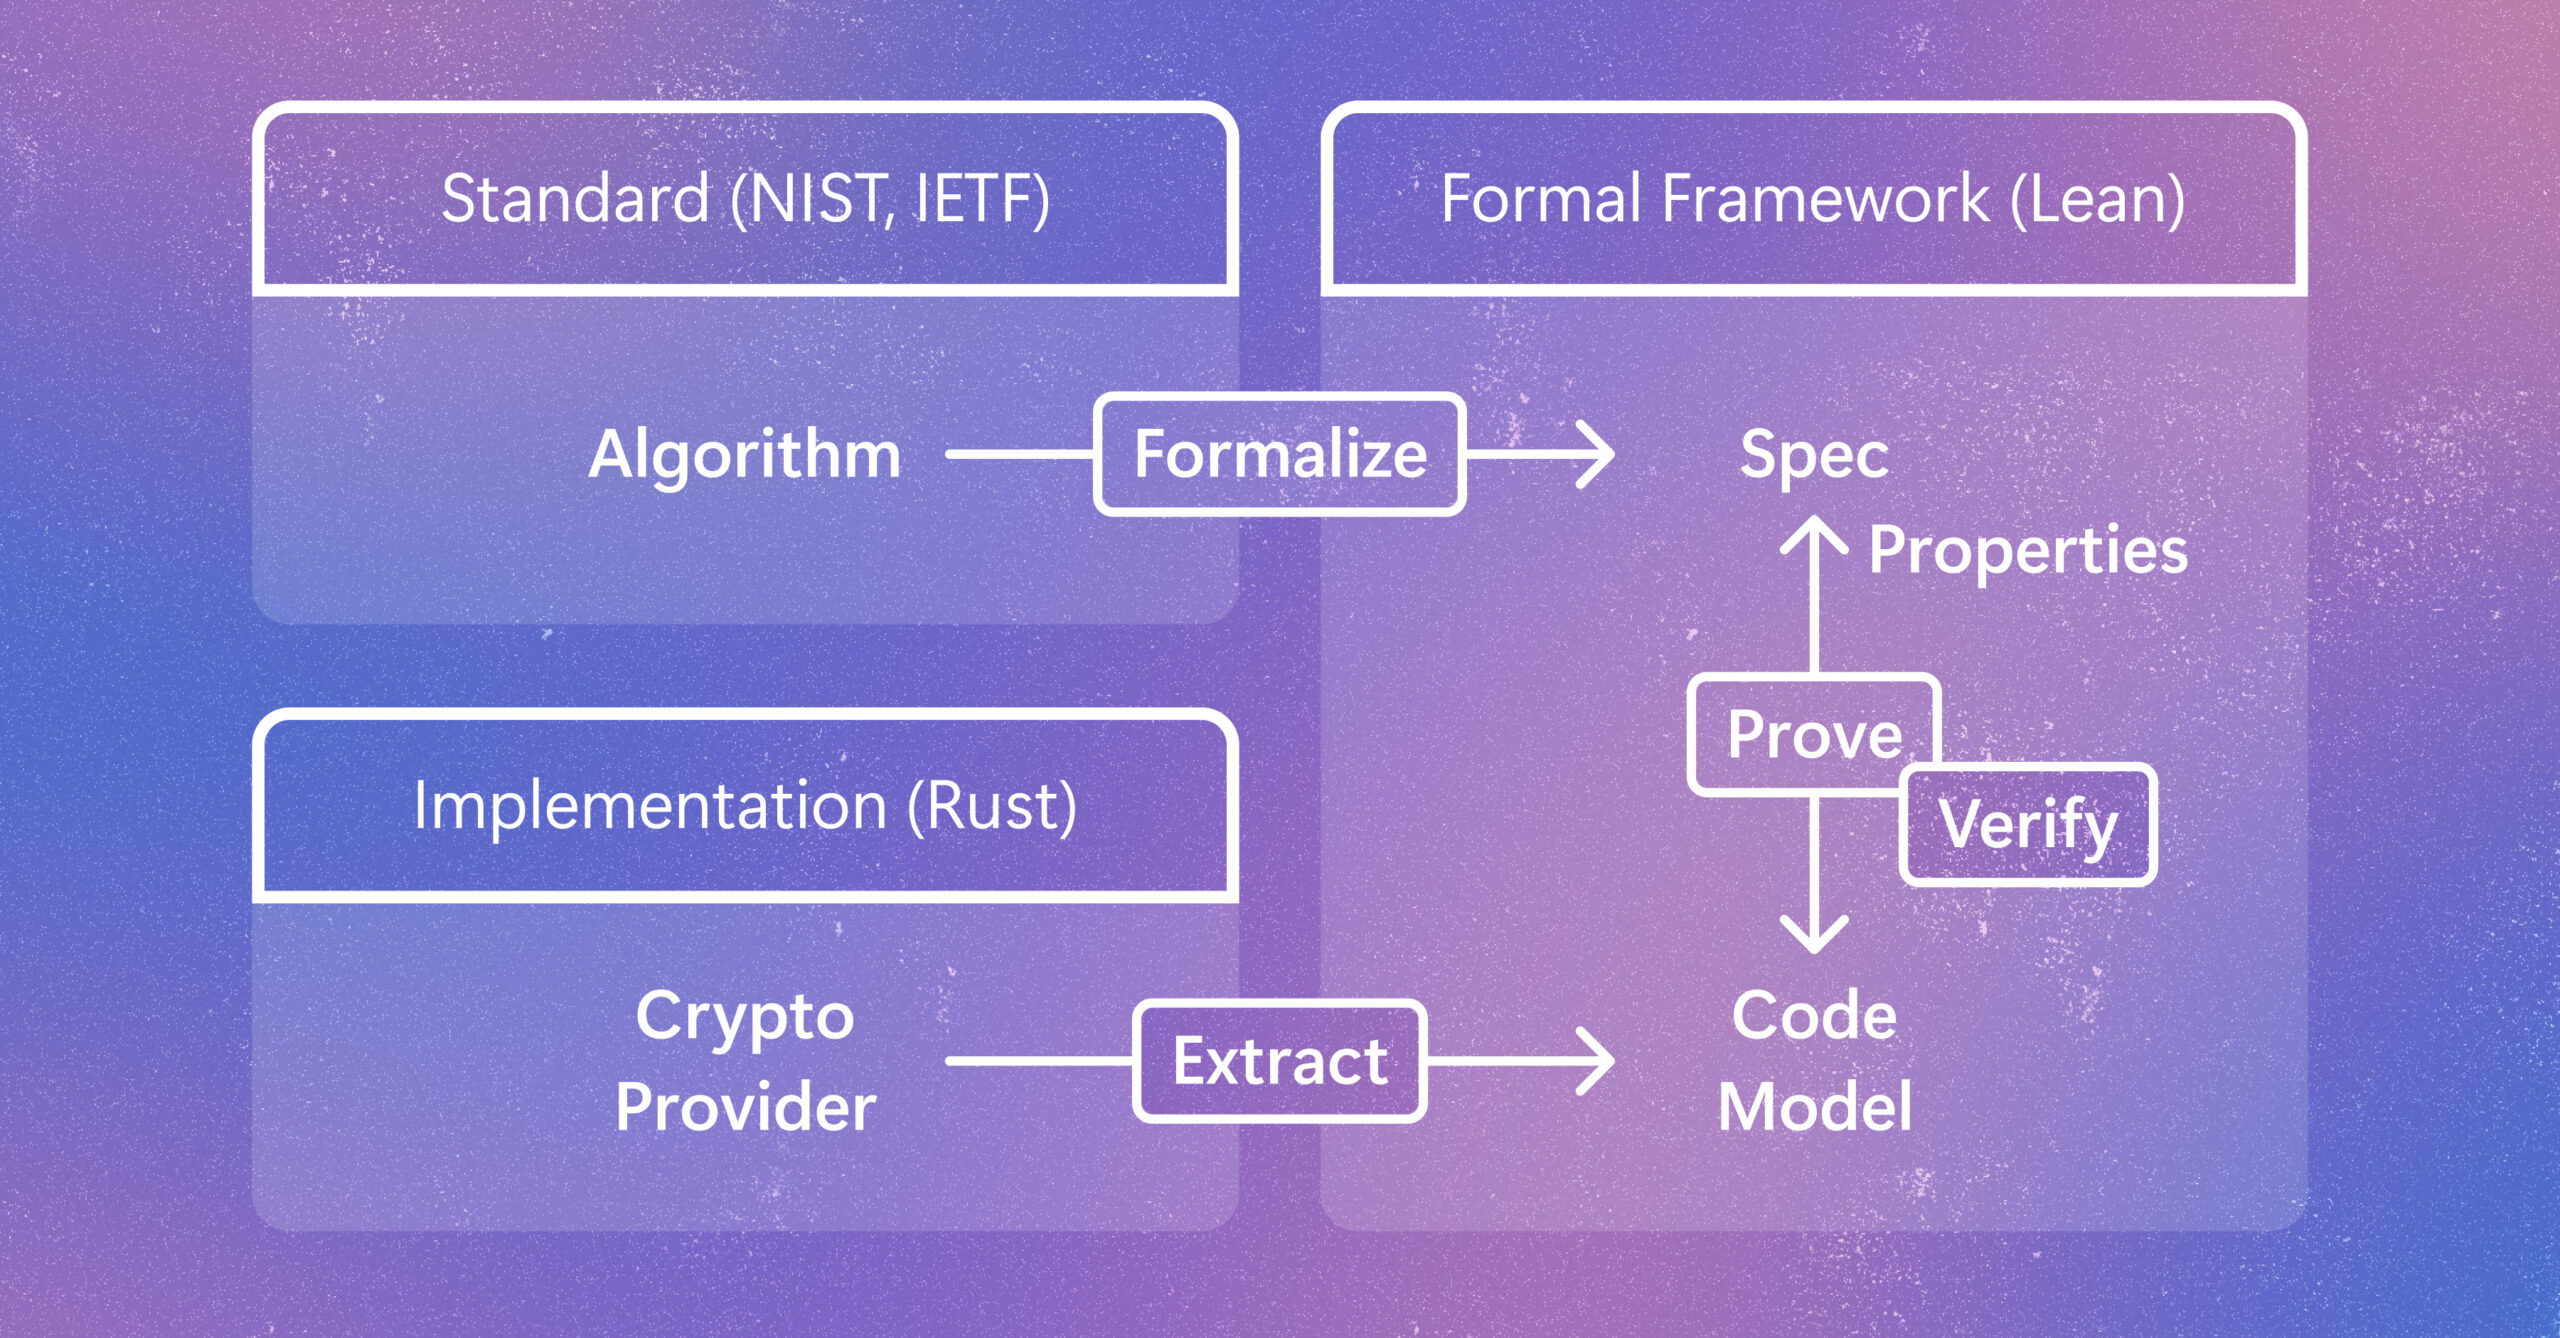
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.