The proposed TTIQ, a test-time reinforcement learning framework that harnesses image-question dependence for better vlm adaptation, combines image and question dependence with calibrated confidence to construct a response-level reward that favors jointly grounded responses.
Abstract
Test-time reinforcement learning can adapt vision-language models (VLMs) to unlabeled target data, but its effectiveness is fundamentally limited by the reliability of self-generated learning signals. To assess the reliability of consensus-based learning signals, we analyze VLM test-time reinforcement learning across diverse VQA datasets and model sizes, revealing two limitations. First, gains from consensus-based test-time training largely come from answer normalization rather than content correction. Second, many initial VLM responses are incorrect due to the model's limited ability to jointly use the image and the question; consensus rewards derived from these outputs may preserve the resulting grounding errors rather than correct them. Motivated by these, we propose TTIQ, a test-time reinforcement learning framework that harnesses image-question dependence for better vlm adaptation. TTIQ teacher-forces each sampled response under the original image-question pair and its image- and question-ablated variants, using the resulting token-level likelihood changes to estimate dependence on each input. It combines image and question dependence with calibrated confidence to construct a response-level reward that favors jointly grounded responses, and uses the token-level signals to assign greater positive policy credit to tokens supported by both inputs. This design favors responses that are jointly grounded in the image and the question and sufficiently confident, rather than merely popular. Experiments across eight VQA datasets and multiple VLM sizes show that TTIQ achieves the best average performance at every model scale. It further generalizes across VLM families, while models trained on one dataset improve performance on unseen datasets without further training.

TTRSD separates update direction from update position, determined by group-relative advantages, from update position, determined by visual sensitivity, without requiring ground-truth labels, external verifiers, or a separate teacher, demonstrating cross-dataset generalization while preserving inherent reasoning integri...
Shu-Ning Wang, Zhi-Heng Wu, Xun-Lan Zhou et al.· 1 citation
A label-free bias-only TTRL, which uses majority-vote pseudolabels as rewards and optimizes only ~100K bias parameters while keeping the pretrained backbone frozen, demonstrating that substantial test-time adaptation can emerge from optimizing a tiny bias-only subspace using entirely label-free rewards.
Noise-Contrastive GRPO is introduced, which injects scale-calibrated Gaussian noise into the last hidden layer of the prompt-encoding pass for half of each rollout group, branching those rollouts from a displaced departure state and integrates into a standard RLVR pipeline as a ~50-line change to the inference engine.
Michael M. Jerge, Joseph Pelczar, J. Downes· 1 citation
Anomalous video understanding aims to identify abnormal events in videos and interpret their semantic meanings beyond simple anomaly detection. Recent video large language models (Video-LLMs) have demonstrated promising zero-shot capabilities for this task, yet their performance remains limited due to insufficient adap...
Hui-Ning Li, Yu-Xiang Duan, Ji-Yang Tan et al.· 0 citations
PuRF is introduced, a novel PuRiFication-driven cache-based method for multi-label test-time adaptation of vision-language models that consistently outperforms state-of-the-art methods on ViT-B/32 across five datasets.
Yiwen Liang, Hui Chen, Yizhe Xiong et al.· 0 citations
Clue-OPSD, a clue-privileged on-policy self-distillation framework for long-video understanding that uses clue intervals as privileged supervision without relying on ground-truth answer labels, while requiring no clue annotations or additional modules at inference time is introduced.
Kai-Shen Wang, Dong-Di Zhao, Yijun Liang et al.· 6 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
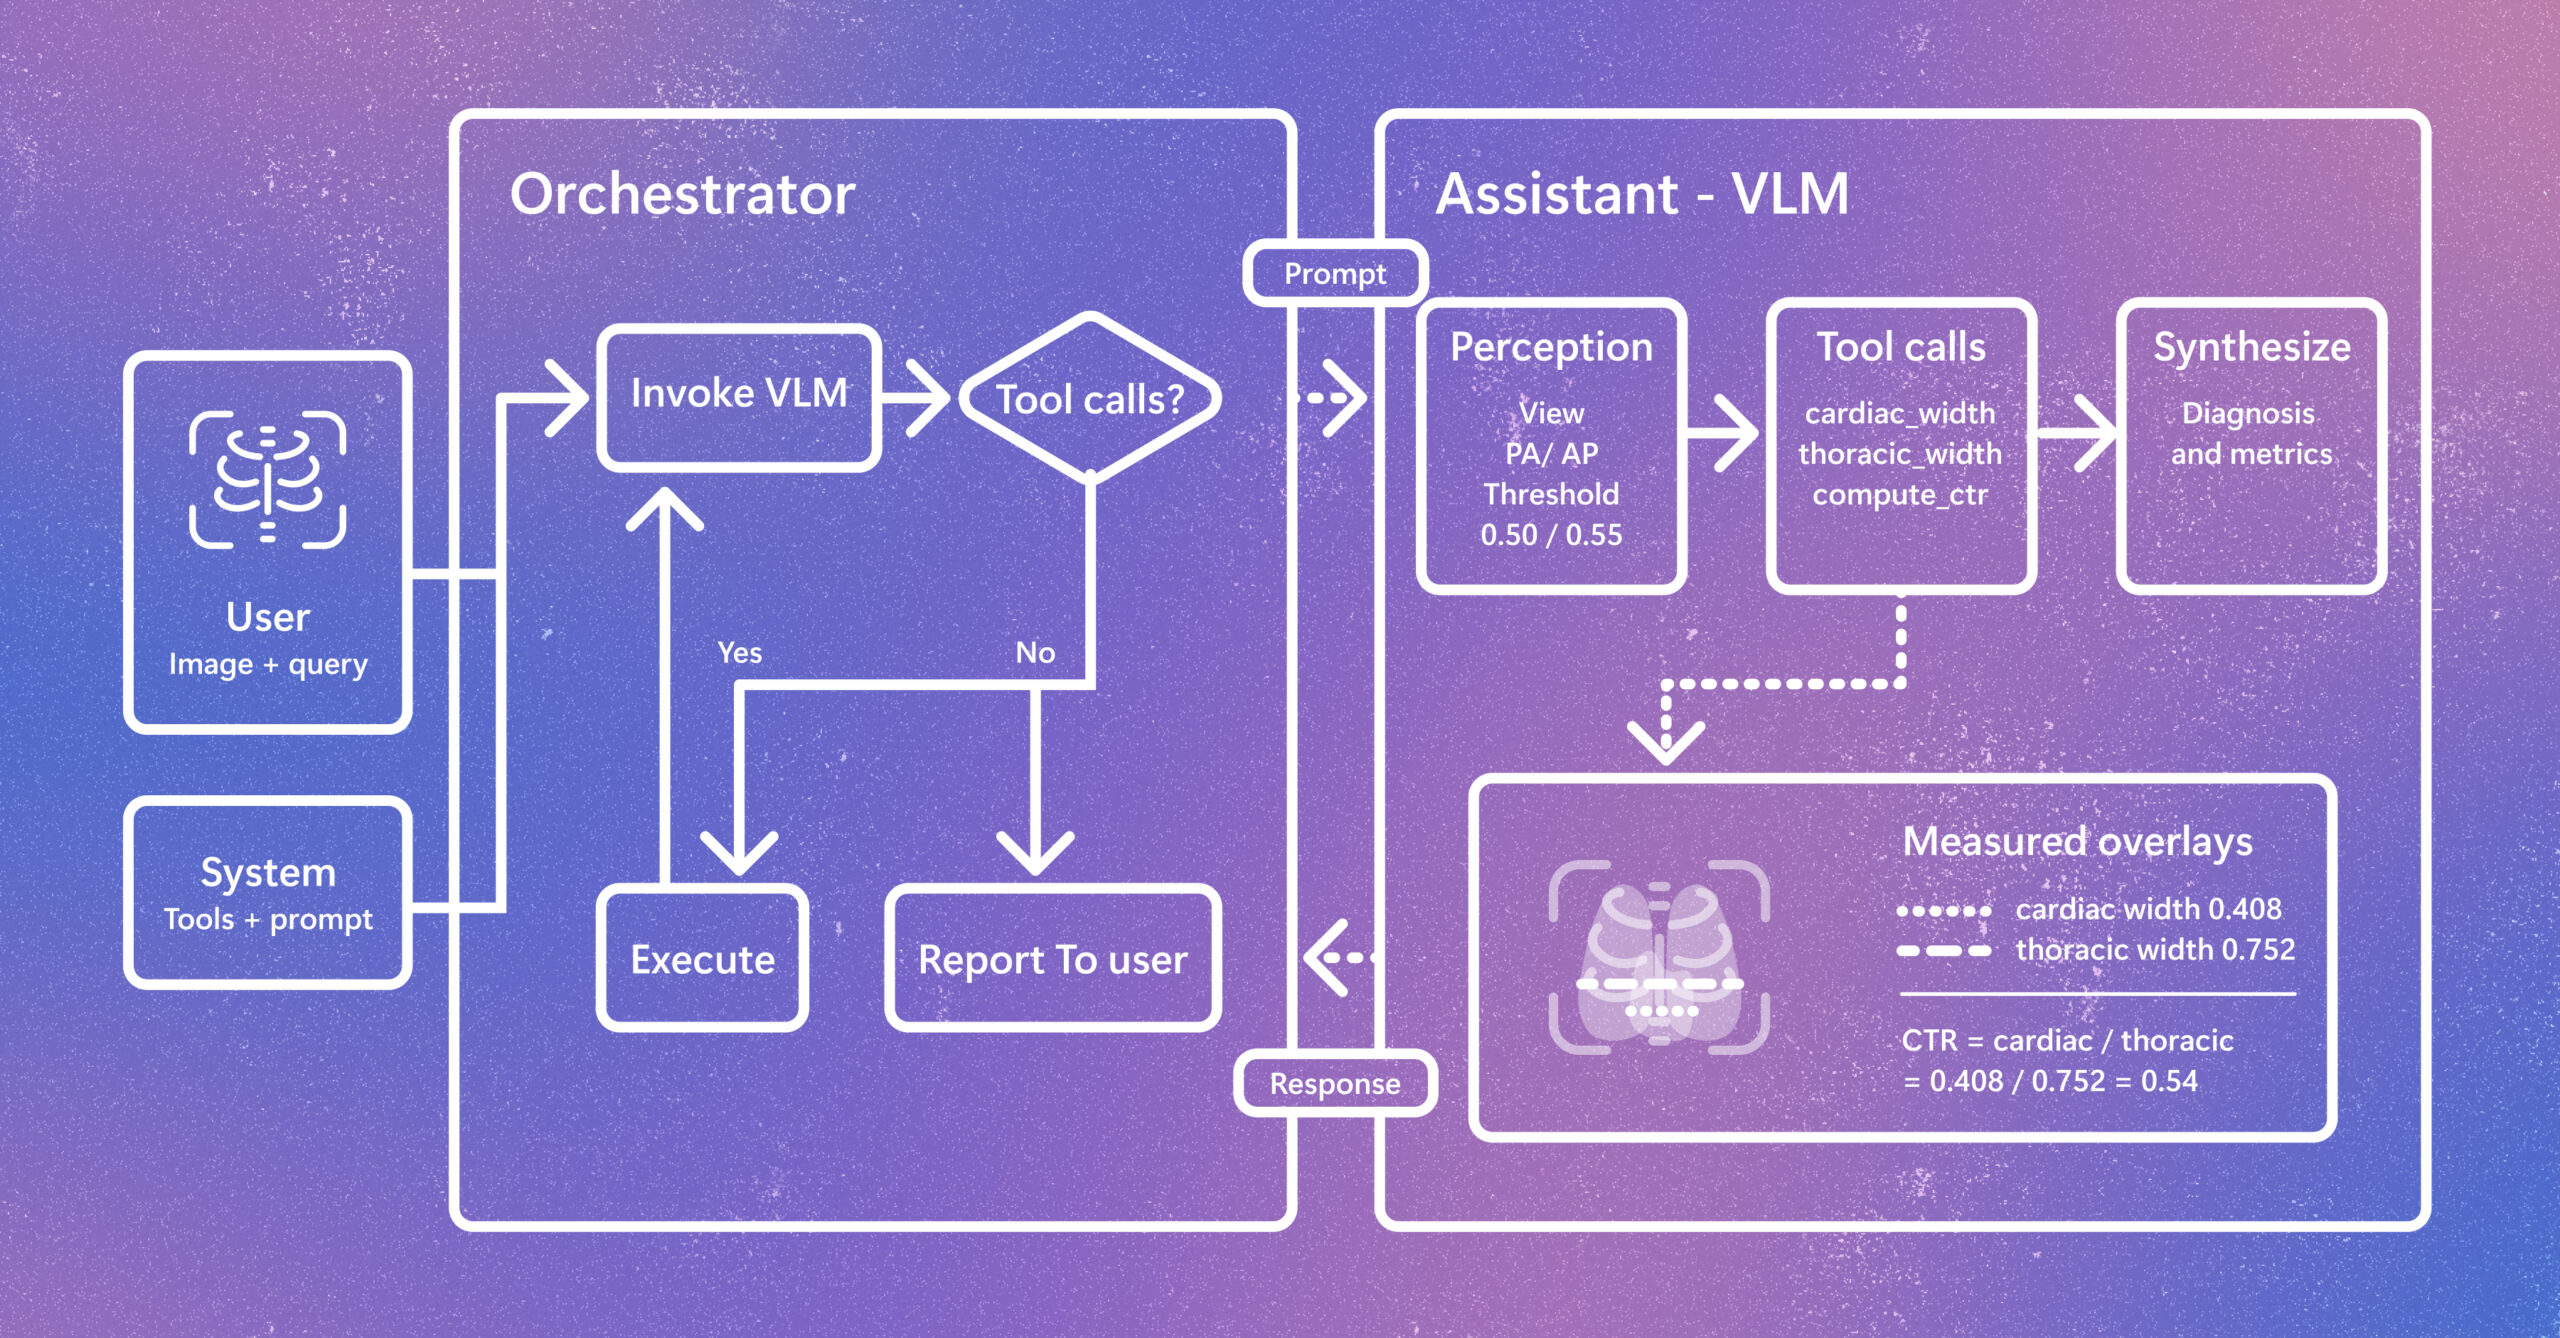
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.