PatchRisk is constructed, a leakage-aware benchmark from Open Source Vulnerability advisories and deps.dev dependency graphs for npm and PyPI that improves AUPRC over the strongest TimeOnly baseline and remains stable across smaller scales and package-group shuffle robustness tests.
Abstract
Open-source software ecosystems are web-scale dependency networks. A downstream package can become exposed to security risk not because its own source code changes, but because one of its transitive dependencies later receives a vulnerability advisory. Existing vulnerability-detection work often focuses on whether code is currently vulnerable or whether a known vulnerable dependency is already present. We study a different problem: future transitive vulnerability exposure. Given a package-version dependency graph observed at release time, the task is to predict whether any non-root dependency will receive a vulnerability advisory within a future horizon. This problem is important for Web intelligence and software supply-chain security because it supports proactive dependency triage before future exposure is visible. It is also easy to evaluate incorrectly: current vulnerable dependencies can leak the label, and different versions of the same root package can create package-level memorization across train and test splits. We therefore construct PatchRisk, a leakage-aware benchmark from Open Source Vulnerability advisories and deps.dev dependency graphs for npm and PyPI. The benchmark uses filtration-aware labels, package-disjoint evaluation, temporal testing, and nested 1K, 3K, 5K, and 10K sampling scales. The largest cleaned setting contains 9,007 root package-version graphs spanning 4,157 root packages. We evaluate three feature families: TimeOnly, GraphStruct, and HistoryGraph. On the 10K temporal-test benchmark, HistoryGraph improves AUPRC over the strongest TimeOnly baseline from 0.351 to 0.640 for 90-day forecasting and from 0.473 to 0.813 for 365-day forecasting. The improvement remains stable across smaller scales and package-group shuffle robustness tests.
VEX-Bench is introduced, the first benchmark for evaluating LLM agents'ability to assess the exploitability of software supply chain vulnerabilities, and contains 75 real-world cases mined from GitHub and labeled by security experts, covering Python, Java, and Go.
Jia-Hao Shi, Edward Tsien, Yi-Feng Di et al.· 1 citation
Software projects rely extensively on third-party libraries, but dependency versions with known vulnerabilities can expose them to security risks. Updating these dependencies is challenging because alternative versions may introduce different transitive dependencies, additional vulnerabilities, or compatibility failure...
Christian Macho, Laura Hofer, Martin Pinzger· Proceedings of the 1st Inter...· 0 citations
Modern software supply chains face increasing risks from vulnerable and anomalous dependencies, necessitating automated and interpretable detection methods integrated within Continuous Integration and Continuous Deployment (CI/CD) workflows. Open-source software (OSS) ecosystems are increasingly targeted by sophisticat...
A. Alzahrani, Muhammad Zubair Asghar· Scientific Reports· 0 citations
Software supply chain security has become increasingly critical due to the widespread reliance on third-party dependencies and the growing attack surface of modern software ecosystems. However, existing quantitative, measurement-based analysis and vulnerability management approaches remain largely fragmented and ecosys...
Sarah Meriem Ourari· IEEE International Conferenc...· 0 citations
Vulnerability patching is critical for safeguarding an enterprise's software ecosystem from cyber attacks. However, patching requires adequate preparation for potential system downtime and for unforeseen effects of the patched software on a live system. Thus, effective risk mitigation requires prioritization strategies...
Modern software heavily relies on code reuse, so upstream vulnerability fixes do not automatically propagate to downstream codebases. Downstream maintainers must manually adopt patches to eliminate known risks. In practice, a single vulnerability often corresponds to multiple patches, which greatly complicates downstre...
Yi Song, Dong-Chen Xie, Xiao-Yuan Xie et al.· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comNov 12, 2026
What's new in research at Microsoft? Host Anson Ho explores the latest, including AI-powered universal translation, a breakthrough in a 31-year-old mathematics challenge, and advances making AI coding agents faster and more efficient. The post Microsoft Research Focus – Edition #98 appeared first on Microsoft Research.
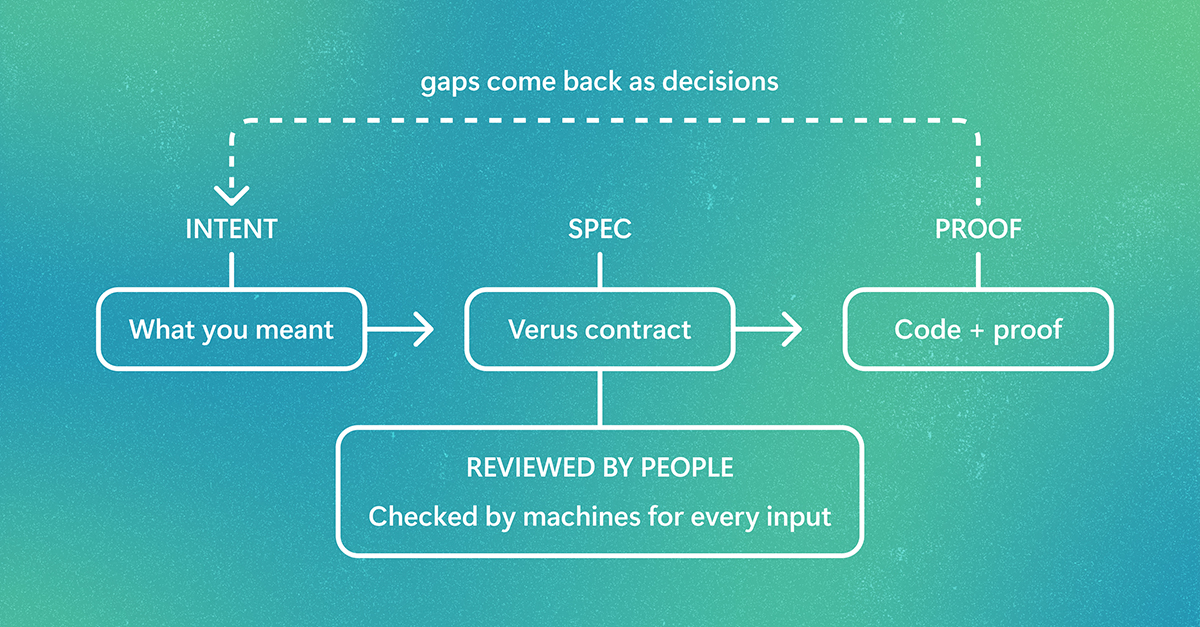
AI agents can generate code at a scale that’s hard for humans to review line-by-line. PDD Kit helps ensure the code is doing what the developer intended by creating formal specifications and testing against them. It converts developer intent into a Verus specification, proves AI-generated code meets it for every input, and uses tests where proofs aren't practical. Developers review intent, not every line. The post Formally verifying agent-written full-stack web apps with PDD Kit appeared first o…