Aug 2026· Journal of the Royal Society of Medicine· pp.
1410768261479691
· 0 citations· 38 references
Medicine
Abstract
This paper traces the historical development of frequentist sample size estimation from its philosophical origins to its present-day complexity. Preliminary concepts were identified by Christiaan Huygens' work on expected value and Jacob Bernoulli's law of large numbers, which first linked sample size and estimation accuracy. The 18th and 19th centuries brought major advances in probability theory through the work of Pierre-Simon de Laplace, Carl Friedrich Gauss and Siméon-Denis Poisson, yet explicit sample size planning remained uncommon. The early 20th century saw the emergence of methods for sample size calculations based on Jerzy Neyman and Egon Pearson's hypothesis testing framework and Sir Ronald Aylmer Fisher's experimental design principles. While Donald Mainland and Austin Bradford Hill referred indirectly to these as early as the 1930s, it took many decades before their explicit use became common. After the Second World War, contributions from figures such as Abraham Wald further embedded sample size planning with sequential methodologies. From the 1970s onward, standardised formulas, regulatory requirements, reporting standards such as CONSORT and statistical software consolidated frequentist sample size estimation as a routine component in applied research. In the 21st century, simulation-based, adaptive and Bayesian approaches, together with open-source computational ecosystems, have expanded the scope and accessibility of sample size methods. In contemporary research, sample size estimation has evolved into a multifaceted discipline; its methodological sophistication is contingent upon the underlying objective, illustrating the persistent divergence between explanatory inference and decision-oriented design.
Bahadur's \emph{Lectures on the Theory of Estimation} develop the classical theory of point estimation inside the geometry of Hilbert space, and they record with unusual honesty where the theory strains: the locally best unbiased estimate depends on the parameter, a two-point parameter space yields an estimate Bahadur...
Distribution goodness-of-fit testing has developed a powerful rate-level theory: we often know how the required sample size scales with the alphabet size, the separation from the null, and the target error probability. Uniformity testing is the canonical example. One can distinguish the uniform distribution on $N$ cate...
This study quantifies the material distortions in empirical return distributions caused by finite samples and overlapping returns, raising caution about the reliability of raw historical simulation for risk management. We aim to provide actionable guidance on when historical data can be informative and when it may...
R. M. Gaspar· The Journal of Risk Finance· 0 citations
We study causal inference in interrupted time series designs where a treatment affects every unit simultaneously, so that the contemporaneous controls used by difference-in-differences and synthetic control are unavailable and the counterfactual must be extrapolated from a unit's own pre-treatment history. We establish...
In this work, we study the problem of testing conditional independence between random variables $X$ and $Y$ given a confounder $Z$. The local permutation test (LPT) offers a principled approach to this problem by partitioning the $Z$-space into pre-specified bins, and permuting the $X$ and $Y$ data within each bin, to...
David Chen, Rohan Hore, Rina Foygel Barber· 0 citations
The paper provides a brief overview of publications related to the division of the initial data sample into disjoint fragments when modeling complex objects. In particular, there is considered distributed asymmetric least squares estimation based on a Poisson subsample; a new methodology for the structural synthesis of...
S. I. Noskov, V. A. Telenkov· Informatika i sistemy upravl...· 0 citations
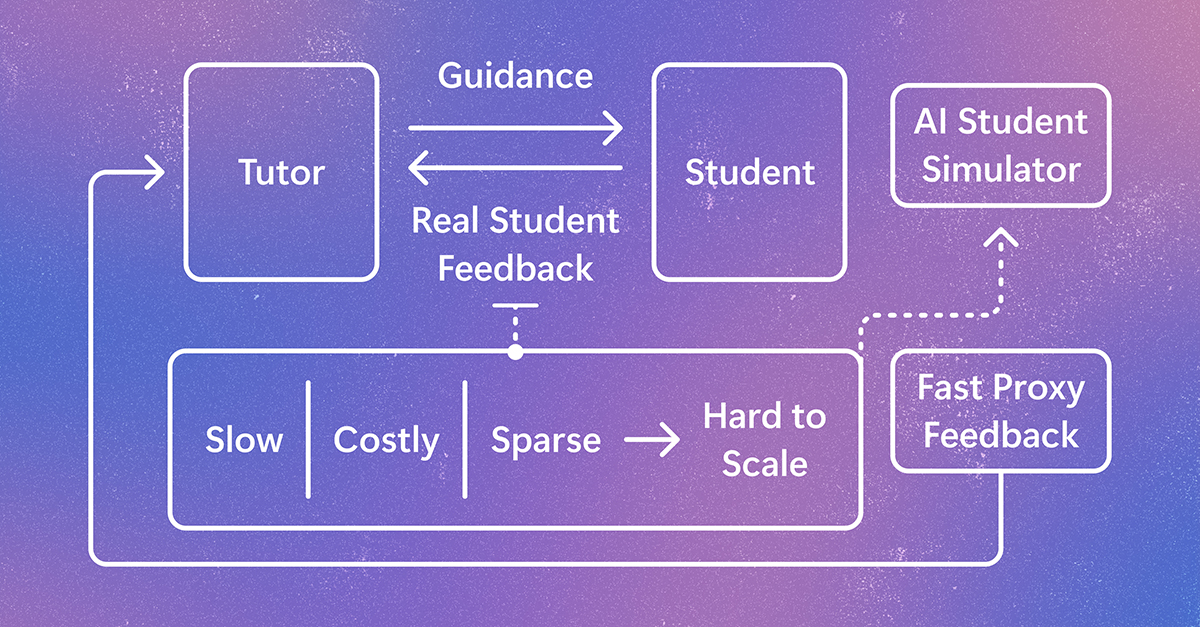
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 6, 2026
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.