In this work, we study the neural scaling laws of RydbergGPT, an autoregressive transformer model trained on qubit projective measurement data gathered from interacting Rydberg atom arrays. The quantum system is known to exhibit a finite-size remnant of a critical point as the laser detuning parameter is varied. We find that near the critical point the transformer loss as a function of training dataset size is well described by a power-law with a loss floor correction. However, away from criticality the quality of the power-law description is substantially reduced. We then compare the statistical structure of both Rydberg measurements and natural-language corpora using an entropy-normalised, finite sample corrected mutual information"two-point"function. We find that near-critical statistics of the two point functions are closest to those observed in natural-language, whilst other qubit configurations far from the critical point have two-point functions that decay more rapidly. This supports the hypothesis that multi-scale dependence contributes to stable neural scaling, and that scaling behaviour should be viewed as a property of the model-data pair.
Multi-shift SR (MS-SR), which averages independent ridge solves at data-adaptive shifts to form a richer, lower-variance spectral filter, is shown, which lowers validation risk and update variance relative to the fixed-shift SR baseline.
The redundancy distribution of the frequency spectrum has been shown in the literature to impact the expressivity and trainability of Quantum Fourier Models (QFMs). In this work, we address the question of how this redundancy spectrum is shaped by the choice of eigenvalues of the data re-uploading Hamiltonians, using a...
Felix Paul, Bhilahari Jeevanesan, Peter Jung· 0 citations
A hybrid quantum model for recovering the damping coefficient of an underdamped harmonic oscillator from sparse noisy observations is studied, showing that both data and physics terms are needed, that circuit-depth effects are regime dependent, and that the observed ranking is robust to the tested observation-noise and...
Thanh (Tim) Nguyen, Hiep L. Thi, Thi Tran Luong· International Journal of Mod...· 0 citations
This work proves convergence of the channel's outputs to a QGP and derive the associated closed-form kernel under a uniform (Lebesgue measure) prior over quantum channels and proposes an empirical Bayes heuristic that replaces the dimensional factor with a learnable scale parameter while retaining the kernel's state-ov...
J. Jäger, Yaroslav Khmelnitskiy, Paolo Braccia et al.· 0 citations
How many directions in weight space does training need? The intrinsic dimension answers this with the smallest number of random directions in which training still reaches a target accuracy, and small values have motivated parameter-efficient methods such as LoRA. We measure it for variational Monte Carlo (VMC), which t...
Lu Wei, Yu-Feng Wang, Chen-Feng Cao et al.· 0 citations
The results show that a single bosonic mode can exhibit exponential quantum learning advantages without entanglement or an increase in system size, identifying accessible Fourier bandwidth as a fundamentally distinct resource for quantum-enhanced learning.
A. A. Baiju, Aritra Das, Ozlem Erkilic et al.· 2 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 2, 2026
A weeklong summer workshop brought higher education faculty to campus to explore how AI and machine learning materials can be adapted for their classrooms.
MIT News · Artificial Intelligence· news.mit.eduAug 27, 2026
A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.
Microsoft Research Blog· microsoft.comAug 20, 2026
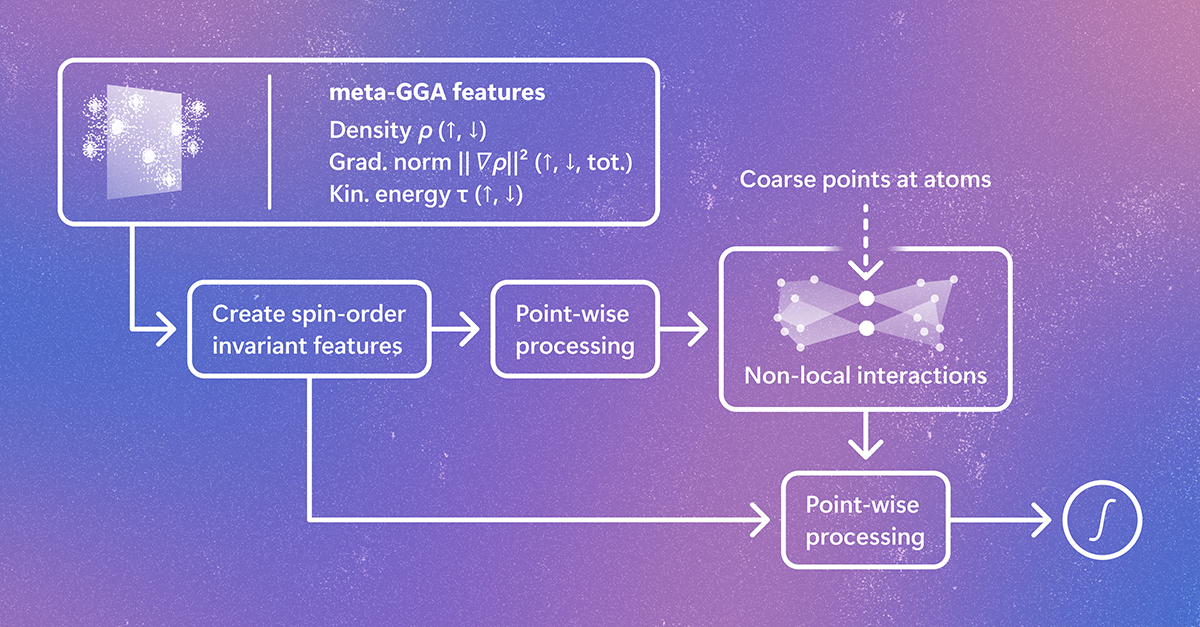
Skala 1.1, the updated deep-learning exchange-correlation functional from Microsoft Research, provides greater accuracy, expanded accessibility across the computational chemistry ecosystem, and a living benchmark to track computational performance. The post Broadening access to Skala creates a faster path to predictive DFT appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.