IntBMoE is a block-conditioned MoE that decouples all three by pairing dense expert composition with sparse block execution, and shows consistent gains over representative sparse and dense MoE baselines on image classification.
Abstract
Mixture-of-Experts (MoE) scales capacity, but existing designs cannot set three quantities independently. For a single token, participation is how many experts contribute knowledge to its output, execution is how many are actually computed (compute cost), and materialization is how many expert-sized parameter sets must be built and stored (memory cost). Sparse routing keeps execution and materialization low, but shrinks participation: for each token, only a few experts contribute. Dense output-mixing restores full participation, but its execution grows with the number of experts. Parameter-merging keeps execution at one expert, but its materialization grows with the number of routing decisions. We propose IntBMoE, a block-conditioned MoE that decouples all three by pairing dense expert composition with sparse block execution. Its blocks come from a small learned codebook, one per entry. At each internal layer, a lightweight hypernetwork merges all expert bases in that layer's pool into one composed expert. Participation is full, because every composed expert draws on the entire pool. Execution stays sparse, because a router sends each token to only a few blocks. Materialization is bounded, because the codebook, not the input, fixes how many blocks exist. Dual-Path Residual Gating (DPRG) further couples two independently composed paths through multiplicative gating. Experiments on image classification show consistent gains over representative sparse and dense MoE baselines. Additional experiments on language modeling and sequential recommendation validate its generalization beyond vision. IntBMoE is fully deployed in AMap's generative recommendation system, serving hundreds of millions of users under a 60ms latency budget, with a 2.4% relative UVCTR gain in online A/B testing. Our code is available at https://github.com/AMAP-ML/DreamX-Rec/.

MetaNet is proposed, a support-set controller that predicts, for each layer, an expert-retention threshold and a bounded routing bias and provides a tunable accuracy-expert-activation trade-off on DeepSeek-MoE-16B-Chat.
Rong-Feng Wang, Shitao Weng, Zhiquan Wang et al.· 0 citations
This work introduces RAPTOR - a Role-Aware Private Training framework, which alternates shared and expert optimization and targets each failure directly, using expert-specific clipping and noise together with a public expected-owner denominator and a count-independent update schedule that avoids conditioning on private...
Duc Dm, Khai Le-Duc, D. Nguyen et al.· 0 citations
RAZOR, a training-free pruning method based on consensus residuals, the deviations of expert outputs from their original weighted mixture, gives the exact output change for a single deletion under survivor renormalization and router refill.
UniMoMo, a post-training compression framework formulated as a constrained graph coarsening problem, is introduced, and a layer-adaptive protection mechanism that restricts the merging of high-traffic experts based on their routing exposure is introduced.
A cross-architecture distinction between expert selection and expert commitment is supported betweenparse Mixture-of-Experts (MoE) routers and DeepSeek-V2-Lite, which uses Top-6 routed experts plus shared experts.
Scratchpad-Augmented Mixture-of-Experts (SA-MoE), which gives each router access to a low-dimensional persistent state that is not provided to the experts, which makes one routing-specific computational history explicit and directly inspectable within the model's natural forward computation.
Abdurrahman Javat, A. Kazakov· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
Microsoft Research Blog· microsoft.comOct 12, 2026
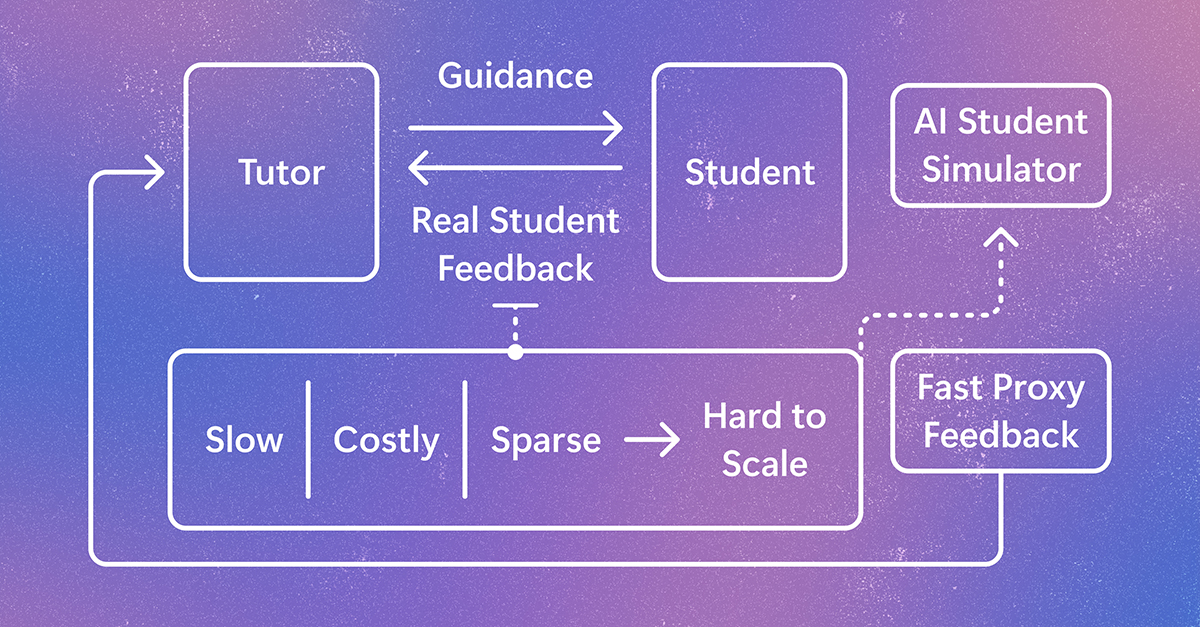
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.