It is shown that ASR errors lead to significant safety risks for embodied AI, and automatic correction of ASR errors can reduce the risk, but this is not always effective.
Abstract
We investigate whether automatic speech recognition (ASR) errors in user input can lead to unsafe outputs from Embodied AI (EAI) models. We find that ASR errors can lead to harmful instructions being accepted and executed by EAI models, thereby reducing safety. We simulate ASR errors and combine them with existing safety benchmarks (SafeAgentBench and POEX) to evaluate how different errors affect embodied AI safety. We find that some of them preserve semantic structure but increase harmful ambiguity, while others weaken the model refusal behaviour and allow unsafe plans to be generated and executed. We show that in some cases automatic correction of ASR errors can reduce the risk, but this is not always effective. Overall, we show that ASR errors lead to significant safety risks for embodied AI.
SafeBranch is proposed, a framework that aligns an embodied actor on safety through branch pairs constructed from the actor's own unsafe rollouts via environment rollback, achieving roughly ten times more safe successes than the untrained baseline on the unseen-object variant.
Hyunse Lee, Jiwoo Jeong, Haneul Lee et al.· 0 citations
General purpose language models are increasingly able to control robotic hardware. Understanding the capabilities and safety of these models when embodied is therefore increasingly important for understanding their societal impact and risks. To this end, we introduce Inspect Robots, a modular, open-source framework for...
Christopher Leet, Achu Menon, Sravanthi Machcha et al.· 0 citations
Embodied agents powered by large language models and vision-language models are increasingly deployed in physical environments, but jailbreak attacks can induce these agents to perform physically harmful actions. A growing number of guardrail methods have been proposed to intercept dangerous behavior before it is execu...
Xun-Guang Wang, Qing-Yue Wang, Yu-Guang Zhou et al.· 0 citations
Vision-language-action models (VLAs) act on instructions without being able to refuse, so screening harmful requests falls to monitors. We test whether these monitors catch ordinary robot tasks requested for harmful reasons, holding the task fixed while varying only how explicitly the intent is stated. $\pi_{0.5}$ comp...
SafeLoop is introduced, a non-invasive external wrapper that adds hazard prediction and rollback-based recovery to a VLA model without changing its parameters, and achieves a stronger overall safety-success trade-off than alternative methods.
Zeyuan Lou, Tian-Ran Zhang, Xin-Quan Yue et al.· 0 citations
Everyday objects, whether placed by an adversary or introduced by ordinary rearrangement of the environment, are thus sufficient to overturn a refusal, and susceptibility to safety bypass is called a property of the task, which it is shown that it can be predicted before the target is ever queried.
Leon Lin, Mikhail Kuznetsov, Muslum Ozgur Ozmen et al.· 0 citations
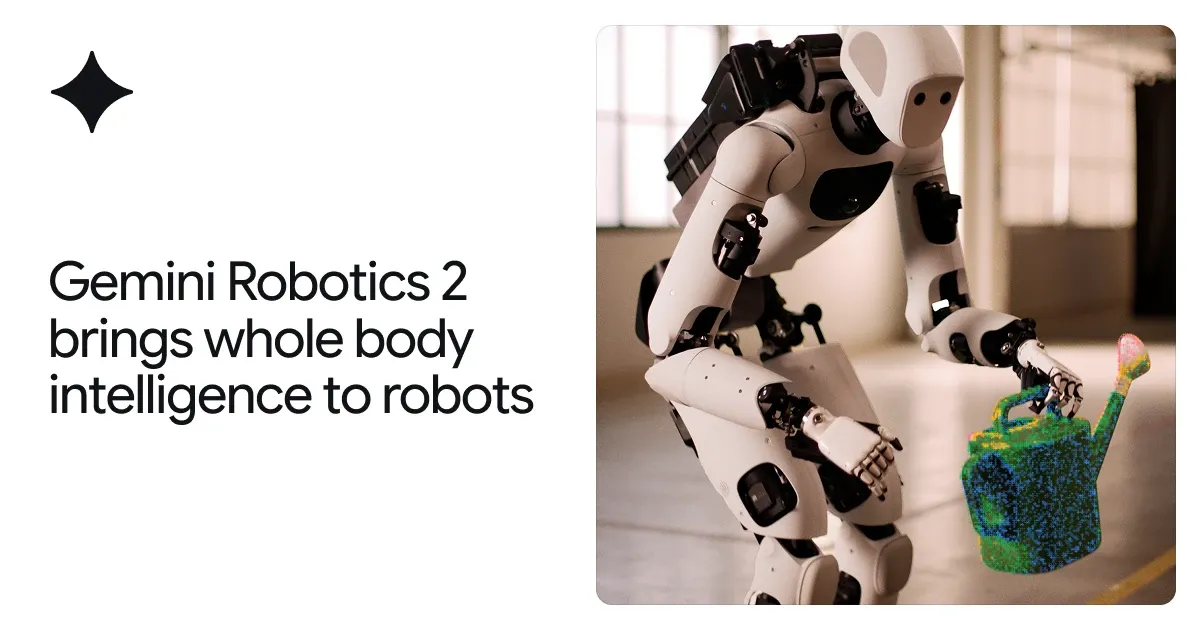
From feet to fingertips — we are teaching robots intelligent whole-body control, fine dexterity, and teamwork to complete a broad range of complex tasks.
MIT News · Artificial Intelligence· news.mit.eduJun 26, 2026
To help robots do chores in places like homes and factories, a new approach from MIT uses one language model to clarify users’ instructions, then another to ignore irrelevant info.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.