This work introduces FeatureFormer, a neural performance predictor that incorporates explicit node-wise encodings of FLOPs, parameter counts, and memory proxies within a gated graph attention architecture and presents NNEQ, a new large-scale energy consumption dataset that enables unified evaluation of latency and energy prediction.
Abstract
As neural networks are increasingly deployed on resource constrained edge devices, accurate prediction of latency and energy is critical for efficient neural architecture search. Existing GNN and transformer based predictors achieve strong results but largely ignore node-level computational cost, limiting their ability to model performance critical operations. To address this, we introduce FeatureFormer, a neural performance predictor that incorporates explicit node-wise encodings of FLOPs, parameter counts, and memory proxies within a gated graph attention architecture. We also present NNEQ, a new large-scale energy consumption dataset that enables unified evaluation of latency and energy prediction. Extensive experiments demonstrate that FeatureFormer achieves state-of-the-art performance across both metrics, including challenging out-of-domain settings. Finally, we show that the proposed encoding is broadly applicable and consistently improves existing predictors with negligible overhead.
Conventional compute-in-memory (CIM) deployment flows usually assume a fixed crossbar geometry, although DNN layers often have different channel counts and matrix shapes. The resulting shape mismatch leaves part of the array capacity unused and can increase the number of split-and-transfer operations during inference....
Kaiwen Deng, Sifan Sun, Hanjie Liu et al.· IEEE Non-Volatile Memory Sys...· 0 citations
This work proposes an architecture that leverages the inherent die white space of high-port-count switches to add shore arbiters, reducing latency and power for intra-shore traffic at zero area overhead and reduces average end-to-end latency by up to 56%.
A. Ben-Ari, Amit Golander· Proceedings of the 19th ACM...· 0 citations
Results demonstrate that STRAP delivers both high predictive accuracy and ultra-low-latency responsiveness in highly dynamic, high-concurrency streaming environments, exhibiting strong practical deployability for latency-sensitive real-time forecasting scenarios such as smart grid anomaly detection, financial risk cont...
Fang-Rui Yu, Xiang-Yu Lin· International Conference on...· 0 citations
This work presents CascadeLUT, an information-structured inference framework organized around bandwidth constraints, where instead of buffering the full input, features are partitioned into ordered subsets and predictions are progressively refined as subsets arrive, enabling deterministic streaming inference without ru...
O. Cassidy, Marta Andronic, G. Constantinides· 0 citations
Findings confirm that combining complementary compression strategies yields substantially better performance-efficiency trade-offs than any single technique applied in isolation.
Upma Sharma Archana· International Journal of Res...· 0 citations
A PyTorch-based, research-oriented framework is introduced that incorporates freezing and pruning mechanisms for designing and optimizing binarized neural networks and a novel pruning method that accounts for the relative importance of learned parameters across abstraction levels is proposed.
Roan Rubiales, Jean-Pierre David· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
Microsoft Research Blog· microsoft.comJul 13, 2026
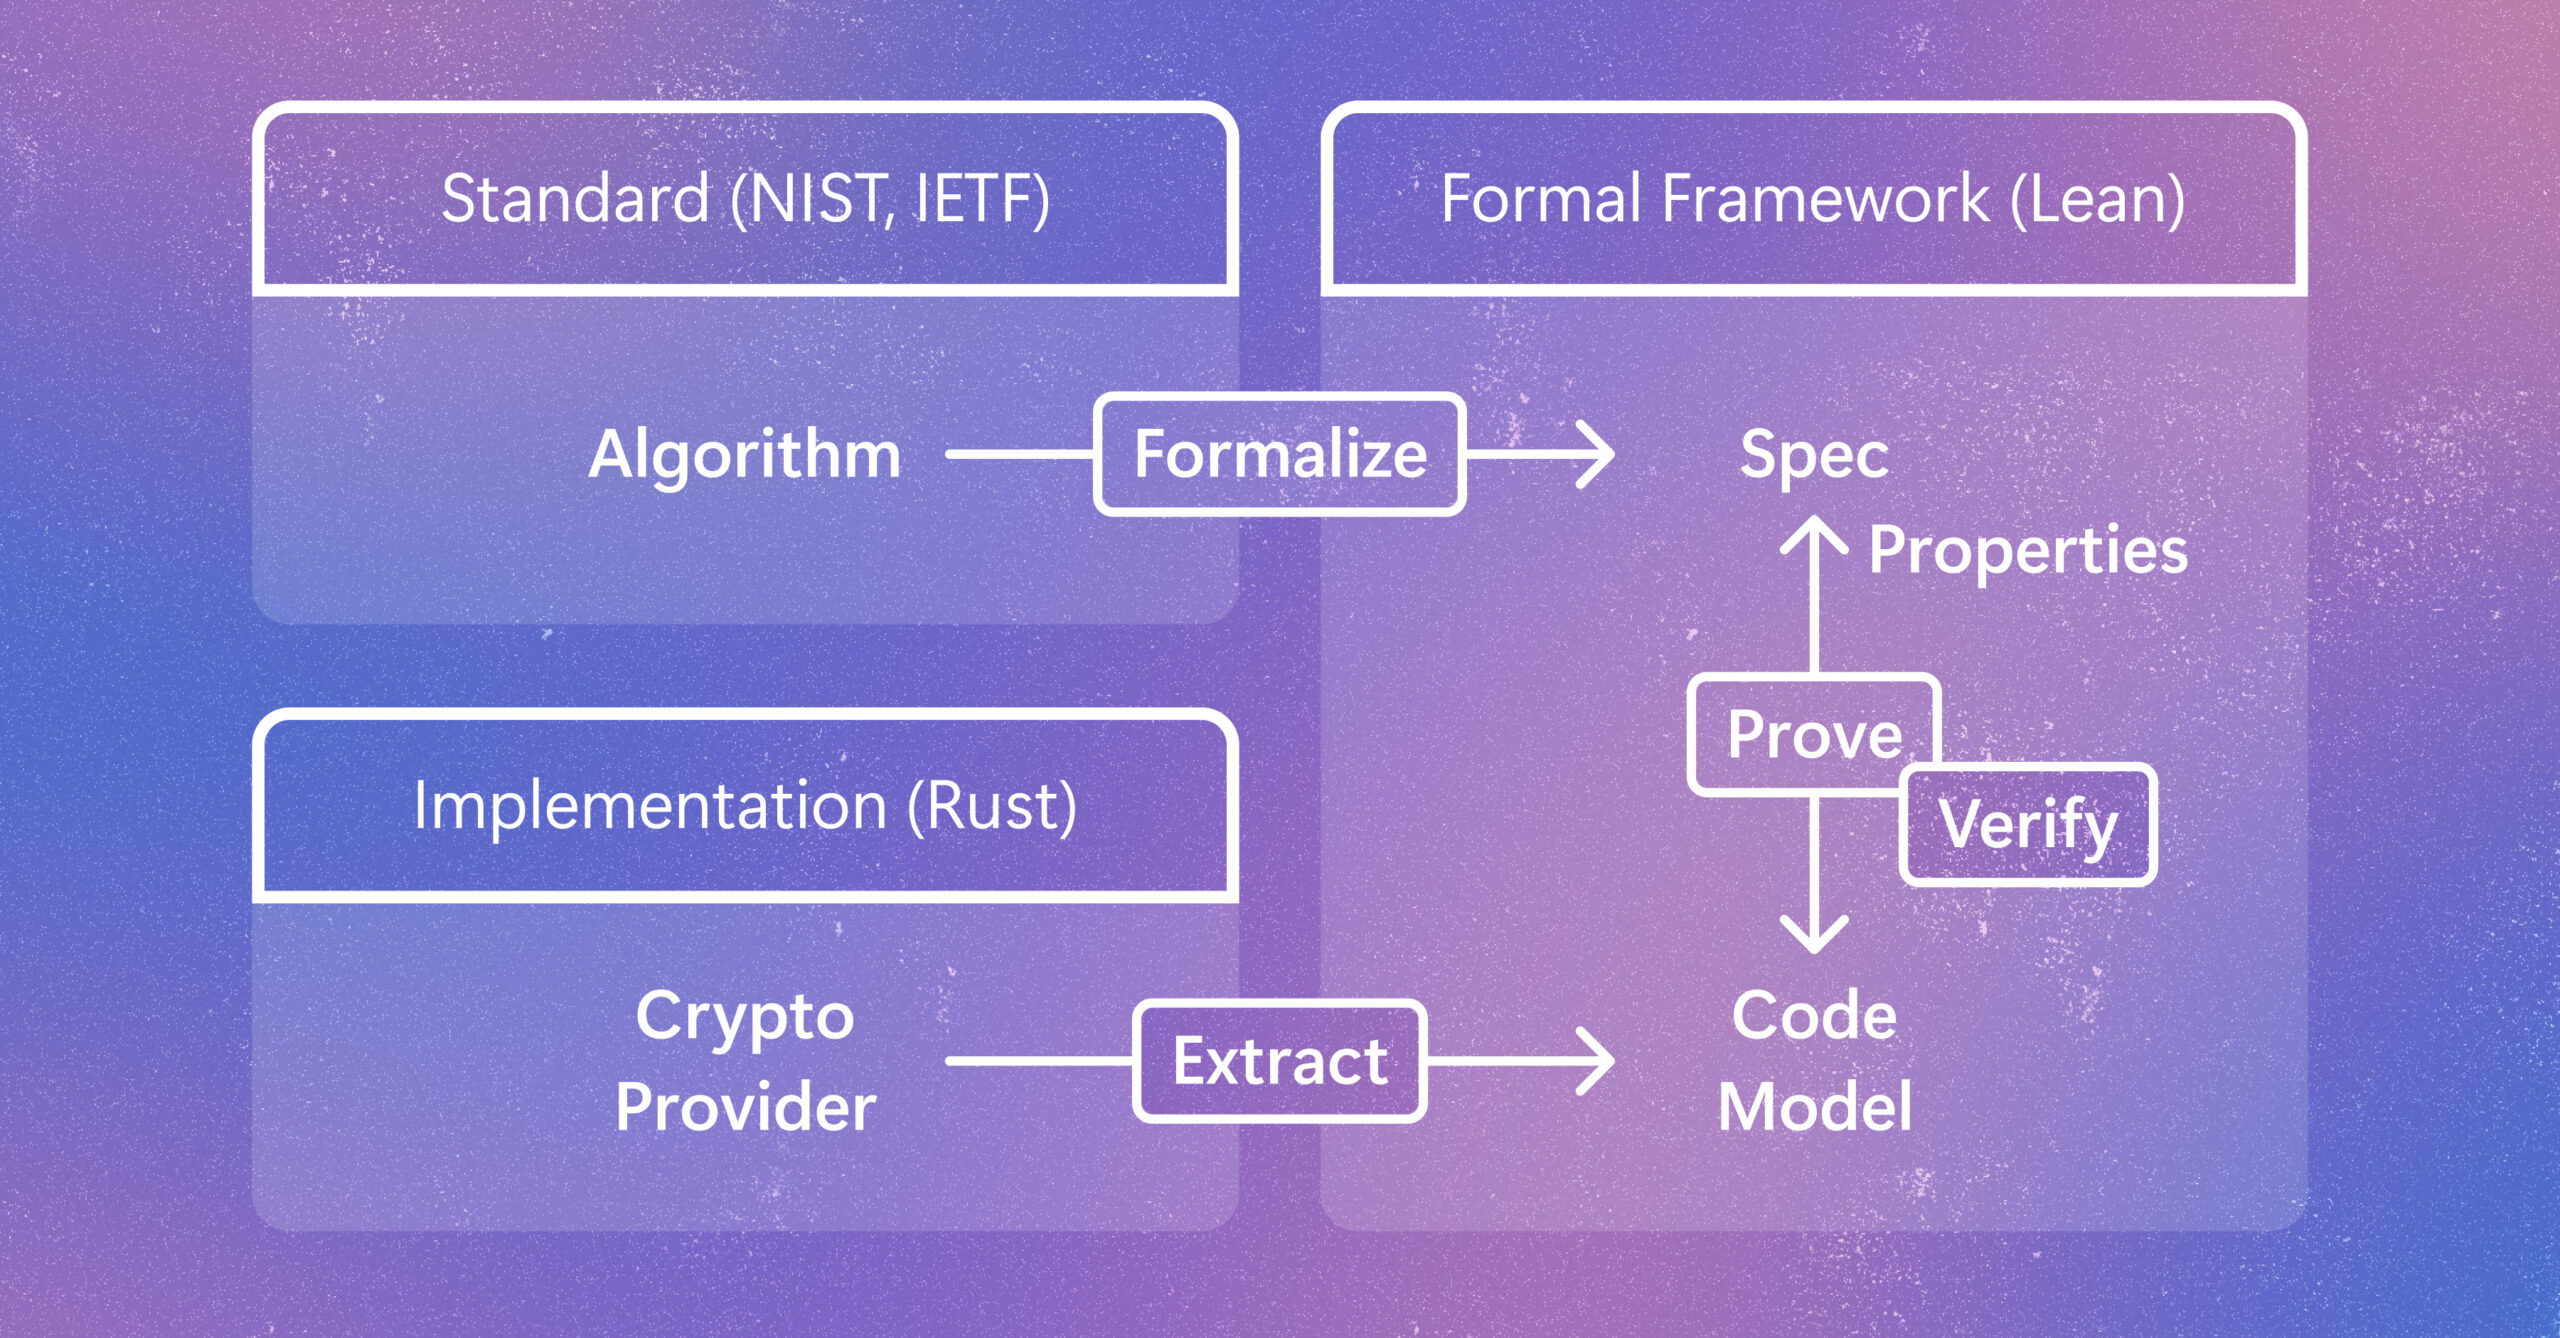
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.