Skip to content

Post-Training VLMs for Video Mistake Detection

Aug 2026 · 1 citation · 35 references
Computer Science

TL;DR

This work proposes the first video-language-model post-training technique for mistake detection, which uses a tailored reward function to encourage the model to identify discrepancies between an instruction and the corresponding video, and generalizes especially well to unseen procedures.

Abstract

Human mistakes are inevitable when following instructions, yet they can lead to severe consequences. As such, there has been an increased interest in developing methods for detecting mistakes in videos, with current methods mostly focusing on closed-set protocols. While successful in controlled settings, the closed-set assumption limits their wider applicability, as any changes to the task require collecting new data and re-training models. Instead, we argue that mistake detection methods should learn the general concept of a mistake, rather than overfitting to step-specific details. To reflect this, we introduce the Mistake Detection Video Question Answering (MD-VQA) protocol and accompanying benchmark. MD-VQA tests whether methods can discern if a step was executed correctly with respect to its description, for both seen and unseen actions. To address this important challenge, we propose the first video-language-model post-training technique for mistake detection. Our method uses a tailored reward function to encourage the model to identify discrepancies between an instruction and the corresponding video. Extensive evaluations demonstrate that this approach outperforms zero-shot, supervised fine-tuning, and post-training baselines. Notably, our method generalizes especially well to unseen procedures, for instance, with an improvement of up to 11.6% over the best-performing baseline on EP-VQA, paving the way toward general mistake detection. We release our code and benchmark at https://github.com/FedeSpu/mstk.

View source

Similar papers

Preprint Aug 2026

Where to Look Matters: On-Policy Self-Distillation for Long-Video Understanding

Clue-OPSD, a clue-privileged on-policy self-distillation framework for long-video understanding that uses clue intervals as privileged supervision without relying on ground-truth answer labels, while requiring no clue annotations or additional modules at inference time is introduced.

Kaishen Wang, Dong-Di Zhao, Yijun Liang et al. · 4 citations
Book Open access Aug 2026

When Models Leave the Training Distribution: A Tutorial on OOD Detection

This tutorial covers recent developments in OOD detection from both theoretical and practical perspectives, including four major categories: (1) post-hoc methods, (2) training-based methods with auxiliary outliers, (3) training methods without auxiliary outliers, and (4) foundation model-based approaches, along with re...

Suranga Seneviratne, Dishanika Denipitiyage, Sanjay Chawla et al. · 0 citations
Conference Open access 2026

Enhancing Zero-Shot Visual Reasoning with Qwen2-VL on CLEVR

Overall, the results show that the baseline is fairly stable under lightweight prompt and decoding changes, however, these low-cost adjustments do not solve the model's main weakness, which still appears in spatial and compositional reasoning.

Zhong-Tian Liu · 0 citations
#artificial intelligence Preprint Sep 2026

Are We Really Doing Few-Shot Learning? A Critical Examination of Pre-Training Assumptions

The results show that class disjointness alone is insufficient to remove the influence of target-domain data, highlighting the need to move beyond in-domain pre-training as the default few-shot evaluation protocol, since it can overestimate performance in realistic scenarios where target-domain data are scarce.

Alejandro Gal'an-Cuenca, Marcelo Saval-Calvo, Antonio Javier Gallego · 0 citations
Preprint Aug 2026

Video-FLAIR: Not Whether to Reason, But How

Video-FLAIR is introduced, a training framework that learns to select the appropriate reasoning mode for each query using reinforcement learning, and yields a supervision signal for learning adaptive reasoning without per-query annotations.

Yogesh Kulkarni, Pooyan Fazli · 0 citations

Related blog posts

Microsoft Research Blog Aug 11, 2026

Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

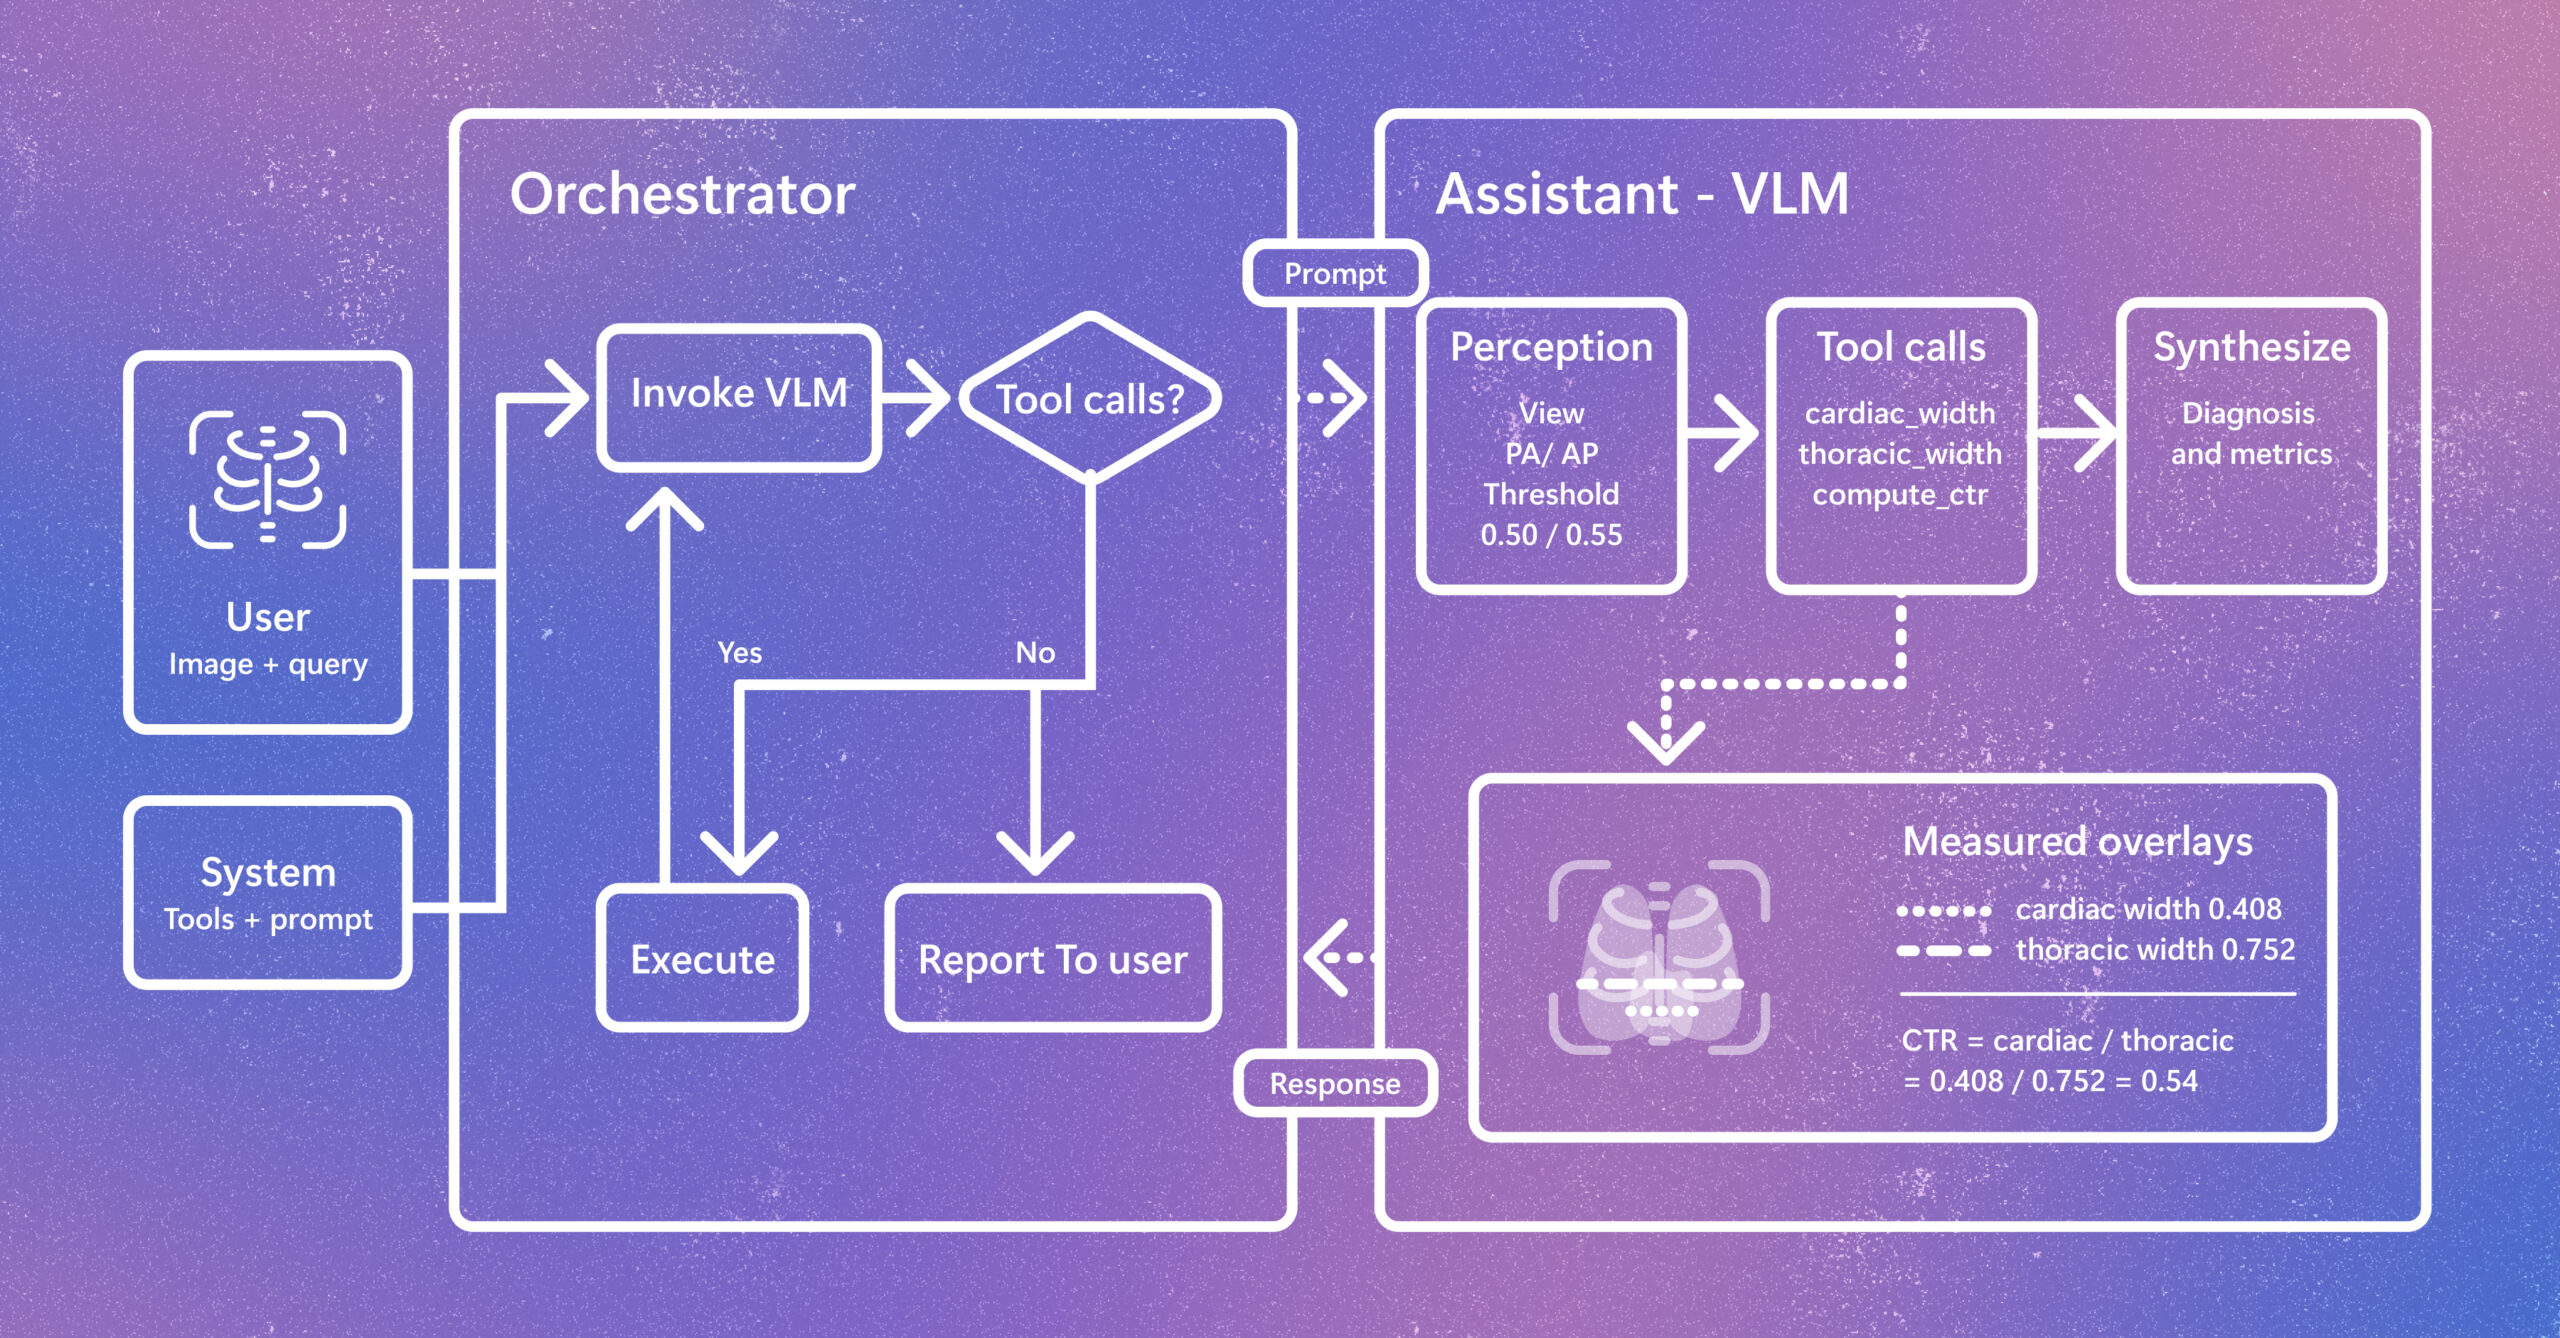
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.
