StarWM is proposed, which uses a cross-attention module trained on self-supervised dynamics to decide where reconstruction applies and preserves state attributes with near-perfect fidelity through long-horizon imagination while systematically discarding distractors.
Abstract
A robust world model must strike the balance between faithfully capturing environmental dynamics and abstracting away from irrelevant content. While reconstruction-based world models ensure faithful supervision, they misallocate representational capacity by pixel area rather than dynamics relevance for visual tasks, which can cause task-irrelevant content to dominate the learned representation. Alternatively, reconstruction-free methods avoid this bias but risk discarding possibly relevant information. We propose StarWM, which uses a cross-attention module trained on self-supervised dynamics to decide where reconstruction applies. A dual-stream decoder then restricts reconstruction to the attended regions, with stop-gradient barriers preventing interference between the two objectives. These components allows reconstruction to supervise the visual content of attended regions without contaminating the latent with non-predictive information. On DeepMind Control with dynamic video backgrounds, default (reward-free) StarWM achieves the strongest performance under random-frame distractors and substantially outperforms reconstruction-based baselines under sequential video. In addition, its reward-augmented variant matches or exceeds reconstruction-free methods on sequential video, achieving the highest overall return across all distractor regimes. Mechanistic probing confirms StarWM preserves state attributes with near-perfect fidelity through long-horizon imagination while systematically discarding distractors.

World models for visual control typically learn compact latent states by reconstructing observations, implicitly encouraging representations to preserve information across the entire visual input. However, task-relevant content often occupies only a small fraction of the observation, while background clutter and distra...
World models trained via pixel reconstruction can struggle in visually complex environments, where irrelevant information dominates the objective and distract the model from information relevant to planning and control. We present Contrastive World Models, an approach for learning latent dynamics models without pixel r...
This work introduces CVPD (Contrastive Counterfactual Visual Process Distillation), which is the first fully self-contained framework for dense, on-policy, token-level visual self-distillation for MLLMs, and proposes a three-gate Counterfactual Criterion that identifies visual blind spots where zooming into a region ch...
Shravan Venkatraman, Omkar Thawakar, Ritesh Thawkar et al.· 2 citations
GlanceWAM is introduced, which decouples imagination from control within a single video DiT: an asynchronous proposer glances ahead on a slow clock to imagine a single lookahead frame seconds into the future in the background, while an action head decodes action chunks at control rate purely in latent space without blo...
Lin-Han Wang, Zi-Jian An, Mingyuan Zhang et al.· 1 citation
Compact JEPA world models enable efficient latent-space planning, but low-dimensional representation trained under reward-free self-supervision must encode both action-conditioned dynamics and predictable visual context. This competition can entangle controllable state with high-rank nuisance appearance and degrade pla...
Lu-Zhe Huang, Lei Chu, Jing-Yi Liang et al.· 0 citations
This paper explores post-training reinforcement learning (RL), specifically GRPO, to directly align autoregressive perception models with their evaluation metrics, and designs an RL framework that addresses perception-specific challenges: reward design for set-structured outputs and multi-head sampling control.
Sofian Chaybouti, Yasser Dahou, N. Huynh et al.· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comAug 11, 2026
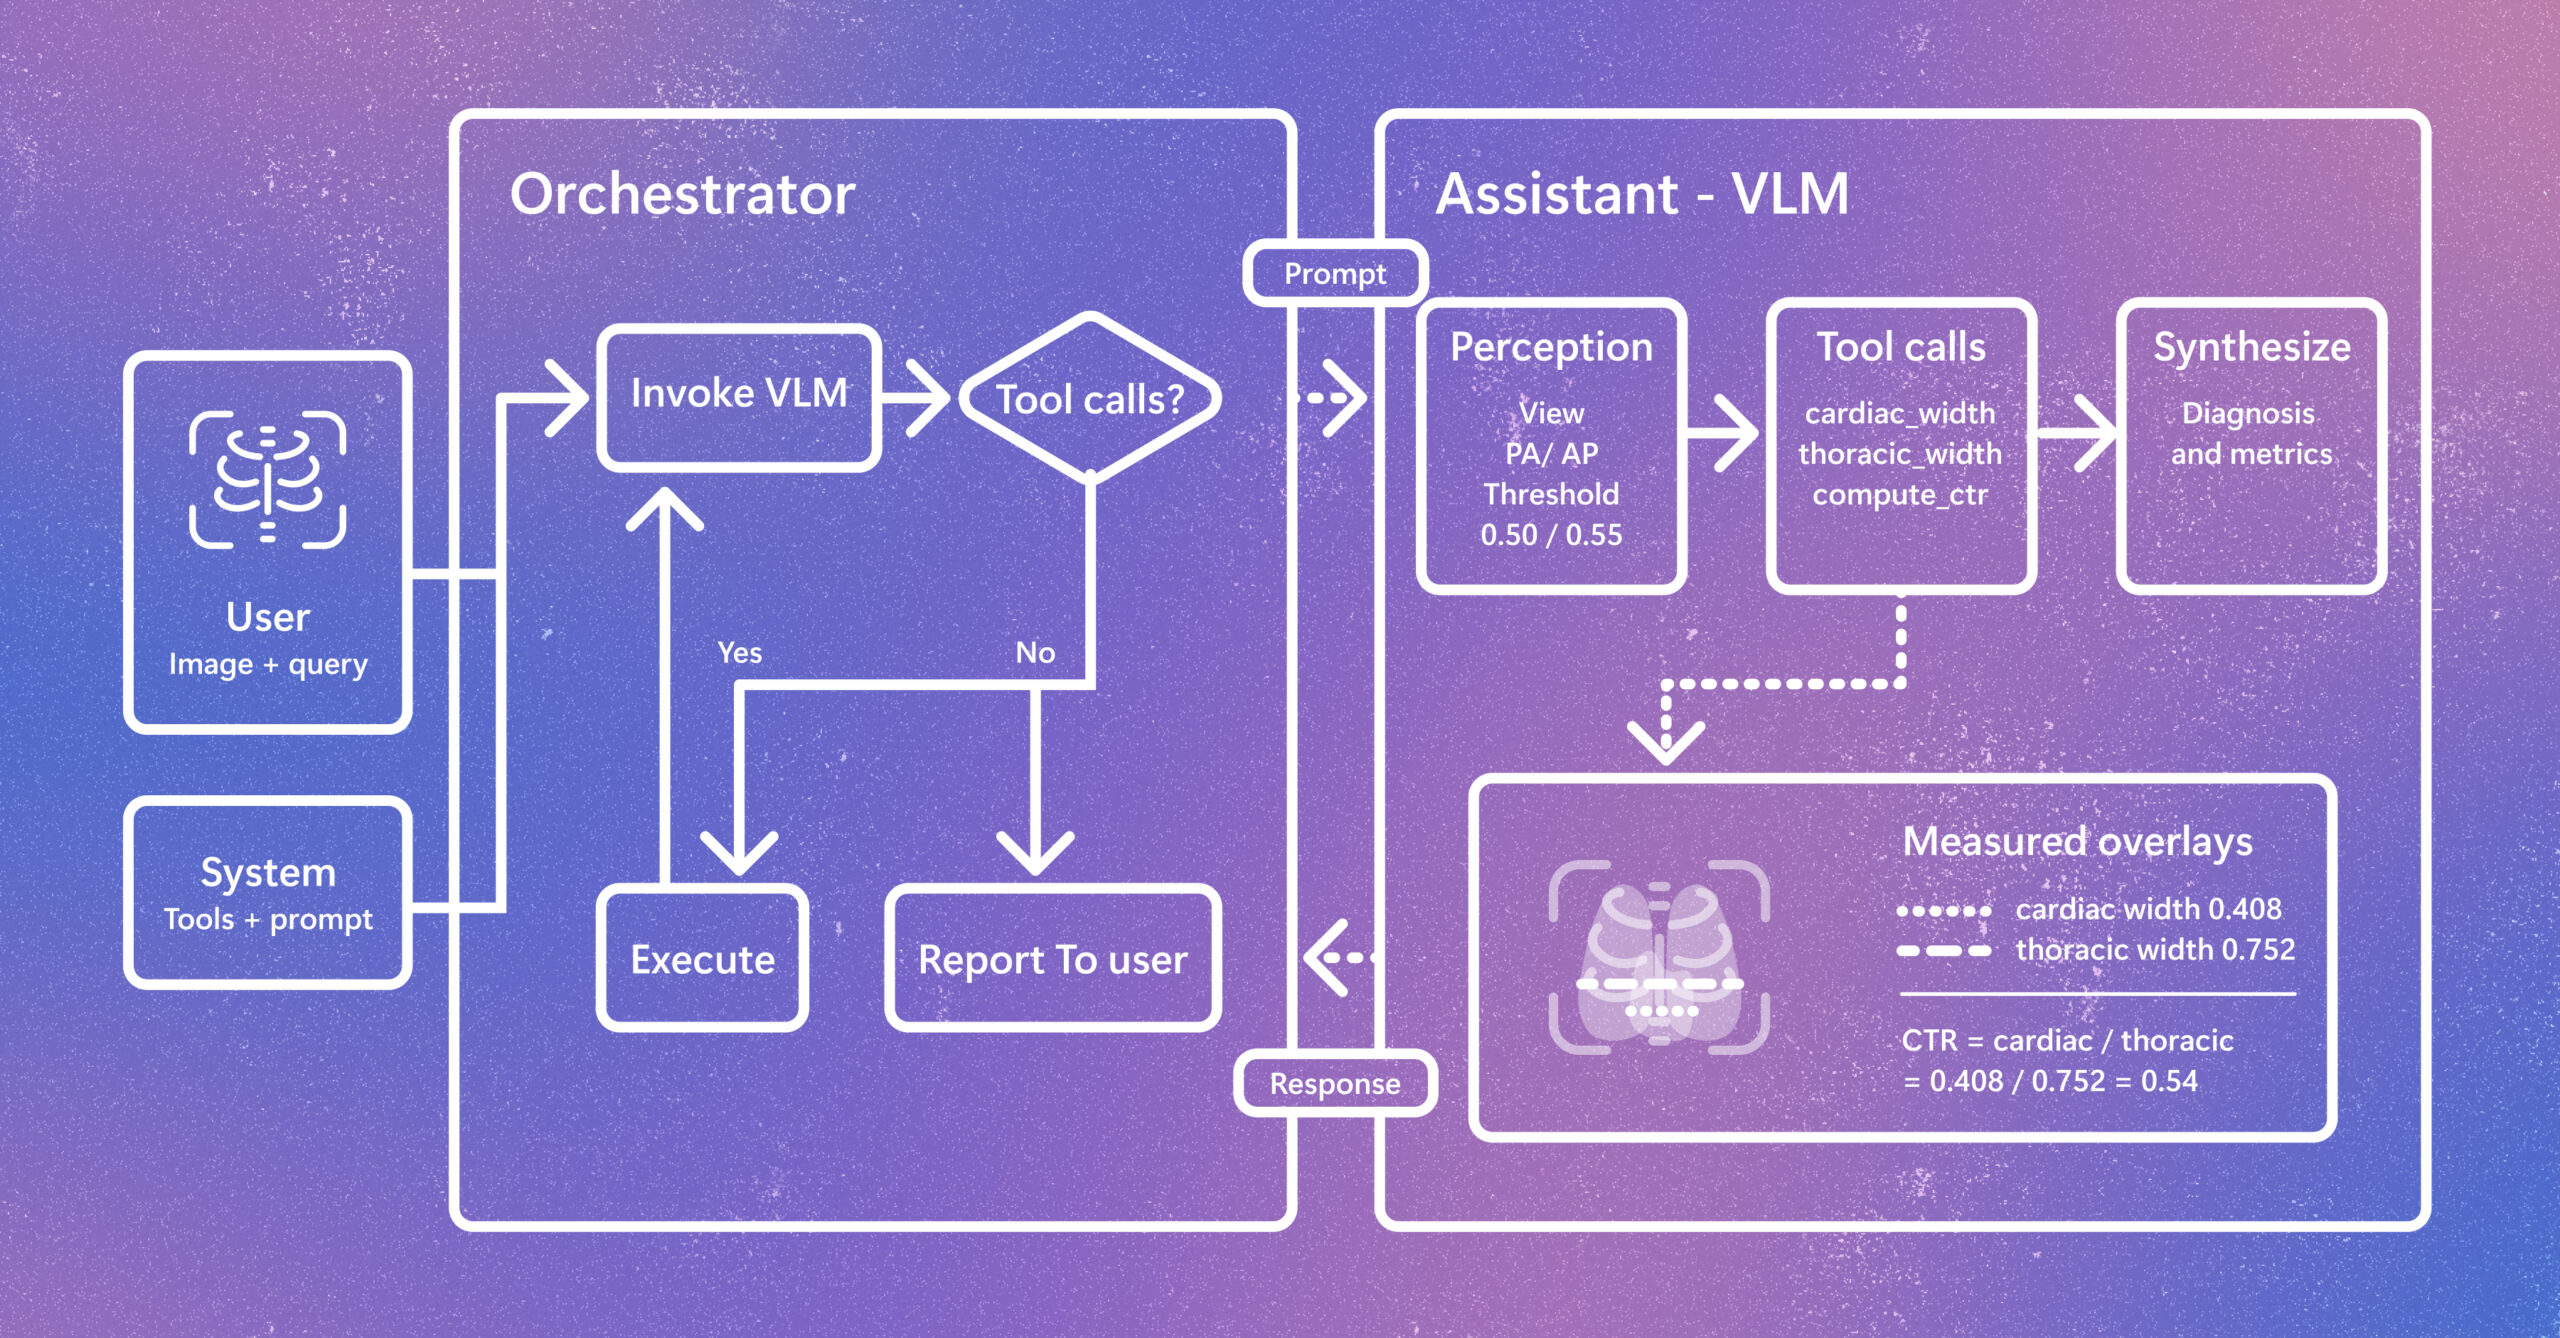
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.