Sep 2026· Zenodo (CERN European Organization for Nuclear Research)
Abstract
Preprint · Version 1 · September 2026 · Not peer reviewed If the limits of language are the limits of the thinkable, then the possibility of linguistic superintelligence depends on whether a system can expand its own language. This paper argues that large language models (LLMs) cannot do so in a closed regime. We introduce a distinction between traversal (moving efficiently through an existing conceptual space) and expansion (enlarging that space), and argue that LLMs can exceed human performance in traversal without acquiring autonomy in expansion. Drawing on Wittgenstein, the weak form of linguistic relativity, and analyses of vocabulary control in Orwell and Foucault, we treat language as the boundary condition of conceptual space rather than a neutral medium. We then examine the literature on model collapse, which shows that recursive training on model-generated text erodes the tails of the linguistic distribution and progressively narrows what the model can express. Crucially, the regimes that avoid collapse do so by retaining human-generated data, confirming the models' dependence on an external source. We address the strongest objection, reinforcement learning with external verifiers, and argue that it confirms rather than refutes the thesis: expansion requires a signal exogenous to the model's own generation. We conclude that the engine that pushes the frontier of the thinkable remains exogenous to the model. Current LLMs are best understood as instruments of unprecedented traversal power operating within a space they did not open and cannot, by themselves, enlarge. About this work. This is an interdisciplinary essay at the intersection of philosophy of language and machine learning. It offers a conceptual argument rather than new experiments: it takes the published empirical results on model collapse (Shumailov et al., Nature 2024; Gerstgrasser et al. 2024; Dohmatob et al. 2024) as premises and draws out their philosophical consequences for the debate on recursive self-improvement and superintelligence. Comments and criticism are welcome at the correspondence address in the PDF. A revised version will be submitted for peer review; this record will be updated with the DOI of the published version if accepted.

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.
Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al.· IEEE Transactions on Softwar...· 178 citations· ⚡14
This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.
Carmine Giardino, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 175 citations· ⚡19
Software startup companies develop innovative, software-intensive products within limited timeframes and with few resources, searching for sustainable and scalable business models.
M. Unterkalmsteiner, P. Abrahamsson, Xiaofeng Wang et al.· e-Informatica Software Engin...· 157 citations· ⚡17
This study conducts a case survey study based on the secondary data of the major pivots happened in 49 software startups, and demonstrates that customer need pivot is the most common among all pivot types.
Sohaib Shahid Bajwa, Xiaofeng Wang, Anh Nguyen-Duc et al.· Empirical Software Engineeri...· 127 citations· ⚡15
The comparison of adopter and non-adopter sample reveals three potential adoption inhibitor, security, data privacy, and portability, which underlines the importance of the technical and security perspectives for research investigating the adoption of technology.
Nattakarn Phaphoom, Xiaofeng Wang, S. Samuel et al.· Journal of Systems and Softw...· 111 citations· ⚡8
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
Microsoft Research Blog· microsoft.comOct 12, 2026
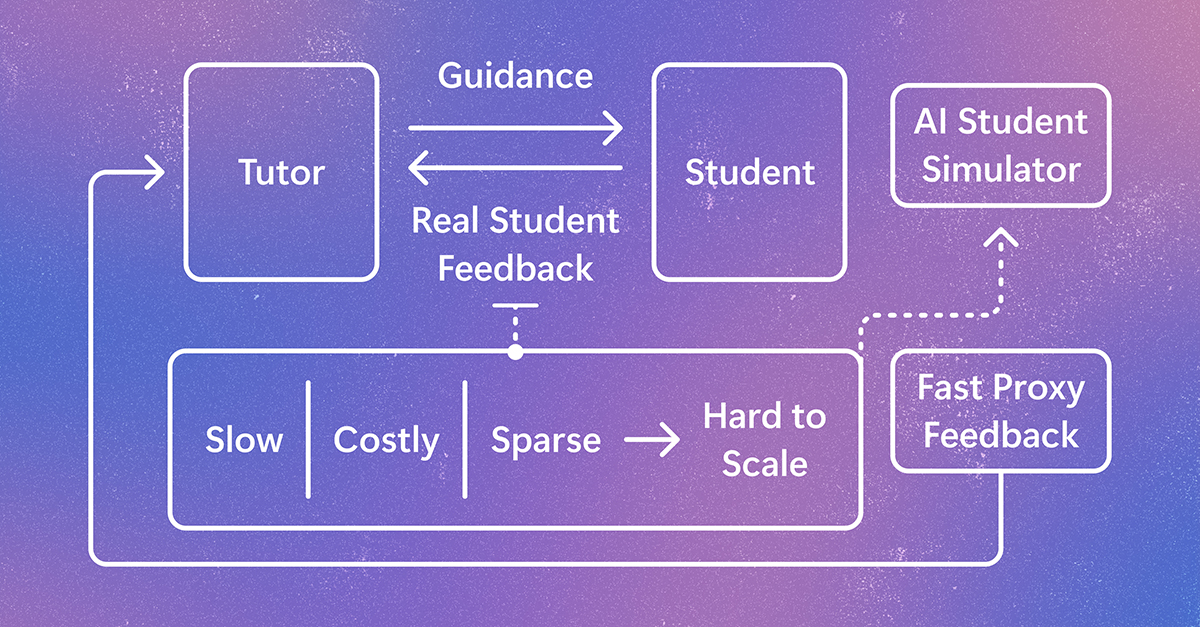
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.