Skip to content

STEER: Reducing Inference Cost in Relational Foundation Models through Semantically Informed Sampling

Oct 2026 · 0 citations · 38 references
Computer Science

TL;DR

STEER is proposed, a sampling approach that shrinks the inference context by concentrating it on the tables most relevant to the prediction task at hand, and it is shown that it reduces inference context size by about 40% on average while maintaining, and in some cases improving, prediction accuracy.
Abstract

Relational foundation models (RFMs) are pretrained once on a collection of relational databases and prediction tasks, and then applied zero-shot to previously unseen databases and tasks. To make a prediction for a target row, an RFM samples a neighborhood of rows linked to that row through foreign keys and uses this neighborhood as its inference context. Lowering inference cost is an important goal for any foundation model, and for RFMs this cost grows with the size of the context. The simplest ways to shrink the context is to drop some of the sampled rows, but this ignores the semantics of the database schema, so it is as likely to discard informative rows as uninformative ones. We propose STEER, a sampling approach that shrinks the inference context by concentrating it on the tables most relevant to the prediction task at hand. STEER obtains relevance information by prompting a large language model to rank the foreign-key edges of the database schema into relevance tiers for the given task, and then maps each tier to a probability of following that edge during traversal. Because the ranking uses only the schema, it is computed once per task and reused across all subsequent predictions, amortizing its cost. We evaluate STEER on three state-of-the-art RFMs (RT, RT-J, and Griffin) and show that it reduces inference context size by about 40% on average while maintaining, and in some cases improving, prediction accuracy.

View source

Similar papers

Preprint Oct 2026

Prune First, Decide Fast: Scalable Semantic Query Processing with JEVDB

Semantic database systems extend SQL with foundation-model inference over unstructured data, but current engines rely heavily on autoregressive LLMs for discrete relational decisions, creating high latency and monetary cost. We present JEVDB, a scalable semantic database system that uses fast, typed decision models for...

Zheng-Le Wang, Han-Xu Yan, Fuheng Zhao et al. · 1 citation · ⚡1
#machine learning Preprint Oct 2026

RelICL: Training-free Relational Learning with Tabular Foundation Models

Tabular foundation models achieve state-of-the-art performance on single-table tasks without any training. Recent work suggests that they are also well-suited for relational learning via deep feature synthesis (DFS), which flattens a relational schema into a single table by adding aggregates of the other tables'columns...

Simon Forbat, Rainer Gemulla · 0 citations
Open access Sep 2026

TACO: Token-Aware Context Optimization for Structured OpenStreetMap Query Generation

Generating executable structured queries for OpenStreetMap (OSM) from natural language remains a challenging task due to the rigid syntax of OverpassQL and the steep learning curve it presents to end-users. While steering Large Language Models (LLMs) via demonstration contexts offers a promising solution, existing...

Zhuoyue Wan, Wentao Hu, Hwanhee Kim et al. · 0 citations
#artificial intelligence Preprint Oct 2026

Correspondences as Decisions: JevNexus for Decision-Centric Schema Matching

Schema matching increasingly uses generative language models to rerank retrieved column candidates, although the underlying task is a bounded correspondence decision. We present JevNexus, which combines typed pairwise decisions with schema/instance evidence and invokes listwise refinement only when the evidence disagre...

Run-Ze Li, Han-Chen Wang, Ying Zhang et al. · 0 citations
Sep 2026

Supervised and LLM-Augmented Cardinality Estimation for Similarity Queries on Knowledge Graphs

Over the past decades, query cardinality estimation on relational databases has been proven crucial, enabling the result size estimation of all sub-plans of each query. This allowed query optimizers to design efficient query plans, towards minimizing the query response time. Lately, knowledge graphs are being preferr...

Georgios Chatzigeorgakidis, Dimitrios Skoutas, A. Simitsis · 0 citations
#artificial intelligence Preprint Aug 2026

rEDMRec: Distilling Large Language Model Reasoning into an Editable Experience Memory for Recommendation

Large language models can improve recommendation quality by reasoning explicitly over user history and candidate items - for example, extracting a user's preferences or explaining why one item fits better than another - rather than mapping history directly to a ranked list. This reasoning, however, is expensive to repe...

M. H. Nguyen, Tung Le, Huy-Tien Nguyen · 0 citations

Related blog posts

MIT News · Artificial Intelligence Aug 27, 2026

Looking beyond natural sequences

A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.

Microsoft Research Blog Aug 20, 2026

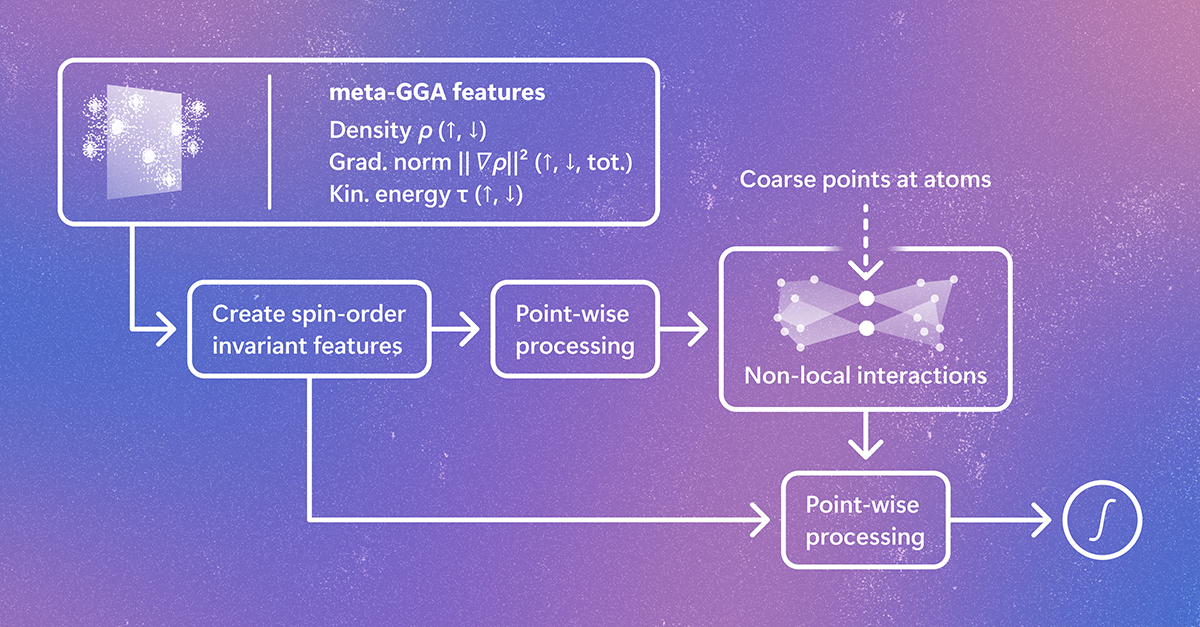
Broadening access to Skala creates a faster path to predictive DFT 

Skala 1.1, the updated deep-learning exchange-correlation functional from Microsoft Research, provides greater accuracy, expanded accessibility across the computational chemistry ecosystem, and a living benchmark to track computational performance. The post Broadening access to Skala creates a faster path to predictive DFT  appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.