Skip to content

What Wins a Vote? Formatting, Length, and Lexical Diversity in the French Compar:IA LLM Arena

Oct 2026 · 0 citations · 2 references
Computer Science

TL;DR

A stylometric approach to 137,293 decisive French-language votes from the July 2026 Compar:IA release is taken, taking a stylometric approach to the raw ranking with rankings adjusted for formatting, length, readability, vocabulary variety, and sentence structure.

Abstract

LLM arenas turn pairwise human preferences into model rankings. Those preferences may reflect how an answer is presented as well as what it says. We take a stylometric approach to 137,293 decisive French-language votes from the July 2026 Compar:IA release; the primary formatting analysis includes 137,113 battles across 116 models, and the joint estimates use the 127,092 battles with all required measurements. For each battle, we reconstruct the response visible when the user voted. We then compare the raw ranking with rankings adjusted for formatting, length, readability, vocabulary variety, and sentence structure. Presentation is associated with winning, but length, bold text, and lists tend to occur together, making their individual contributions hard to separate. Across the measured features, two associations change least across specifications: bold usage (+11.0% win odds per standard deviation in the joint model) and moving-average type-token ratio (MATTR), a measure of vocabulary variety that is less sensitive to answer length (+16.8%). The bold association is substantially smaller in observed multi-turn conversations, whereas the MATTR association changes little; because users choose whether to continue, this difference is descriptive rather than causal. The full adjustment moves 36 of 116 models by at least ten ranks. Yet comparisons with external benchmarks do not show that adjusted rankings better measure capability. We therefore recommend publishing raw and adjusted rankings side by side as a transparent sensitivity analysis.
View source

Similar papers

#machine learning Preprint Oct 2026

Similar Models, Broken Odds: Where Luce's Axiom Fails in Chatbot Arena

Chatbot Arena ranks language models with the Bradley-Terry model, which gives each model one score and so assumes Luce's choice axiom. Choice theory predicts where this fails: near-copies are told apart more decisively than their scores imply. On 1.8 million Arena votes, votes between versions of one model are 1.37 tim...

S. Bakshi, Apurba Bose, Aishwarya Bose et al. · 0 citations
Book Open access Oct 2026

Journal Atlas: Venue Fit Scoring Under Incomplete Evidence, and the Corpus Method It Requires

We present Journal Atlas, a public corpus of 399 curated venue profiles and two methods over it: one that scores how well a manuscript fits a venue and reports how much evidence that score rests on, and one that builds the corpus with a language model without letting it invent what nobody has recorded. Existing recomme...

Meng-Han Lee · 0 citations

Related blog posts

Microsoft Research Blog Oct 22, 2026

Flint-interactive: A language for creating interactive data visualizations

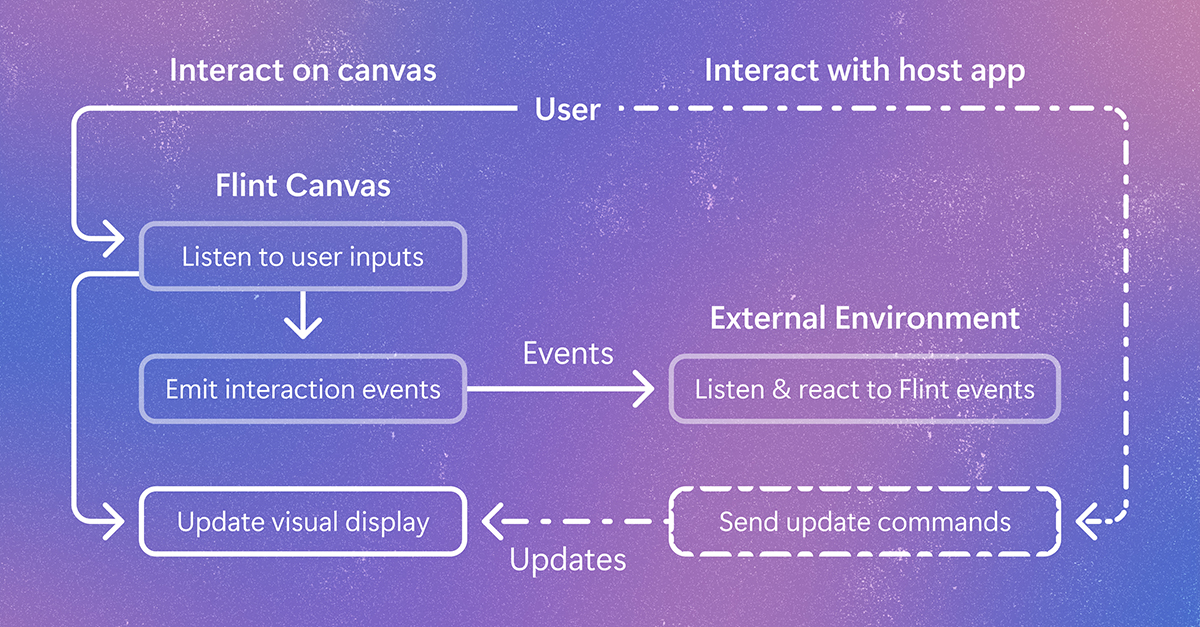
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.

MIT News · Artificial Intelligence Oct 15, 2026

AI model decodes the language cells use to communicate

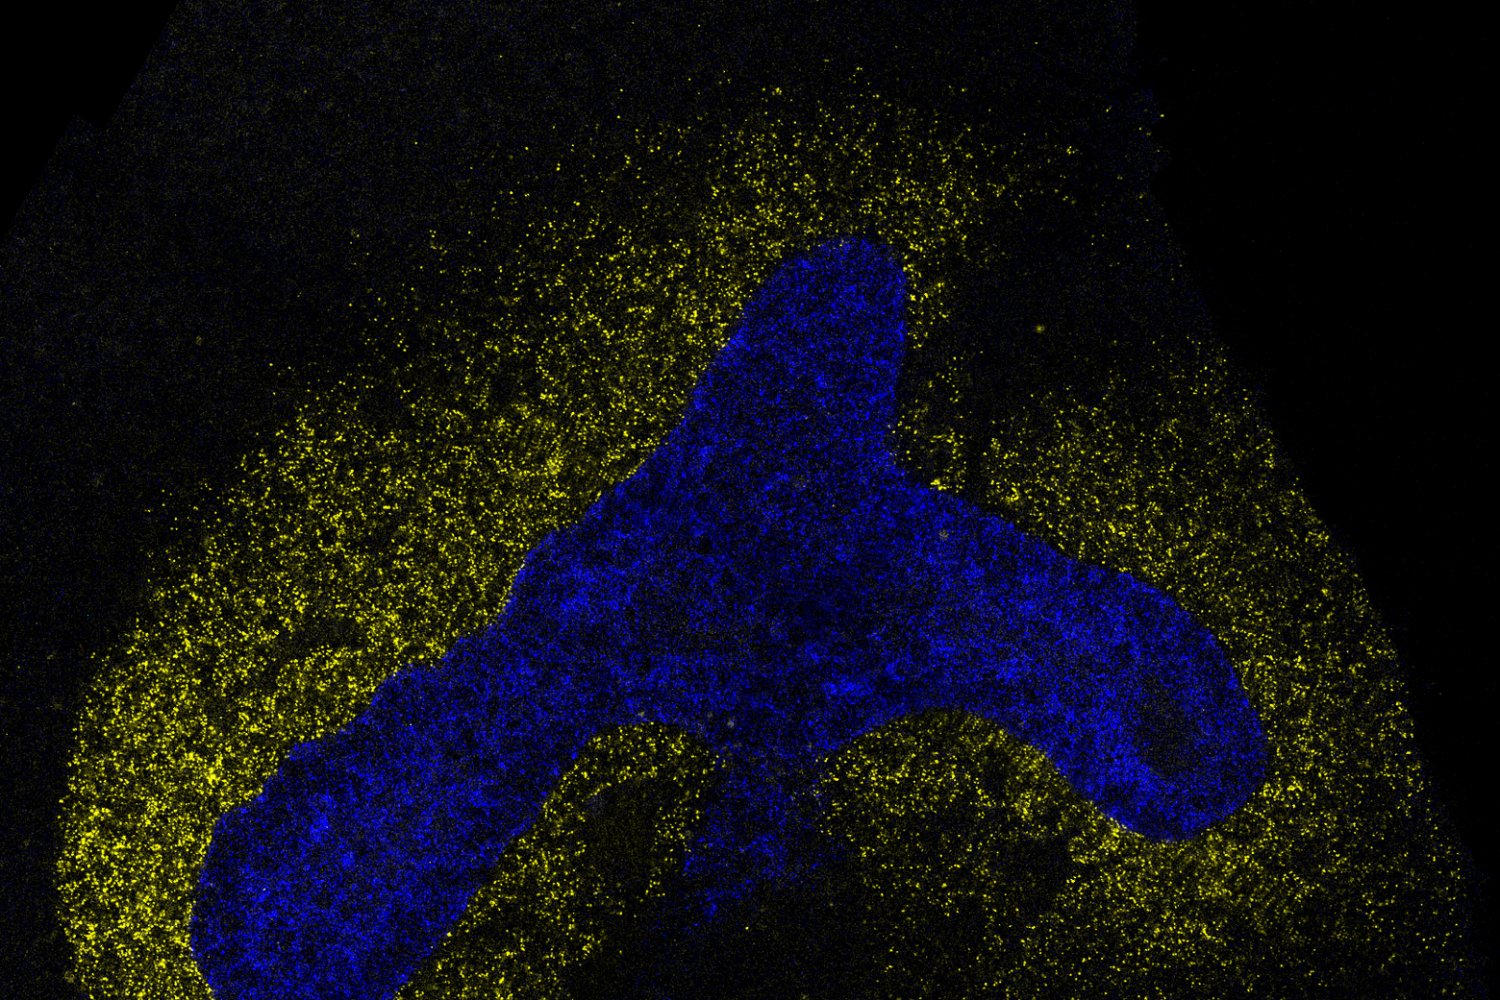
A new computational approach reveals how cells communicate to assemble into tissues. This could accelerate stem cell engineering, improve disease models, and inform therapies.

Microsoft Research Blog Oct 15, 2026

Proof-based general-purpose computing with Magnetar

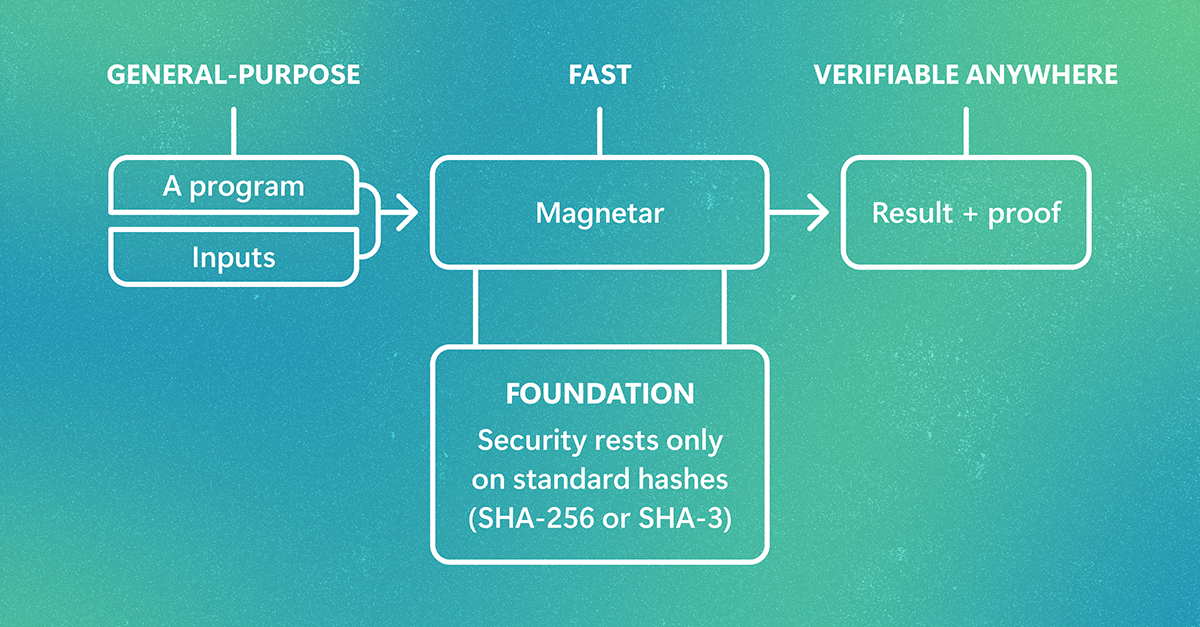
Zero-knowledge proofs can verify computing results without rerunning workloads or exposing sensitive data. Magnetar helps bring them into the mainstream with support for standard programming languages, major speed gains, and quantum-resistant security. The post Proof-based general-purpose computing with Magnetar appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.