Mar 2026· arXiv.org· Vol abs/2603.21404· 2 citations· 73 references
Computer Science
Abstract
Large language models are increasingly used to annotate texts, but their outputs reflect some human perspectives better than others. Existing methods for correcting LLM annotation error assume a single ground truth. However, this assumption fails in subjective tasks where disagreement across demographic groups is meaningful. Here we introduce Perspective-Driven Inference, a method that treats the distribution of annotations across groups as the quantity of interest, and estimates it using a small human annotation budget. We contribute an adaptive sampling strategy that concentrates human annotation effort on groups where LLM proxies are least accurate. We evaluate on politeness and offensiveness rating tasks, showing targeted improvements for harder-to-model demographic groups relative to uniform sampling baselines, while maintaining coverage.
Annotator disagreement is increasingly recognized as a meaningful property of subjective tasks, rather than merely noise to be removed. Predicting which items are likely to be contested could help allocate annotation effort and route difficult cases to human review. We propose predicting disagreement from interpretable...
Irem Ecem Yelkanat, Faeze Ghorbanpour, Alexander Fraser· 0 citations
Identification and ranking of salient propositions in documents is indirectly involved in many AI tasks, but few papers define proposition salience scores clearly, make diverse data available, or evaluate models directly on the task. This paper proposes PROPALIGN, a multiple-summary-based approach for propositional sal...
Lin Ai, Emma Thronson, Katherine Conhaim et al.· 0 citations
Variation caused by task design and model choice instrument uncertainty is called variation caused by task design and model choice instrument uncertainty because researchers can measure it only by comparing reasonable task designs.
Thomas Reiter, Christoph Kern, F. Miasnikov et al.· 0 citations
It is proved that overlap sparsity is the first-order determinant of wrong deployment decisions: at 5% pairwise overlap, wrong-decision rates reach 25% and the probability of selecting the wrong best judge among ten candidates is 65%.
NAPHA (eNtropy-Aware Post-Hoc Alignment), a simple yet effective lightweight post-hoc alignment method that matches the LLM distribution to the HJD by first assigning an instance to a discrete entropy class and then routing it to specialized, trained alignment models is proposed.
Sebastian Steindl, Nikos Voskarides, Alberto Gasparin et al.· 0 citations
This work systematically compares LLMaJ methods with and without decomposition on multiple NLG datasets and finds that, when human labels are available, LLMaJ without using task decomposition can perform comparably to human annotators.
Sebastian Steindl, Nikos Voskarides, Alberto Gasparin et al.· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comOct 22, 2026
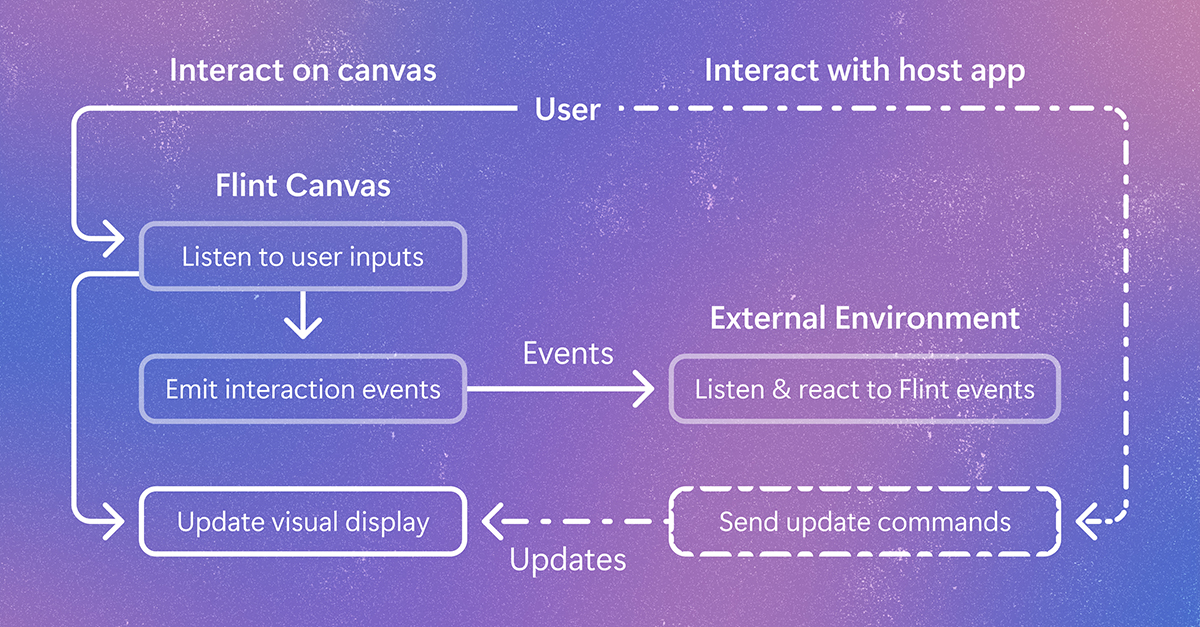
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.
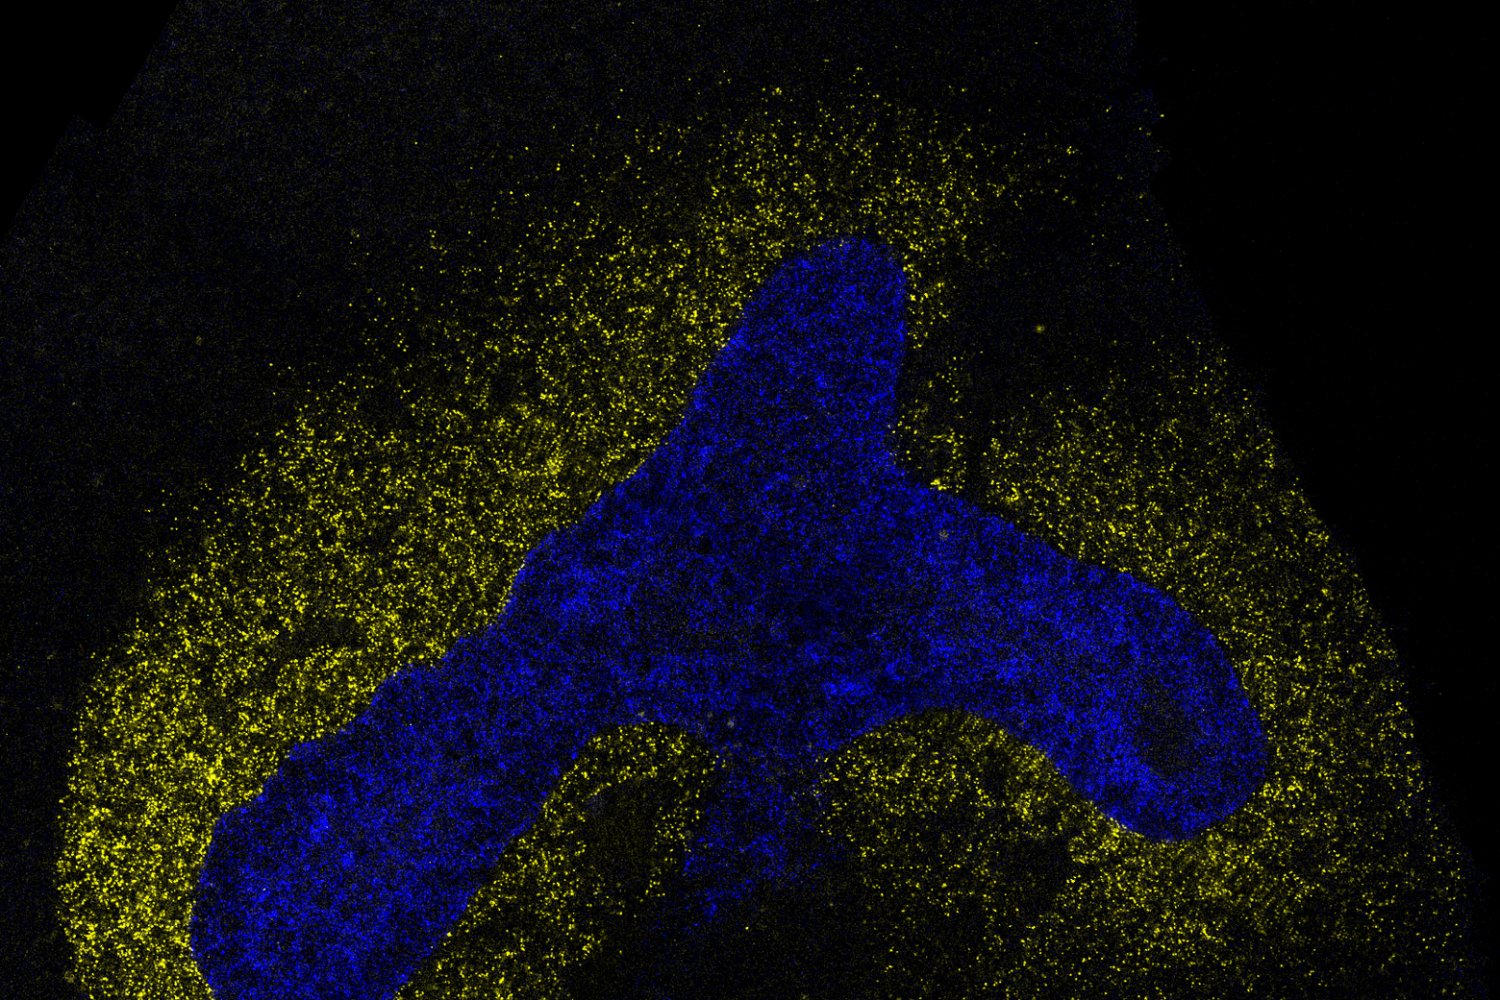
A new computational approach reveals how cells communicate to assemble into tissues. This could accelerate stem cell engineering, improve disease models, and inform therapies.
Microsoft Research Blog· microsoft.comOct 15, 2026
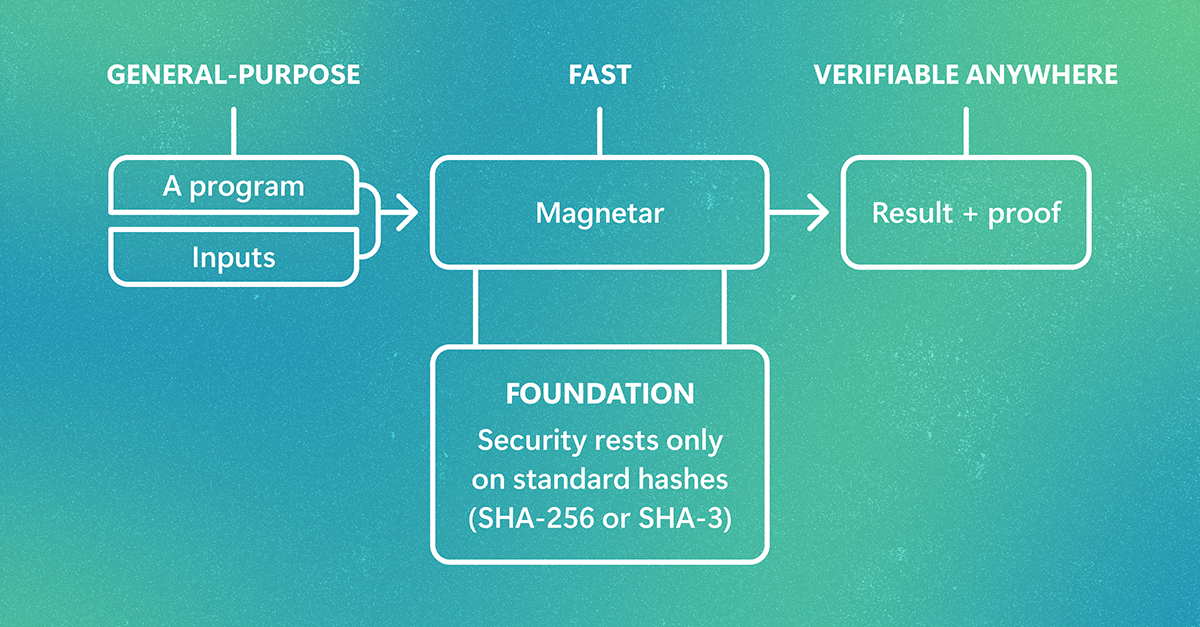
Zero-knowledge proofs can verify computing results without rerunning workloads or exposing sensitive data. Magnetar helps bring them into the mainstream with support for standard programming languages, major speed gains, and quantum-resistant security. The post Proof-based general-purpose computing with Magnetar appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.