Oct 2026· 1 citation· ⚡ 1 influential· 35 references
Computer ScienceMathematics
Abstract
We prove global exponential (linear) convergence with an explicit rate in the rich scaling for wide two-layer linear networks trained with smooth Polyak-Lojasiewicz predictor losses. Gradient flow in the factors closes exactly in terms of a finite-dimensional Bures flow of the neuron law covariance, in which the predictor dynamics are preconditioned by hidden covariance blocks. Mean-field conservation laws provide uniform spectral lower bounds on the hidden preconditioning blocks when the initial covariance satisfies a spectral support gap condition. This condition encompasses positive definiteness while still allowing for singular initializations. For an initial covariance $\Sigma_0 = \sigma^2 \mathrm{Id}$, the loss converges to the global minimum with linear rate at least $4\sigma^2\kappa$, where $\kappa$ is the PL constant. We establish stability of this rate under finite-width sampling, as well as global convergence of factor gradient descent for an explicit stepsize interval depending on smoothness, the initial loss, and conserved spectral margins. Our argument extends layerwise to deep linear ResNets, subject to a residual-path bound. In the case of heavy-ball momentum, training dynamics close instead over positions and velocities in terms of a lifted phase covariance. Linear convergence holds under an explicit condition on the energy and damping, specifying a window of admissible dampings. For two-scale white initializations, this interval is nonempty for sufficiently large position scales, with a fixed initial loss gap and velocity covariance. Numerical experiments illustrate the covariance geometry and compare the predicted and observed rates.
It is found that Llama 3 delivers comparable quality to leading language models such as GPT-4 on a plethora of tasks, and performs competitively with the state-of-the-art on image, video, and speech recognition tasks.
This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.
F. Xia, Amir Zamir, Zhi-Yang He et al.· 2018 IEEE/CVF Conference on...· 1,069 citations· ⚡112
This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduNov 6, 2026
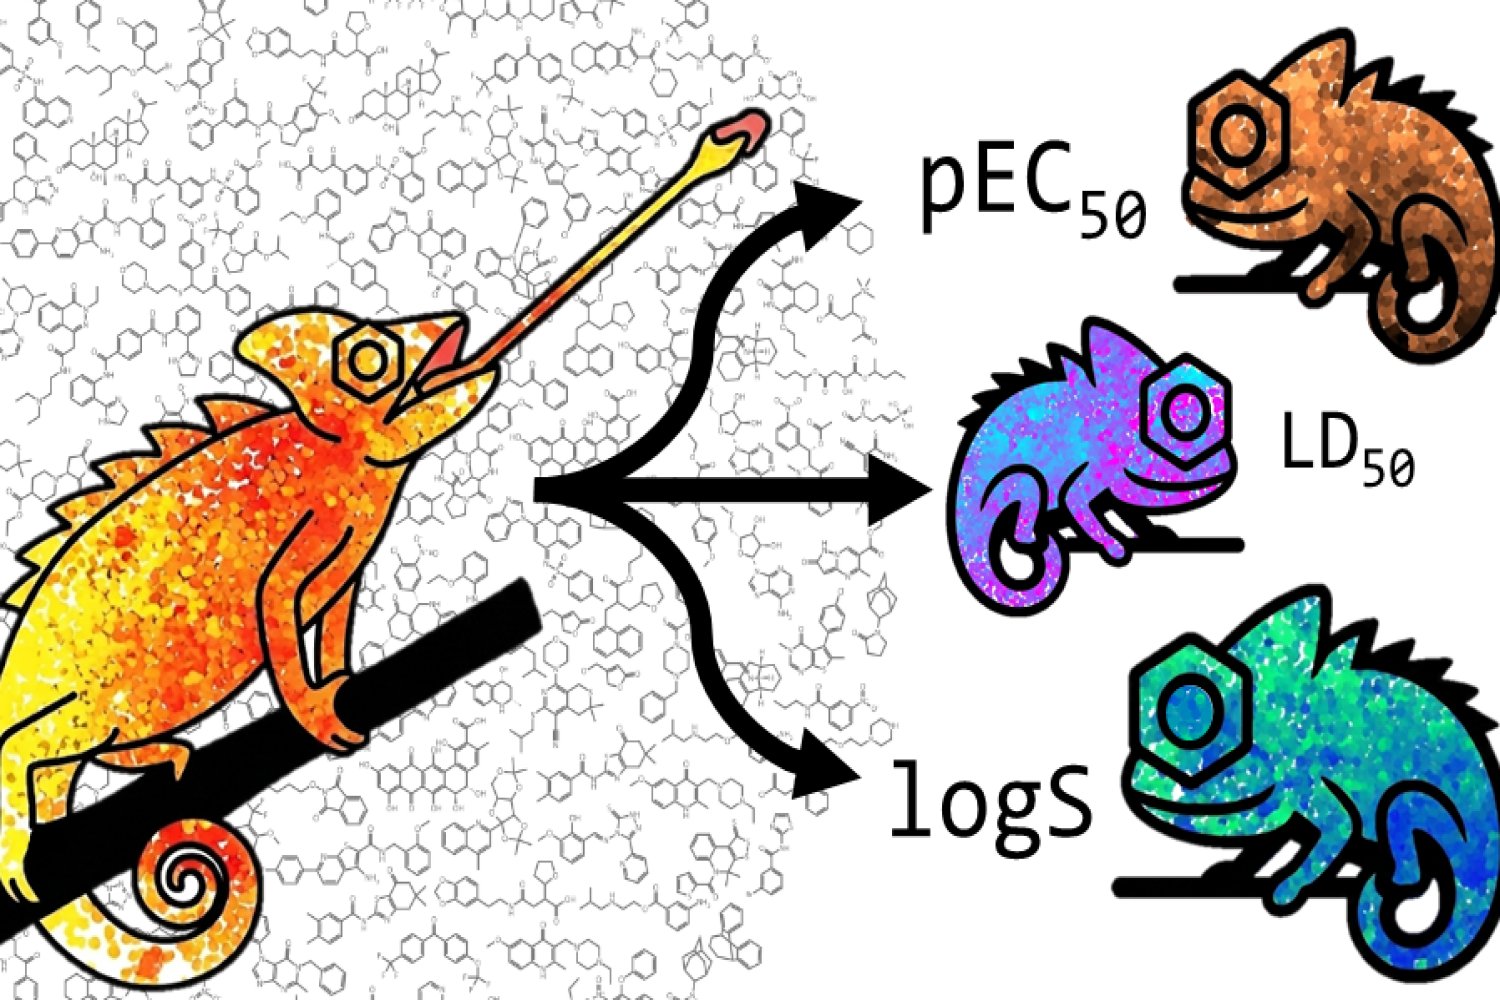
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.