Skip to content

Which LLM for Which Work? Budgeted Model Allocation under Uncertain Evaluation

Aug 2026 · 0 citations · 34 references
Computer Science Mathematics

TL;DR

CAS (causal active sequential experimentation), which targets evaluation to model-workload pairs and repeats the test as evidence accumulates, to ask whether one assignment stays optimal across every quality table consistent with the evidence.

Abstract

A company with a fixed artificial intelligence (AI) budget must decide which large language model (LLM) handles each recurring workload. What it lacks is the quality table, how well each model performs on each workload. Given that table, the decision is a multiple-choice knapsack problem and is routine to solve, so estimating it is the difficulty, and that estimation fails in two ways. Models are rarely compared on the same work, and the recorded score is usually a proxy rather than the outcome the company values. Causal and off-policy methods repair the first but condition on the second, while evaluator-validation methods estimate the second but stop short of the decision. Worse, buying more re-evaluation cannot settle the second: randomization governs which requests are scored, not how a score is produced, so the table stays uncertain however much evaluation is purchased. Yet the deployment decision may still be determined even when the table is not. We therefore ask whether one assignment stays optimal across every quality table consistent with the evidence. For the fixed-budget problem, this admits an exact two-solve certificate: solve once at the estimated table and once at a least-favourable table. Agreement certifies the assignment; disagreement identifies the model-workload pairs where further evidence can matter. We propose CASE (causal active sequential experimentation), which targets evaluation to those pairs and repeats the test as evidence accumulates. On a production log, the measurement failure is the larger of the two: correcting assignment exactly still leaves most of the loss, and randomized re-evaluation does not remove it. In our experiments, the available evidence often does not determine the assignment. On paid software tasks, better information about model quality yields more savings than further optimization of the assignment on the same estimates.

View source

Similar papers

Review Open access Sep 2026

Automatic Model Selection Based on Task Complexity

An Adaptive Intelligence Router is set out that chooses among deterministic programs, retrieval and service interfaces, small language models, more capable language models, more capable language models, and accountable human review.

L. Santhanam · 0 citations
Preprint Aug 2026

LLMs Can Design Near-Optimal OR Algorithms

For the well-specified operations problems the authors study, a single untuned LLM query can already produce algorithms competitive with specialized methods, suggesting that frontier LLMs can be a serious empirical baseline for algorithm design in well-specified OR problems.

Jackie Baek · 0 citations
Preprint Aug 2026

EcoAgent-Bench: Evaluating Economic Decision-Making in Budget-Constrained LLM Agents

EcoAgent-Bench is introduced, in which every task specifies priced actions and an explicit budget, and results show that completion under a budget and economical action selection are distinct properties.

Jie Wu, Ming Gong, Feixiang Cheng et al. · 1 citation
Preprint Aug 2026

CoBa: Cost-Effective Test-Time Scaling via Compute-Balanced Routing

This paper formulates test-time reasoning as a compute-allocation problem in which a system must decide whether the next unit of compute should be spent on generation, verification, or stopping, and introduces CoBa, a compute-balanced routing policy that first obtains a small set of candidates, applies cheap verificati...

Yan Zhou, Yue Ouyang, Kaiyang Zheng et al. · 0 citations
Preprint Aug 2026

Sampling Luck Masquerades as Allocation Gain: Auditing Test-Time Budget Allocation for Neural Combinatorial Optimization

Neural combinatorial optimization (NCO) solvers report the best of many sampled solutions per instance, and the sample count is, by convention, identical for every instance. Whether a non-uniform allocation of a fixed total budget would buy anything has not been measured. We measure it, and we audit the measurement its...

Ji-Woo Bae · 0 citations

Related blog posts

Microsoft Research Blog Oct 12, 2026

Simulating student learning for better AI tutoring

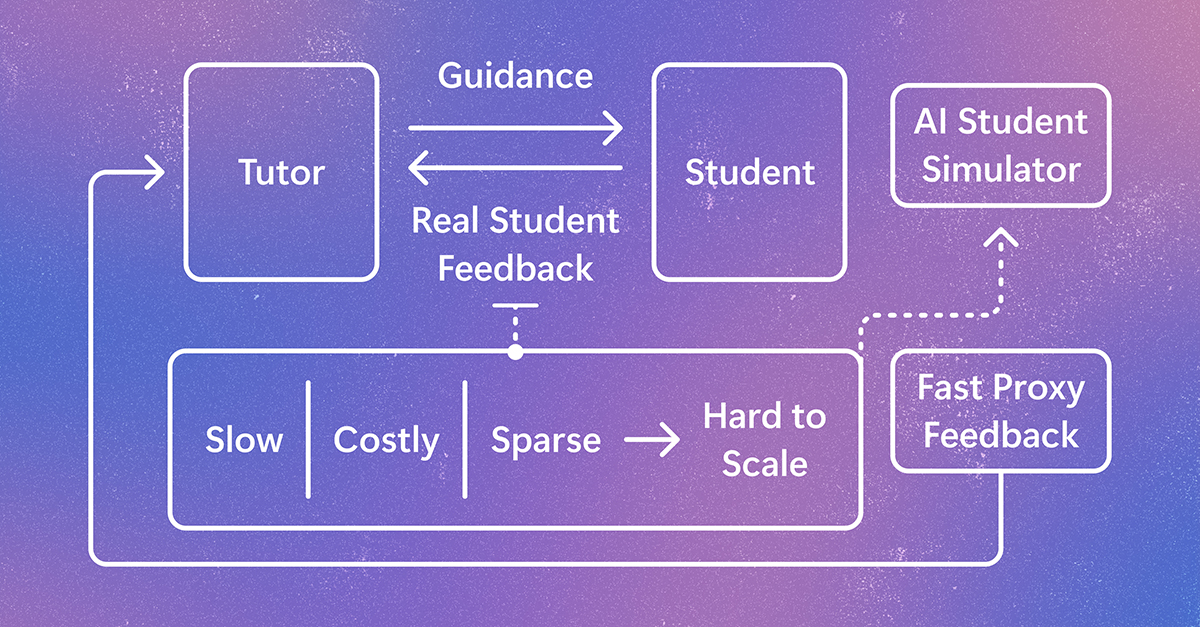
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.