Skip to content

Data Diversity, Not Frequency Invariance: A Controlled and Self-Audited Study of Compression-Robust Deepfake Detection

Aug 2026 · 0 citations · 36 references
Computer Science

TL;DR

Match controls on training recipe as well as capacity, and buy compression robustness with codec diversity before architecture, and buy compression robustness with codec diversity with codec diversity before architecture.

Abstract

Frequency features and compression-invariant representation learning are widely assumed to be key to deepfake detection that survives video compression. We test this with CAFRL - block-DCT and FFT-phase streams, compression-level-conditioned band attention, and adversarial (gradient-reversal) compression invariance - and report a controlled negative. Under a pre-registered protocol with capacity- and augmentation-matched controls, a plain EfficientNet-B0 on multi-quality data beat CAFRL as specified at every compression level on the FaceForensics++ test split, by 3.66 AUC points at CRF 40 (paired, single seed). A self-audit of our own negative found four defects biased against the frequency hypothesis, and pre-specified re-tests repairing all four showed the deficit to be a recipe artifact, not an architecture failure: the baseline recipe recovered 3.96 points over the matching shipped-recipe variant. The frequency path made no detectable difference: discriminative alone (standalone validation AUC 0.91-0.98 late in training) but of no marginal value under this fusion, at two feature widths of one 4.0 M trunk, every seed-pooled interval for the intra-dataset compression contrasts including zero; on the single held-out manipulation tested, the fair variants sat below the plain backbone. The adversarial branch, as specified, added nothing and degraded its own conditioning estimator; at the fair recipe it is untested. Robustness under single-pass H.264 re-encoding came instead from data diversity: real constant-rate-factor variants beat synthetic JPEG augmentation by 7.3 points (single runs, non-overlapping intervals). The evidence is FaceForensics++-family, GAN-era and single-codec. Match controls on training recipe as well as capacity, and buy compression robustness with codec diversity before architecture.


View source

Similar papers

Preprint Sep 2026

GenTraceBench: A Benchmark for Tracing Audio Deepfakes Across Pre- and Post-training Stages

Modern text-to-speech (TTS) systems are rarely deployed as unchanged pre-trained models. They are often adapted through supervised fine-tuning (SFT) or preference optimization such as DPO and GRPO. This raises a practical question for audio deepfake forensics: do fingerprints learned from a foundation generator remain...

Li Wang, Kun-Yu Feng, Wan Lin et al. · 0 citations
2026

A Confidence-Aware Semi-Supervised Learning Framework for Automatic Modulation Recognition

Automatic modulation recognition (AMR) is a cornerstone of dynamic spectrum allocation and cognitive radio. Despite the promise of deep learning-based methods, their reliance on large labeled datasets limits their practicality in scenarios with scarce labeled samples. To address this, we propose a confidence-aware semi...

Hai-Bin Zhang, Jia-Le Wang, Chao Wang et al. · 0 citations
Preprint Sep 2026

Collapse, Not Invariance: Diagnosing Auxiliary Objectives in Speech Anti-Spoofing

Speech anti-spoofing countermeasures degrade when the generator, codec or channel changes, and a common remedy is an auxiliary objective that shapes the embedding space; whether it does is invisible to EER, a pure ranking metric. We compare seven such objectives with cross-entropy over 113 runs on five corpora, AASIST3...

Ksenia Lysikova, Kirill Borodin, Maxim V. Maslov et al. · 0 citations
Conference Aug 2026

Entropy-guided test-time augmentation based on large language model for secret point recognition

In the domain of confidentiality management, secret point recognition stands as a precise and efficient technical solution. However, it faces significant hurdles in machine learning-based implementations: stringent confidentiality constraints on confidential data and restricted data accessibility often lead to insuffic...

Zhendong Wu, Hu Li, Liang Zhang et al. · 0 citations
Preprint Sep 2026

Feature-Aware Token Attack for Compression-Triggered Stealthy Failures in Large Vision-Language Models

This work proposes Feature-Aware Token Attack (FATA), which couples attention suppression with cosine-based feature preservation on a fixed set of salient clean-image tokens and has the lowest measured detection rate among four attacks across three evaluated detectors at a 5% false-positive rate.

Shilinlu Yan, Bo-Wen Chen, Yuechen Zhang et al. · 0 citations

Related blog posts

MIT News · Artificial Intelligence Oct 28, 2026

Making machines that can listen

Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.

Microsoft Research Blog Aug 11, 2026

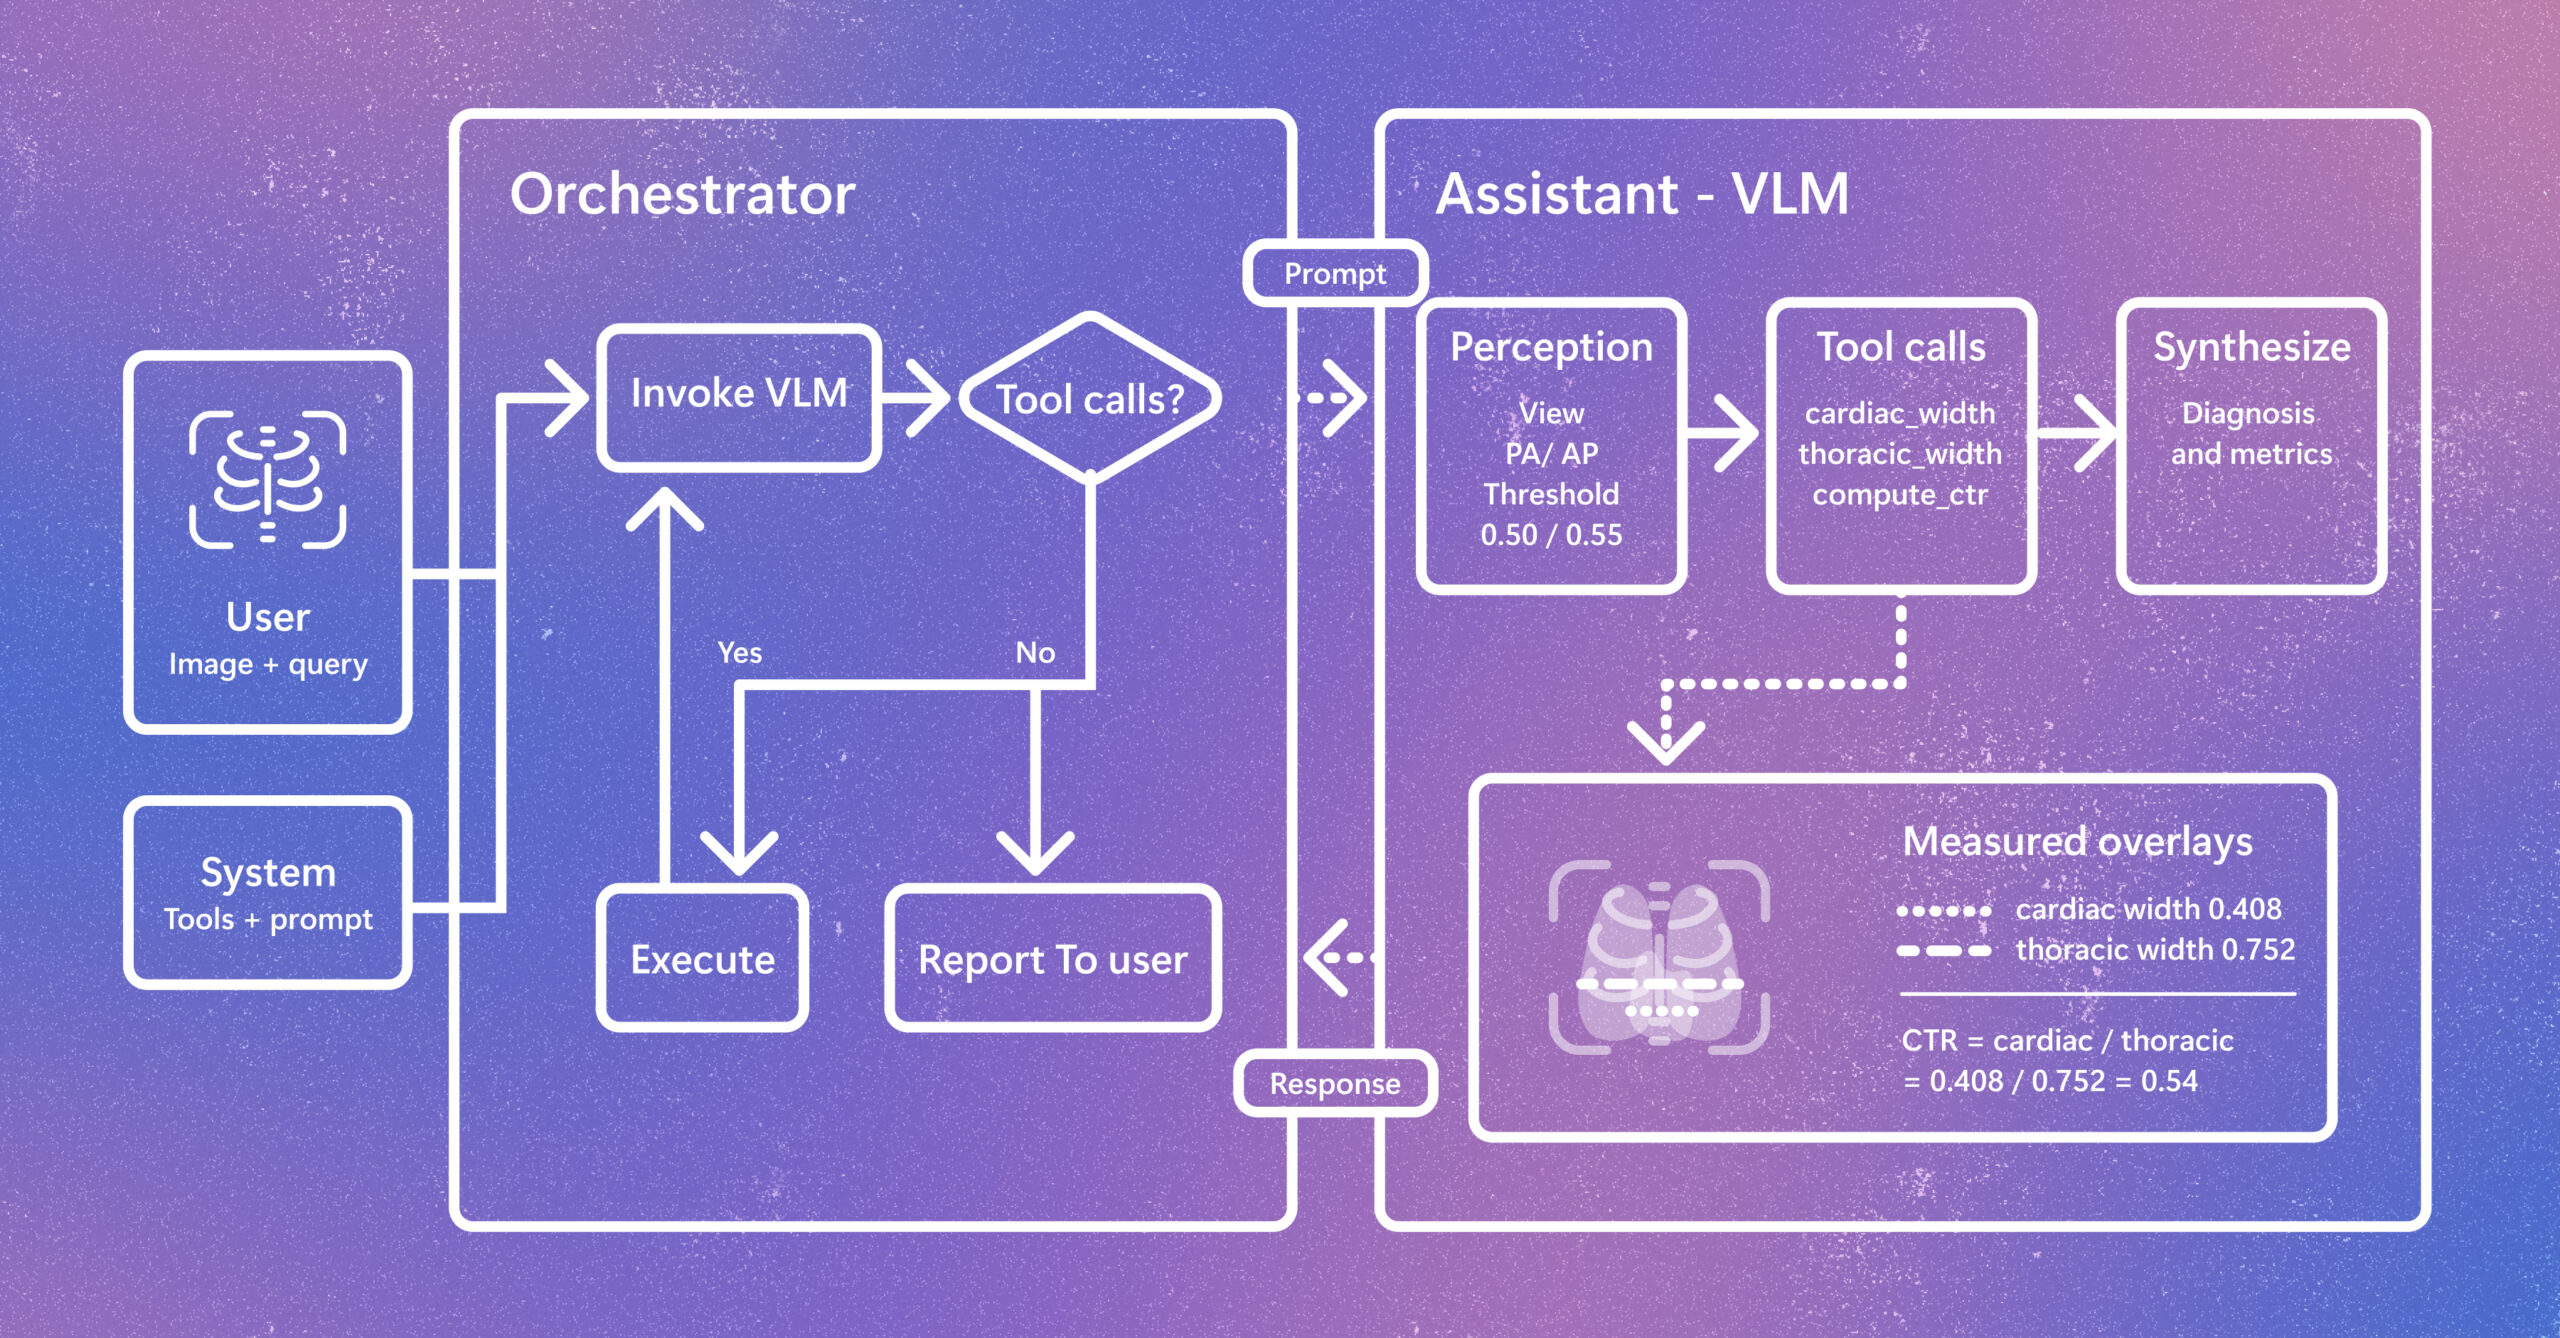
Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.