This paper presents a comparative study of segmentation architectures, ranging from convolutional backbones to vision transformers, applied to the B.O.V.I.D. dataset, a corpus of high-resolution bovid dental photographs paired with hand-made segmentation masks not originally designed for ML-based training, and evaluates a range of preprocessing and alignment techniques to mitigate the resulting label imperfections.
Abstract
Semantic segmentation decomposes an image into distinct mask regions corresponding to different object categories, such as people, cars, signs or buildings. Advances in machine learning (ML) have shifted this task away from traditional rule-based heuristics such as edge detection, towards deep neural networks (DNN) that learn to classify pixels directly. However, semantic segmentation DNNs crucially depend on expertly designed mask targets to learn from, and imperfect or misaligned masks can interfere with a model's ability to learn effectively. This paper presents a comparative study of segmentation architectures, ranging from convolutional backbones to vision transformers, applied to the B.O.V.I.D. dataset, a corpus of high-resolution bovid dental photographs paired with hand-made segmentation masks not originally designed for ML-based training. We evaluate a range of preprocessing and alignment techniques to mitigate the resulting label imperfections. We find that while these preprocessing choices have limited effect on quantitative metrics such as Dice score and mIoU, their qualitative impact on predicted masks is substantial.
Segmenting bruises is a challenging task in medical imaging due to limited data and annotations, diffuse boundaries, and highly variable appearance. In this work, we propose BruNet, a segmentation framework that combines a ViT-based visual encoder (a self-supervised DINOv3 or a pretrained LingBot-Vision backbone) with...
Qi-Ming Wang, Richard J. Motley, E. E. Obi et al.· 0 citations
This study presents the development, training, and comparative evaluation of a U-Net-based convolutional neural network for pixel-level semantic segmentation of surface defects on structural components in nuclear reactor environments. Four defect classes are considered: cracks, corrosion, voids/pores, and background. D...
Miroslav Avramov, V. Gancheva· IOP Conference Series: Earth...· 0 citations
EpigraphNet, a segmentation-guided transformer pipeline evaluated on the Persepolis Fortification Archive, is introduced, and a lower Spearman correlation between sign frequency and per-class performance indicates more balanced recognition across frequent and rare classes.
Utsav Poudel, Rasik Bhattarai, Siddhartha Pathak et al.· 0 citations
Weakly Supervised Semantic Segmentation (WSSS) learns pixel-level predictions from image-level tags. Recent work focuses on improving coarse CAMs extracted from large vision-language models (commonly CLIP), but does little to improve their accuracy along segment boundaries. That job is instead delegated to a post-proce...
Instance segmentation requires precisely outlining object boundaries in images using polygonal masks. Conventional single-scale annotations often fail to represent multi-scale appearance variations, which limits segmentation accuracy and reduces the semantic richness available to learning algorithms. We introduce Small...
Adem Kosar, O. Korkmaz, Tolga Turay et al.· Scientific Reports· 0 citations
This work proposes CMAE-UNet, a camouflage suppression and edge enhancement model based on the UNet architecture that robustly withstands field interference, providing strong technological support for automated tomato detection, intelligent harvesting, and growth monitoring.
Jian-Hua Zheng, Huang-Hui Zhao, Xiaoshan Ma et al.· AgriEngineering· 0 citations
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
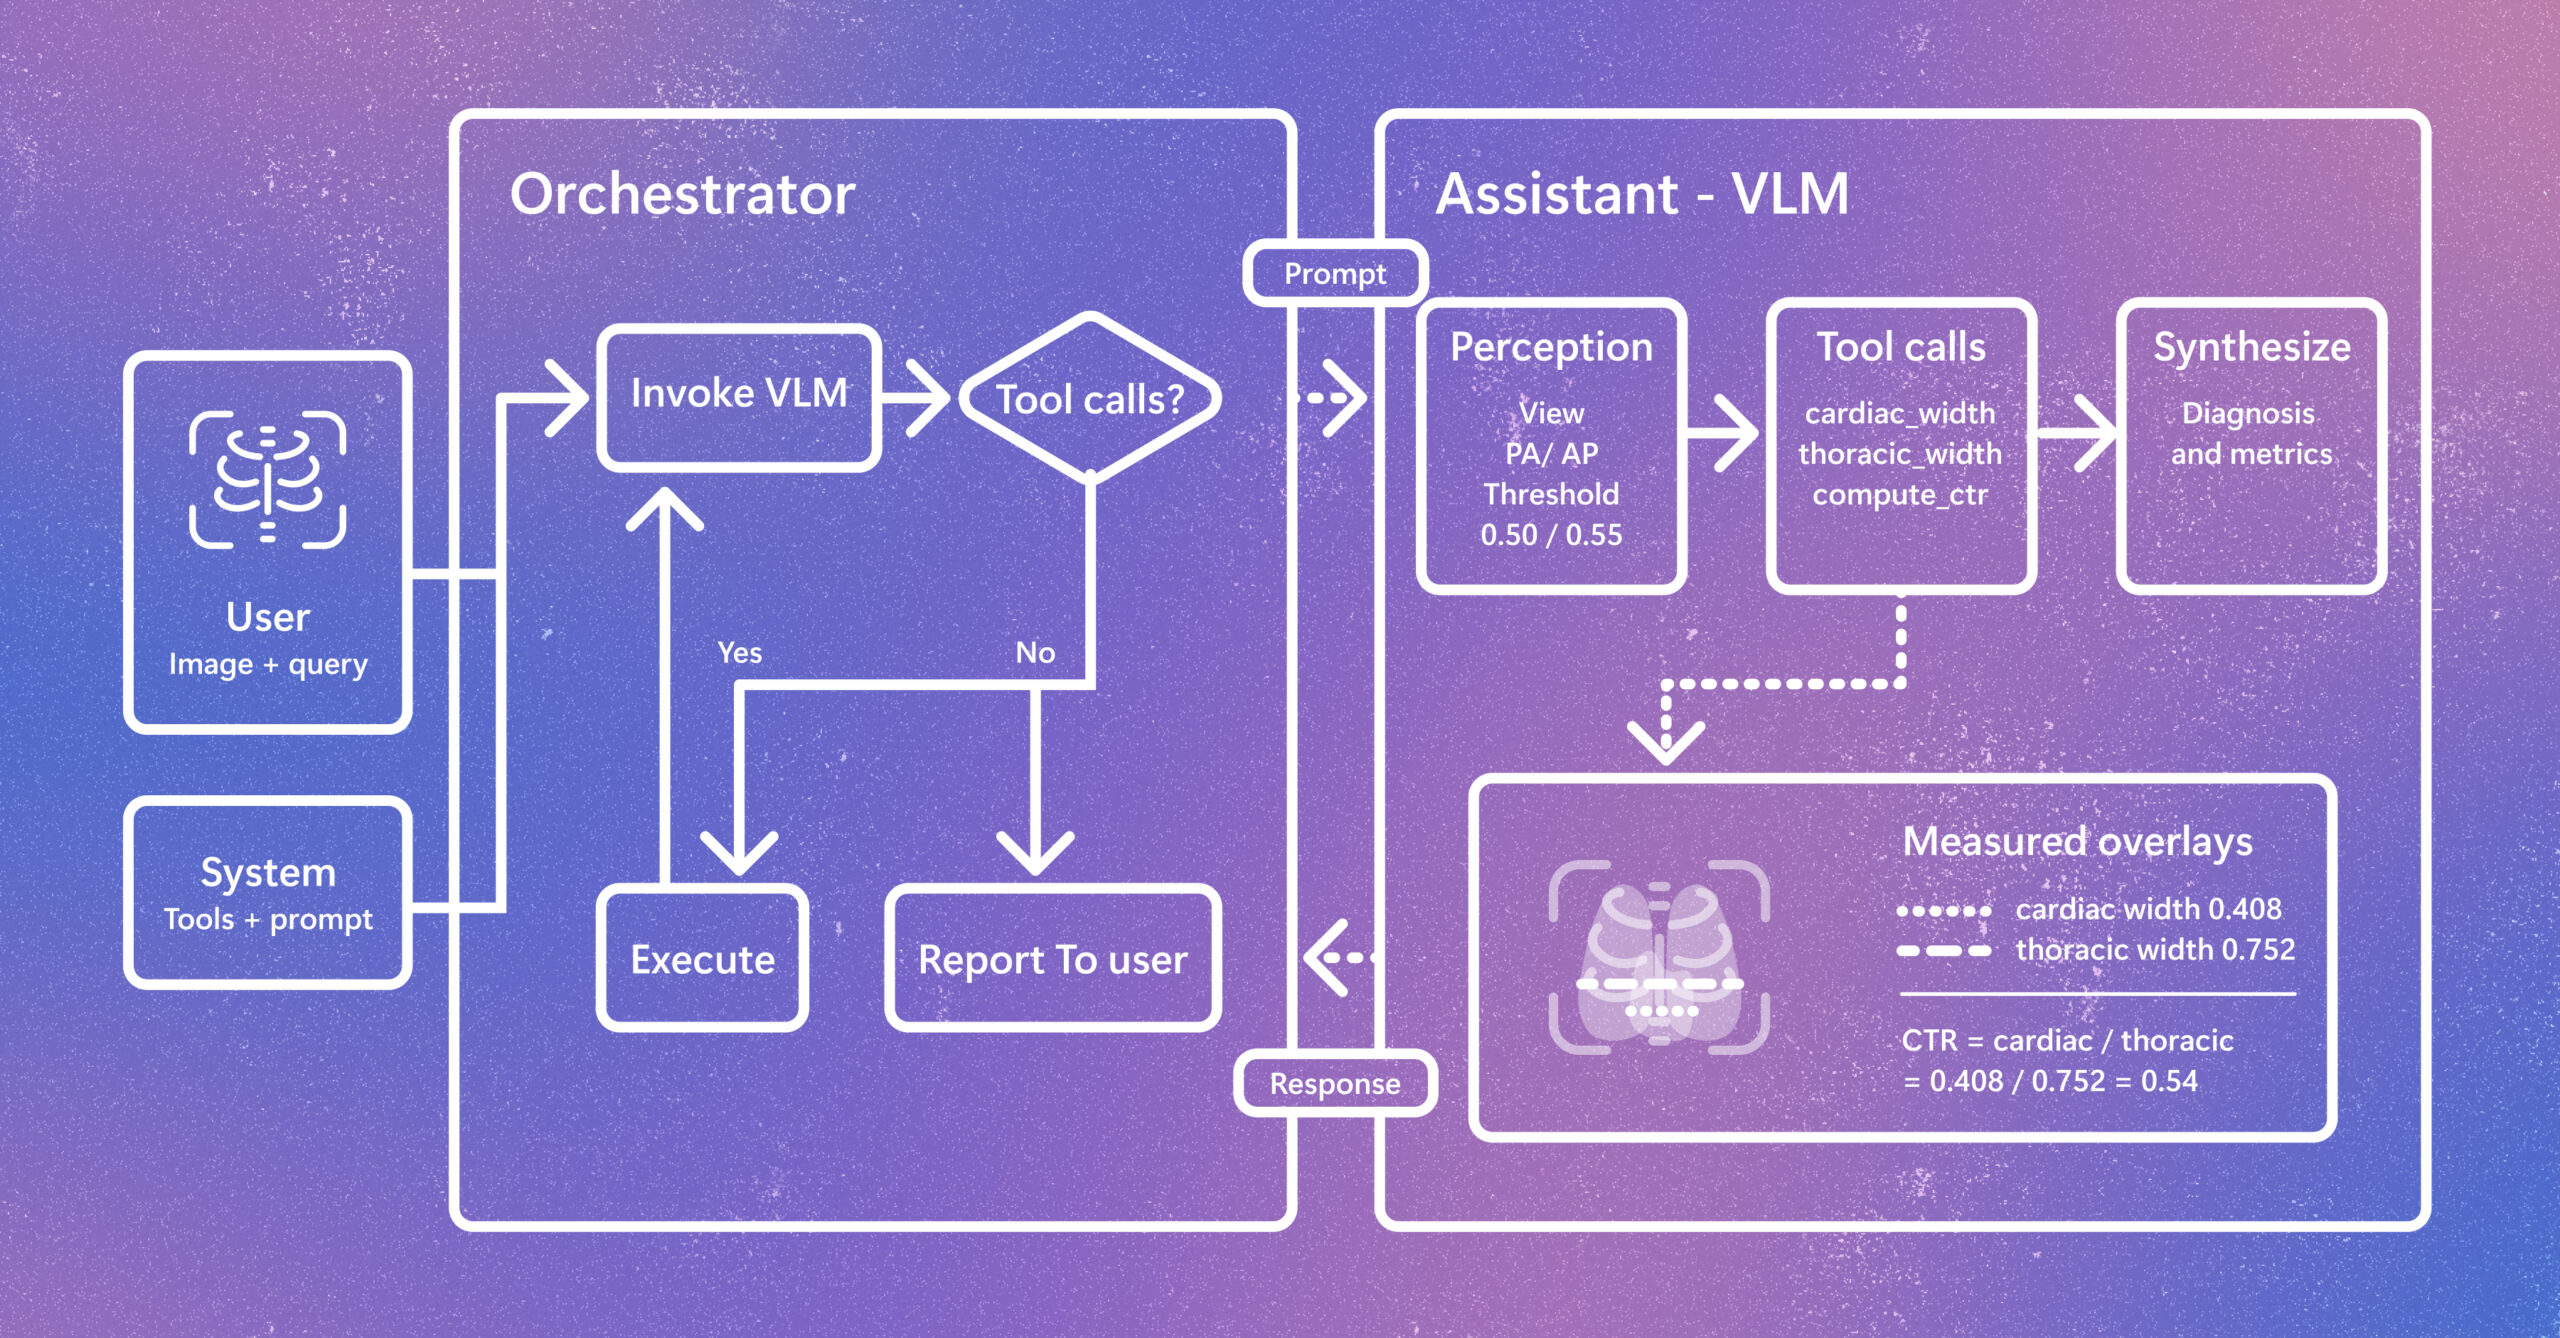
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.