Nov 2026· IEEE Transactions on Computer-Aided Design of Integrated Circuits and Systems· Vol 45, pp. 6364-6377· 1 citation· 39 references
Abstract
Owing to the inherent advantages of edge computing in latency, privacy, and always-on availability, deep neural network (DNN) tasks are progressively shifting to edge devices. However, limited edge resources pose significant challenges for deploying large DNNs. Pipeline parallelism (PP) and post-training quantization (PTQ) are essential techniques for addressing these resource constraints, and mainstream frameworks (e.g., DeepSpeed, PyTorch) encapsulate them independently. Nonetheless, this decoupled treatment inevitably traps the optimization process into local optima and results in inferior throughput-accuracy tradeoffs in heterogeneous edge environments, due to the natural circular dependency between the PP and PTQ optimization processes. To this end, we propose MP3, a novel framework for joint PP-PTQ optimization in heterogeneous edge environments. MP3 integrates three core components: 1) task-device co-analyzer (TDC) utilizes a fine-grained modeling method to estimate computation and communication latencies precisely; 2) information-fused accuracy proxy (FAP) characterizes quantized DNN accuracy through a unified proxy combining intralayer and interlayer information, with a data-driven fusion function search strategy; and 3) pipeline quantization co-optimizer (PQC), leveraging latency estimates from TDC and accuracy characterizations from FAP, navigates the joint optimization space effectively by formulating it as a constraint programming (CP) problem. A comprehensive experimental evaluation on an edge testbed confirms the effectiveness of MP3, demonstrating that it lies on a superior Pareto curve (achieving up to $3.2\times $ throughput speedup with accuracy drop within 1%) and exhibits robust adaptability across heterogeneous devices.

HDA-MoE is presented, a framework that optimizes MoE execution on NMP architectures through hybrid parallel deployment and runtime scheduling and integrates an offline hybrid parallel mapping algorithm with an online dynamic and adaptive scheduling mechanism to reduce communication overhead while improving computation...
Hao-Chen Huang, Shu-Zhang Zhong, Sheng-Xuan Qiu et al.· IEEE Transactions on Compute...· 0 citations
Large Language Model (LLM) inference has become the dominant workload in modern AI systems, requiring serving infrastructures to maximize throughput while meeting strict latency Service-Level Objectives (SLOs). Since state-of-the-art LLMs exceed the compute and memory capacity of a single GPU, inference is commonly dis...
OmniPipe is proposed, a flexible bidirectional multi-pipeline parallelism scheme for unified dense and MoE LLM training that minimizes the pipeline bubble ratio while effectively overlapping EP communication with computation, enabled by the flexible and scalable parallelism scheme of bidirectional pipelines.
Jun Li, Zhi Ma, Shi-Gang Li· International Conference on...· 0 citations
Xronos is proposed, a collaborative fine-tuning framework for heterogeneous CPU edge devices that uses TP as its execution backbone and combines lightweight profiling with heterogeneity-aware tensor partitioning to reduce the straggler bottleneck.
Wonmi Choi, Sunjae Park, Dohyeok Kwon et al.· 0 citations
Retrieval-Augmented Generation (RAG) offers a compact yet powerful alternative to massive Large Language Models (LLMs), making it attractive for privacy- and resource-constrained edge deployments. However, orchestrating RAG on devices with limited compute, memory, and power is nontrivial. We address this challenge with...
Deeksha Chaudhary, Cyan Subhra Mishra, Rishabh Jain et al.· IEEE International Symposium...· 0 citations
Machine learning inference is moving to the edge due to latency, energy, and privacy constraints. The growing complexity of edge workloads places increasing pressure on memory hierarchies, making data movement a major limitation for both performance and energy efficiency. Fixed-function accelerators inherit the memory...
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
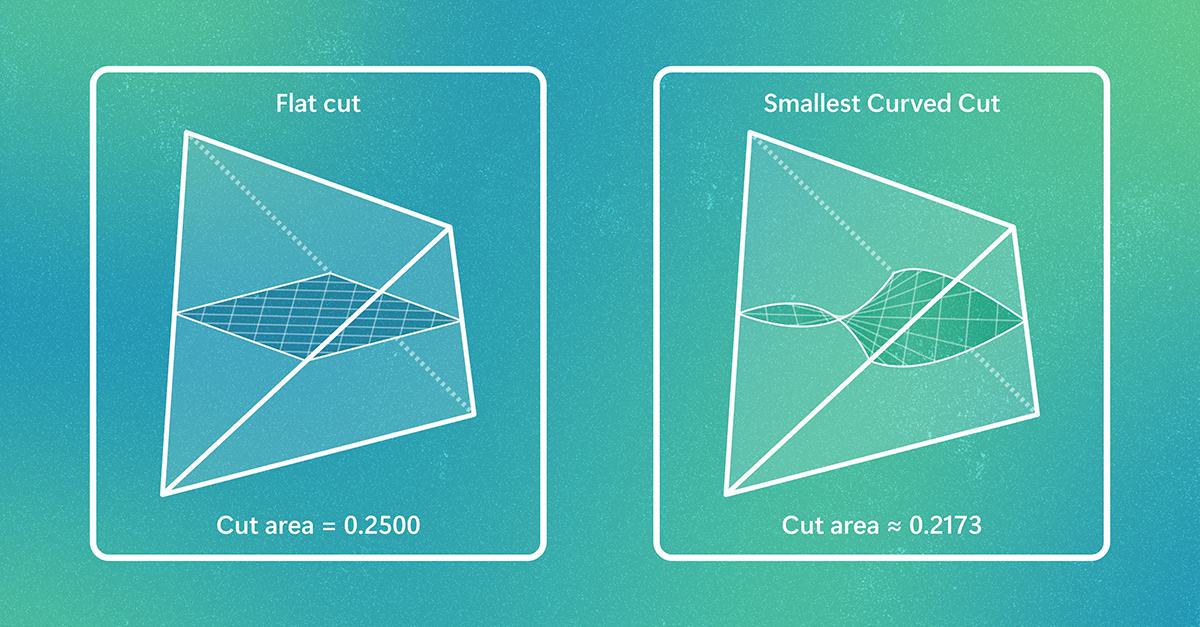
For decades, a fundamental question about the difficulty of computing in high-dimensional spaces has resisted proof. New research resolves this question, removing a major theoretical obstacle to understanding the efficiency of randomized algorithms used across science and computing. The Kannan–Lovász–Simonovits (KLS) conjecture was proposed in 1995. It asks whether, for a broad class of high-dimensional […] The post Solving a 31-year-old grand challenge in mathematics – the KLS conjecture appear…
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.