An automated theorem prover builds a proof step by step, choosing at each point what to add and what to remove, and learns policies that solve up to 46% more problems than leanCoP, and reach proofs in an order of magnitude fewer steps.
Abstract
An automated theorem prover builds a proof step by step, choosing at each point what to add and what to remove. We cast this construction as a policy acting in a transition system induced by a formal calculus, which fixes which steps are sound: for clausal connection tableaux, leanCoP-style search and plCoP/rlCoP-style planning then become stateful policies over one interface, and policy-learning methods apply directly. We equip such policies with a graph neural network that scores proof edits from structure that transfers across problems, train it by imitation learning from found proofs, and measure how performance holds as we remove search scaffolding, from full symbolic backtracking to a policy the network drives alone. Within a fixed step budget on M2k, MPTP2078-bushy, and TPTP v9.2.1, learned policies solve up to 46% more problems than leanCoP, and reach proofs in an order of magnitude fewer steps.
Results support a qualified internalized-search reading: under the recipe the authors test, much of the measured RL gain corresponds to a change in sampling efficiency toward operating points the base model can already reach under search.
Wen-He Sun, Cun-Xiang Wang, Zi-Jun Yao et al.· 0 citations
PLVR (Program Learning with Verifiable Rewards): a post training method that learns such programs directly from input-output examples and is released with the symbolic backpropagation library and a conformance checker so the method can be applied to primitive libraries other than the authors' own.
This model interleaves reasoning, tool calls, and returns in one left-to-right generation, trained by a supervised warm-up and then outcome-level reinforcement learning against a programmatic reward read directly off the gold call chain, which leaves no learned critic and no judge in the training loop.
Armin Dariani, Sifan Wu, Bang Liu et al.· 0 citations
A robot that can be taught a new task from a handful of demonstrations has to work out for itself what it still cannot do, and then ask for exactly that. Interactive imitation learning takes a step in that direction by letting a policy practice on its own and calling an expert when it goes wrong. Existing methods decid...
Suyog Khanal, V. ArunKumarA., Santu Rana· 1 citation
Echo-GRPO is proposed, a framework that lets the model reason in the words it speaks, and idiolectal paraphrasing is a plug-in module that consistently improves both RL and supervised fine-tuning frameworks for reasoning distillation, demonstrating that policy-aligned supervision extends beyond GRPO.
Ji Soo Lee, Jinyoung Park, Seohyun Lee et al.· 0 citations
Results show that organizing solver feedback into generation, verification, and repair roles enables more scalable and faithful annotation-free symbolic planning.
Cheng-Hao Zhang, Yi-Kai Mao, Hao-Yu Gao et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
MIT News · Artificial Intelligence· news.mit.eduJul 15, 2026
Assistant Professor Pat Pataranutaporn describes a new interface that lets everyday users glimpse inside an AI's neural network before their chatbot ever says a word.
Microsoft Research Blog· microsoft.comJul 13, 2026
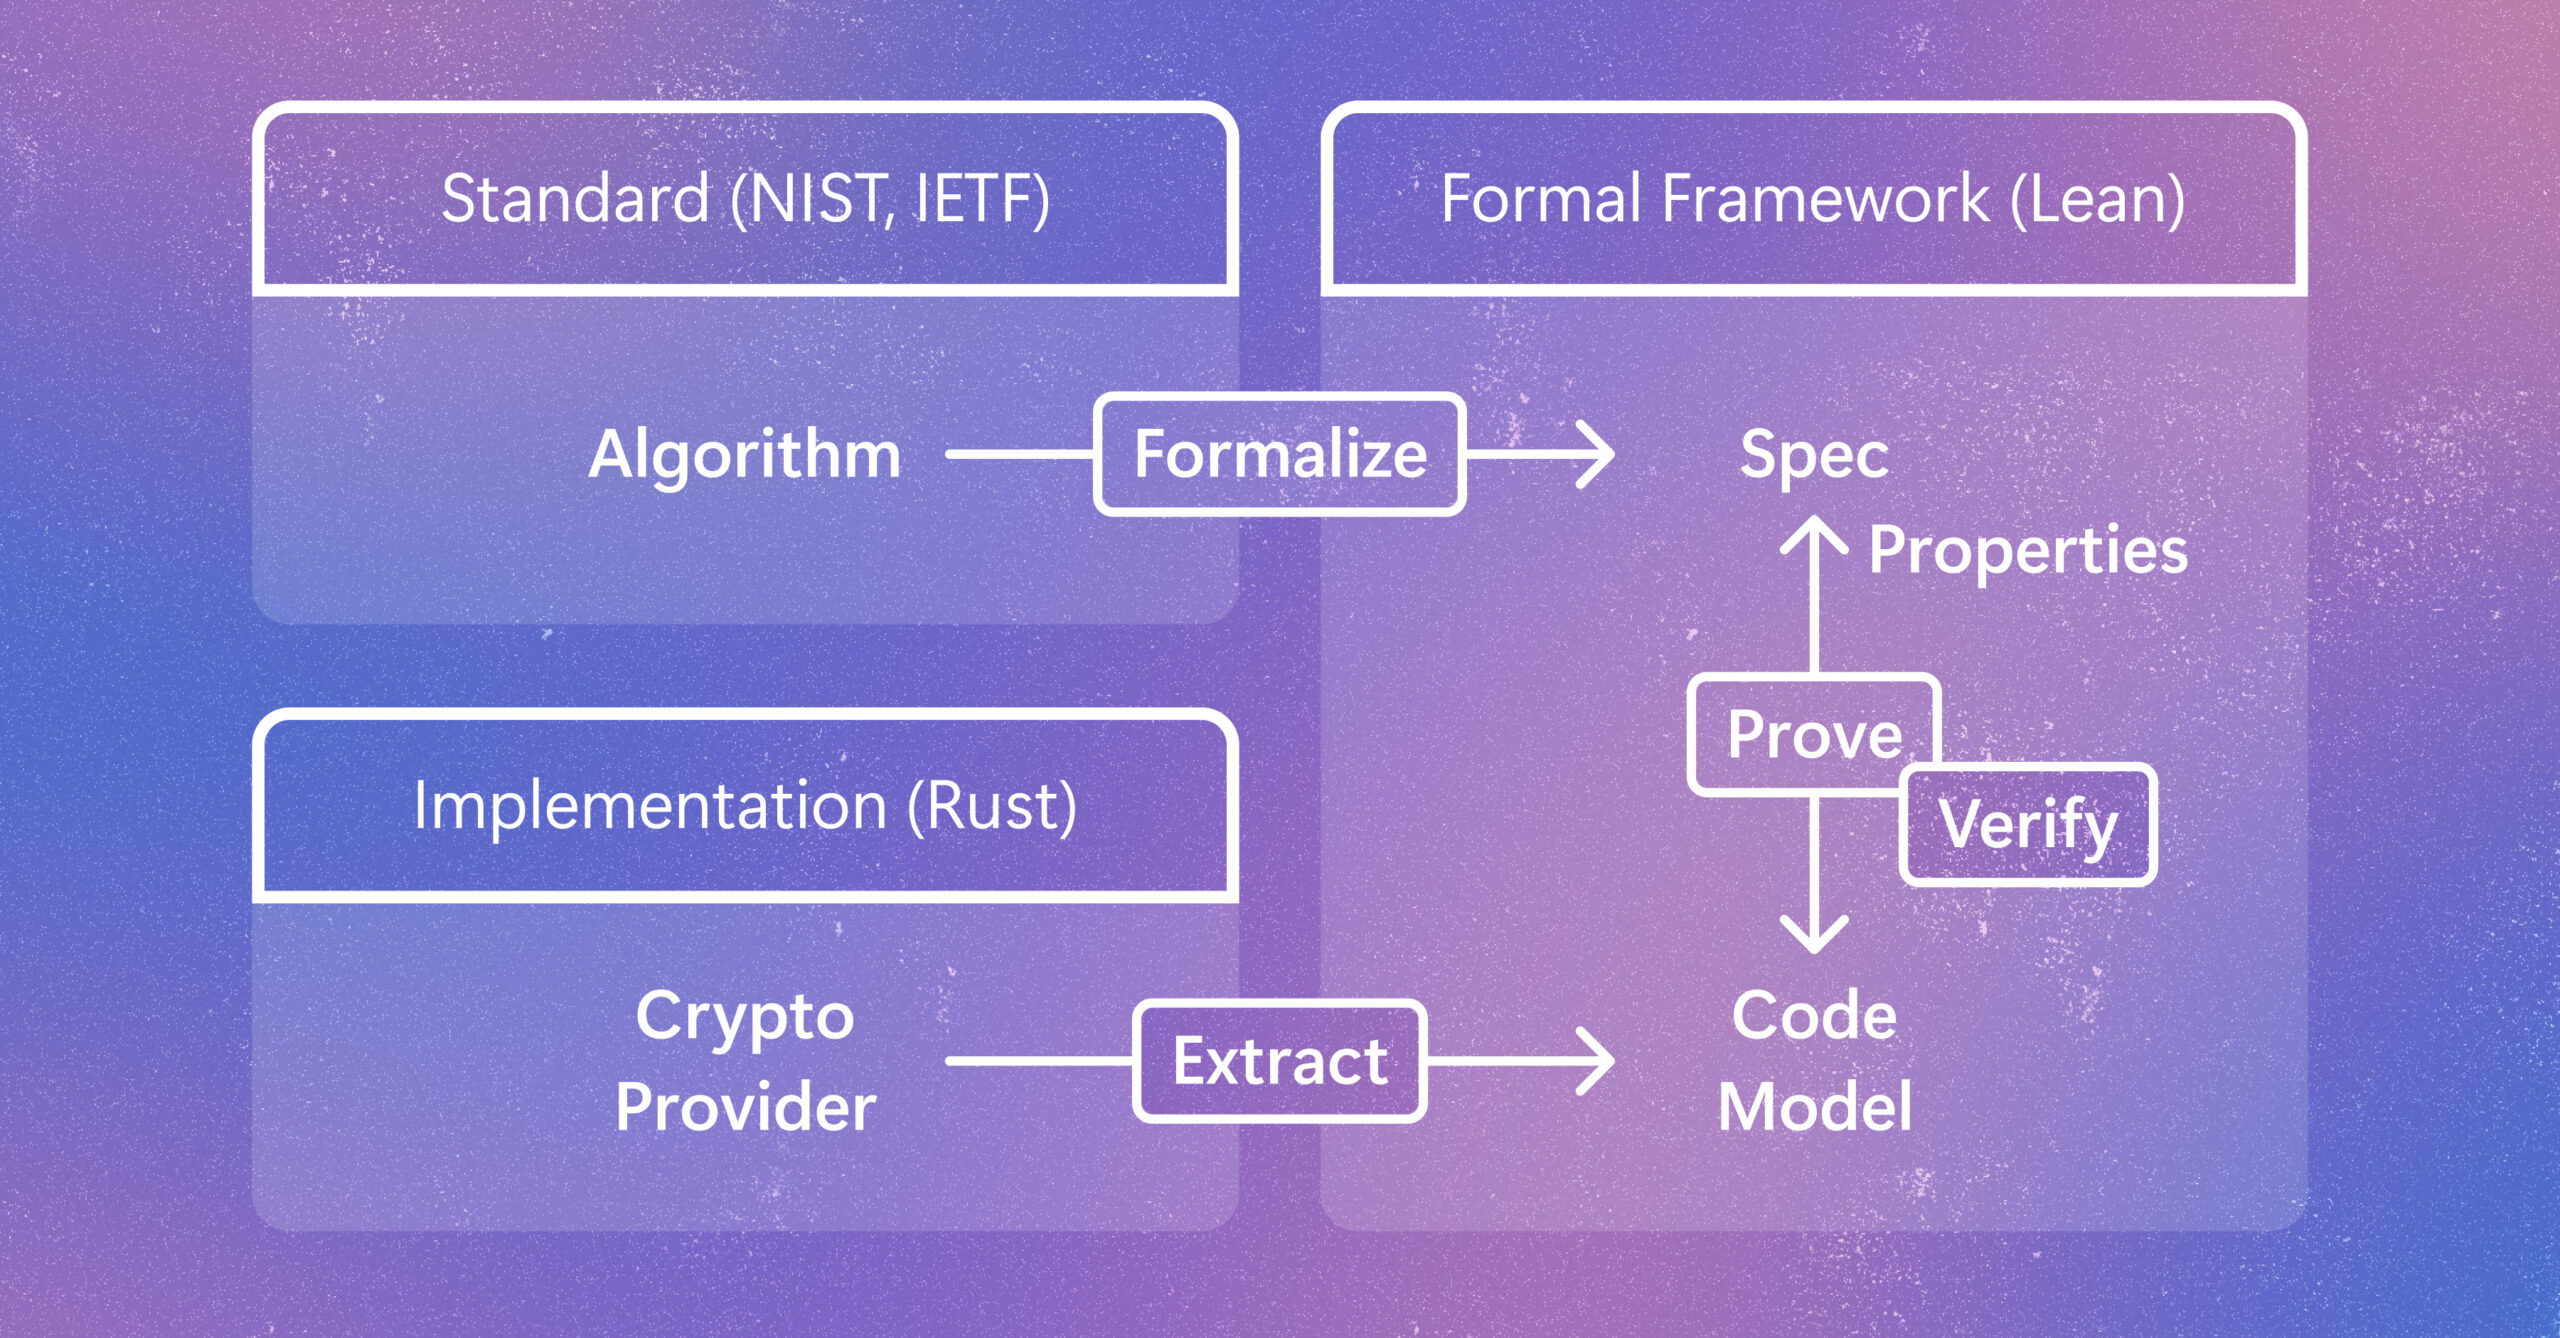
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.