This work proposes a Projected RGD algorithm that achieves dimension-independent linear convergence at unit step size and identifies as unit-step RGD on a totally geodesic submanifold, thereby extending the dimension-independent guarantee to that setting verbatim.
Abstract
The computation of the Bures-Wasserstein (BW) barycenter of an ensemble of positive definite matrices arises throughout machine learning, optimal transport, and quantum information. Riemannian gradient descent (RGD) at unit step size -- the fixed-point iteration used in practice -- converges rapidly, yet existing analyses present a dichotomy: unit-step guarantees carry worst-case exponential dependence on the dimension, while dimension-independent guarantees require small step sizes that forfeit the empirical speed. We resolve this dichotomy, not by improving the guarantees for unit-step RGD, but by proposing a Projected RGD algorithm that achieves dimension-independent linear convergence at unit step size. The achieved rate, $(1 - \kappa^{-3/2})$, where $\kappa$ is the condition number of the ensemble, also polynomially improves on the best small-step guarantee ($\kappa^{3/2}$ versus $\kappa^{5/2}$ iteration complexity). The crux is a novel Projection Lemma: clipping the eigenvalues of a positive matrix to an interval $[\alpha, \beta]$ is the closed-form, non-expansive (1-Lipschitz) BW-metric projection onto the set $\{S : \alpha I \leq S \leq \beta I\}$ -- a statement which, unlike its known one-sided counterpart, does not follow from convexity. The projection is moreover free: it reuses an eigendecomposition the next iteration must perform in any case, so the projected and unprojected iterations cost the same per step. The same analysis covers the invariant matrix projection problem of Brahmachari et al. (2025), whose fixed-point algorithm we identify as unit-step RGD on a totally geodesic submanifold, thereby extending the dimension-independent guarantee to that setting verbatim.
We explore fast convergence of the Riemannian Frank--Wolfe method for smooth geodesically convex optimization over compact feasible sets. Hadamard manifolds are the main setting. On general complete manifolds, the analysis accounts for all feasible minimizing geodesics. We consider the open loop step-size $\eta_k=a/(k+...
Natural gradient descent (NGD) underlies common methods in ML. For dually flat families, idealized NGD on the forward Kullback--Leibler objective follows the mixture geodesic which is often longer than the shortest Fisher--Rao path. We quantify this overhead by the inefficiency ratio \(R \ge 1\), the Fisher length of t...
This work studies Gaussian-restricted barycenters for quadratic two-sided Kullback--Leibler unbalanced optimal transport with independent marginal penalties and no coupling entropy to establish global attainment, derive the stationary moment equations, and construct a reverse-KL majorization--minimization iteration.
An abstract KL principle for conditional expected descent with memory and summable tails using only the ordinary pointwise KL property is developed, which yields almost-sure finite length, whole-sequence convergence, and deterministic KL rates.
Projection-free methods replace projections by linear minimization oracles, making their convergence fundamentally sensitive to the geometry of the feasible region. We develop a geometric framework for this dependence in Riemannian Frank--Wolfe optimization. A power-type double-geodesic modulus quantifies the intrinsic...
This work establishes the first curvature-independent regret guarantees for decentralized online optimization on Hadamard manifolds, and studies Distributed Riemannian Online Gradient Descent, which combines local Riemannian h-subgradient updates with an implicit Fr\'echet-mean consensus.
A weeklong summer workshop brought higher education faculty to campus to explore how AI and machine learning materials can be adapted for their classrooms.
MIT News · Artificial Intelligence· news.mit.eduAug 27, 2026
A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.
Microsoft Research Blog· microsoft.comAug 20, 2026
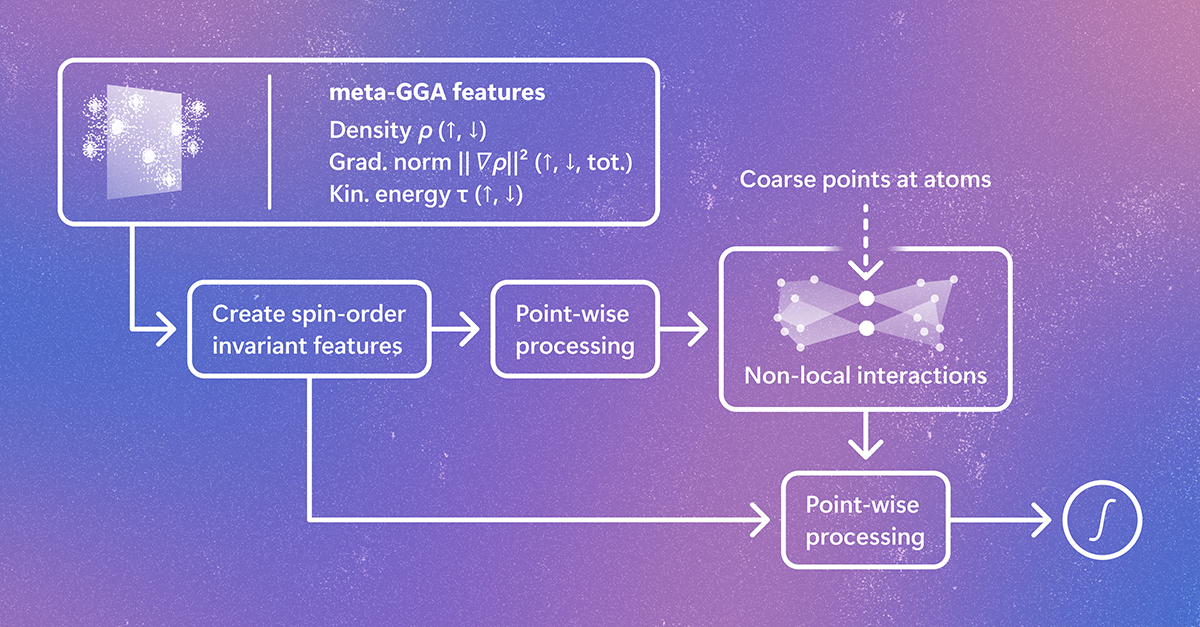
Skala 1.1, the updated deep-learning exchange-correlation functional from Microsoft Research, provides greater accuracy, expanded accessibility across the computational chemistry ecosystem, and a living benchmark to track computational performance. The post Broadening access to Skala creates a faster path to predictive DFT appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.