Aug 2026· 3 citations· ⚡ 1 influential· 23 references
Computer Science
TL;DR
Whether independently implemented training stacks can serve as differential oracles for a whole fine-tuning pipeline, rather than the operators and inference paths that prior differential testing targets, is studied.
Abstract
Neural network training has an oracle problem: a run can converge normally and yield a usable model while the software beneath it computes something other than specified. Almost all such work runs on one stack, so there is rarely anything independent to check against. We study whether independently implemented training stacks can serve as differential oracles for a whole fine-tuning pipeline, rather than the operators and inference paths that prior differential testing targets. We define a trajectory-level protocol -- a shared specification, cross-check points spanning arithmetic, model loading, data rendering and the learning trajectory, and a separation of independence of the stack, the orchestration and the language runtime -- and apply it to a LoRA adaptation of Qwen3-0.6B over 168,574 clinical question-answer pairs under PyTorch and under numbat, an independent framework written in Zig, driven natively and through its C interface from six languages. Across 42 paired evaluations spanning a full epoch the two stacks'held-out cross-entropy differs by 0.134% on average, and four implementations end the epoch within 0.15% of one another. The comparison exposed 17 faults that single-implementation development had missed, two of them notable for software engineering. The fault with the largest effect on the trained model lay outside the numerical kernels: a mismatch in how clinical text was rendered moved held-out loss 0.15, some 500 times more than the arithmetic faults found beside it. And four faults were reachable only from a language whose memory model differs from the first two implementations: a scheduler migrating work across threads, a collector blind to device memory, an ownership discipline needing a primitive the interface lacked. Implementation diversity has several axes, and the runtime is one.
Across medical benchmarks, MedLLM shows a pattern visible only at sub-billion scale: medical competence does not degrade uniformly under compression but splits by task type and dissociation is masked at 7B, where both capabilities are present, and surfaces only when capacity is scarce.
M. R. Rahman, Asim Ahmed, Mihan Mohagheghzadeh et al.· arXiv.org· 0 citations
This tutorial presents OneEHR, an open-source toolkit that defines a unified experiment contract for modern EHR modeling and enables head-to-head comparison among conventional, neural, LLM-based, and agentic methods through a single configuration-driven interface.
Yinghao Zhu, Zixiang Wang, Lei Gu et al.· Proceedings of the 32nd ACM...· 0 citations
ClawBench shows that apparently identical outcomes arise from distinct, independently measurable failure modes, and that trustworthiness in agentic genomics is a property of the pipeline architecture rather than of the model, providing a portable, contamination-resistant unit of attribution for the field.
This entry-level tutorial aims to equip healthcare professionals with the tools necessary to effectively integrate LLMs into clinical practice, ensuring that these powerful technologies are applied in a safe, reliable, and impactful manner.
Qiao Jin, Nicholas Wan, Robert Leaman et al.· Nature Protocols· 1 citation
CAST (Concept-guided Artifact Suppression Tuning), an SAE-based framework for auditable clinical text classification, improves over its corresponding fine-tuned encoder baselines and remains competitive with strong LLM baselines, while producing a feature-level audit trail of the clinical concepts that support each pre...
This work proposes a measure of training data influence that does not require selecting a downstream task or validation set as the attribution target, and defines an example's influence by how much its gradient update reduces the squared distance to the final parameters of a given pretraining run.
Yuto Nishida, Hirokazu Kiyomaru, Yusuke Oda et al.· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comOct 12, 2026
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 6, 2026
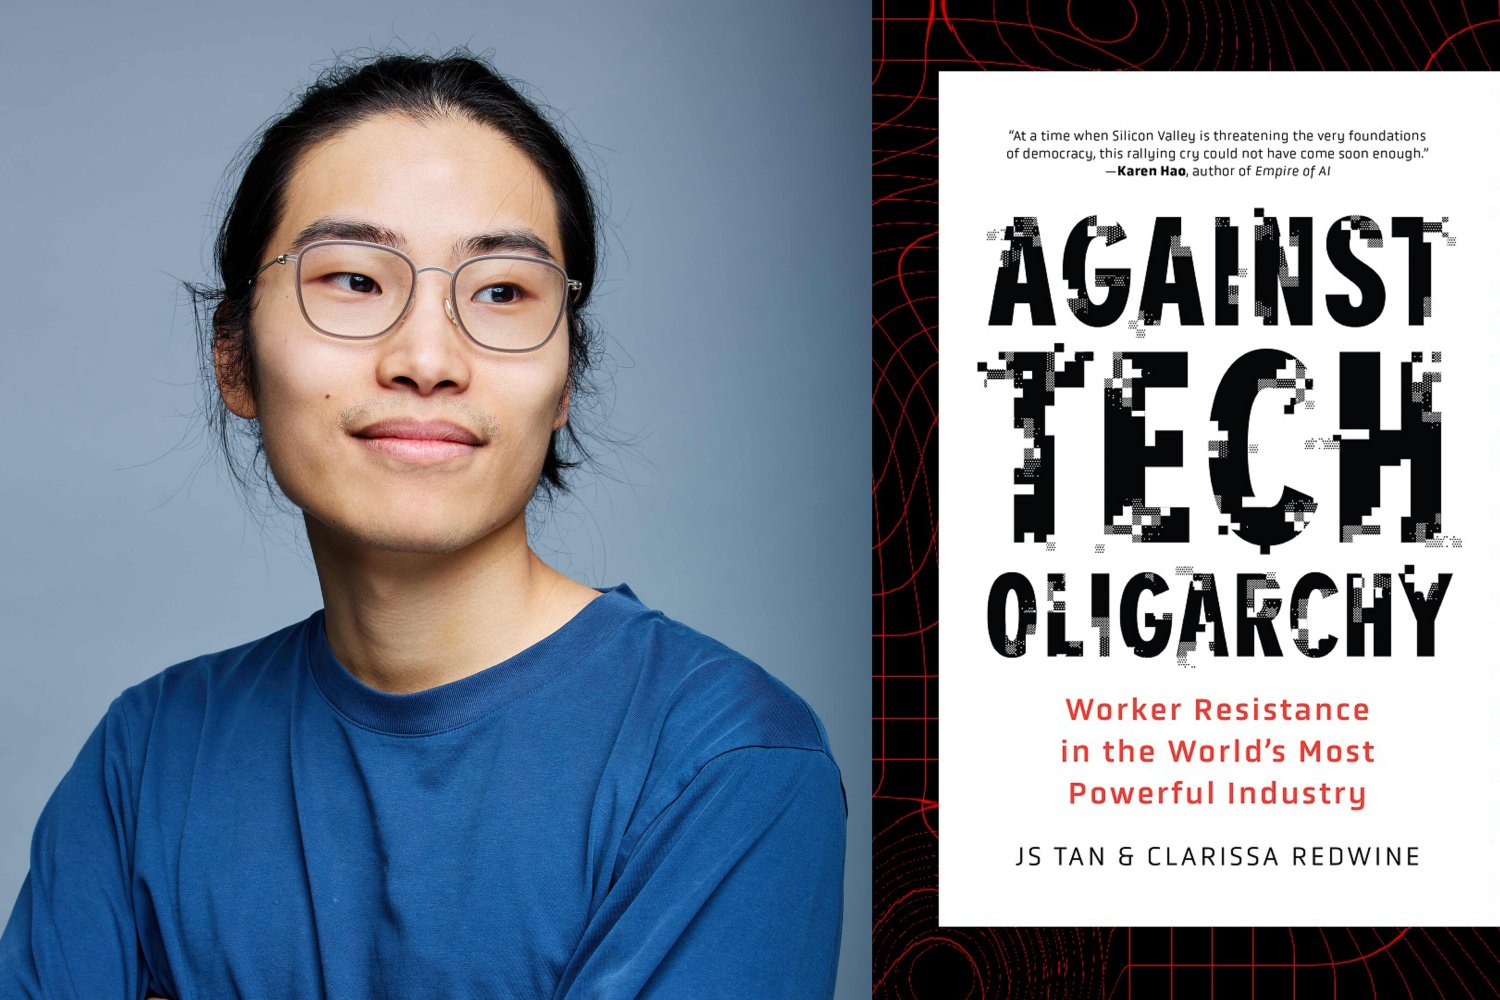
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
MIT News · Artificial Intelligence· news.mit.eduOct 2, 2026
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.