Ternary multiplicative adaptation is proposed, which represents discrete updates of ternary weights such as sign flips or zeroing through a low-rank Kronecker factorization into two small ternary matrices applied element-wise to ternary weights.
Abstract
Ternary transformers offer extreme memory and compute efficiency, but existing low-bit LoRA-based methods cannot directly fine-tune ternary weights. Current approaches either require dequantization, restoring low-bit base weights to higher precision to merge with adaptation weight, or update only quantization parameters, preventing a merged model that remains ternary. We propose ternary multiplicative adaptation, which represents discrete updates of ternary weights such as sign flips or zeroing through a low-rank Kronecker factorization into two small ternary matrices applied element-wise to ternary weights. This design is parameter-efficient and expressive, preserves the ternary domain, and supports direct merging without dequantization. Experiments on six models across language and vision, including ternarized LLaMA-3 1B and 3B and a ternary ViT-B/16, demonstrate that our method recovers much of the performance lost to quantization and outperforms strong low-bit and ternary baselines. Code is available at https://github.com/alexmanoo/ternary_adaptation.
TERINT-GEMV is designed, a multiplier-free bit-serial accelerator that ingests the 6-bit indices directly through an on-chip lookup table, computing ternary × INT8 dot products with dynamic zero-skipping.
Tomas Sousa Pereira, Ruibao Wang, Ikenna Nwozo et al.· International Symposium on L...· 0 citations
As pretrained language models grow, full parameter updates become prohibitively expensive, motivating parameter-efficient fine-tuning (PEFT). LoRA decomposes weight updates into low-rank factors, but its per-module cost $r(m{+}n)$ imposes a structural floor at rank one. FourierFT breaks this floor via frequency-domain...
Sayed Muhsin, Seok-Bum Ko· IEEE Signal Processing Lette...· 1 citation
T-ACE is presented, a Ternary Accuracy-aware Compute Engine that enables efficient ternary LLM inference under PTQ by jointly designing the data representation and execution pipeline and integrates on-the-fly decoding and scaling directly into the ternary GEMM pipeline.
Wonseok Jung, Junseok Kang, Sangwon Shin et al.· International Conference on...· 0 citations
FluxBin is proposed, an algorithm-kernel co-design that synergizes post-training quantization with a highly optimized CUDA kernel and introduces Decoupled Row-Column Binary Decomposition to enhance representational capacity while maintaining hardware efficiency.
Qingyao Yang, Run-Ming Yang, He Xiao et al.· 0 citations
BiSCo-LLM is presented, a codebook-free binary spherical coding framework for extreme low-bit LLM weight compression and its reported storage budget includes binary codes, neural decoders, protected-channel payloads, LoRA adapters, and metadata.
Yuantian Shao, Peisong Wang, Zhilei Liu et al.· arXiv.org· 0 citations
A training-free framework, BAL-ANCER, which achieves global budget allocation for mixed-precision quantization and low-rank correction through information-guided subspace matrices, allowing a principled greedy allocator to distribute compression bits and ranks across the entire model.
Si-Nuo Fan, Ying-Jie Lao· Proceedings of the Thirty-Fi...· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
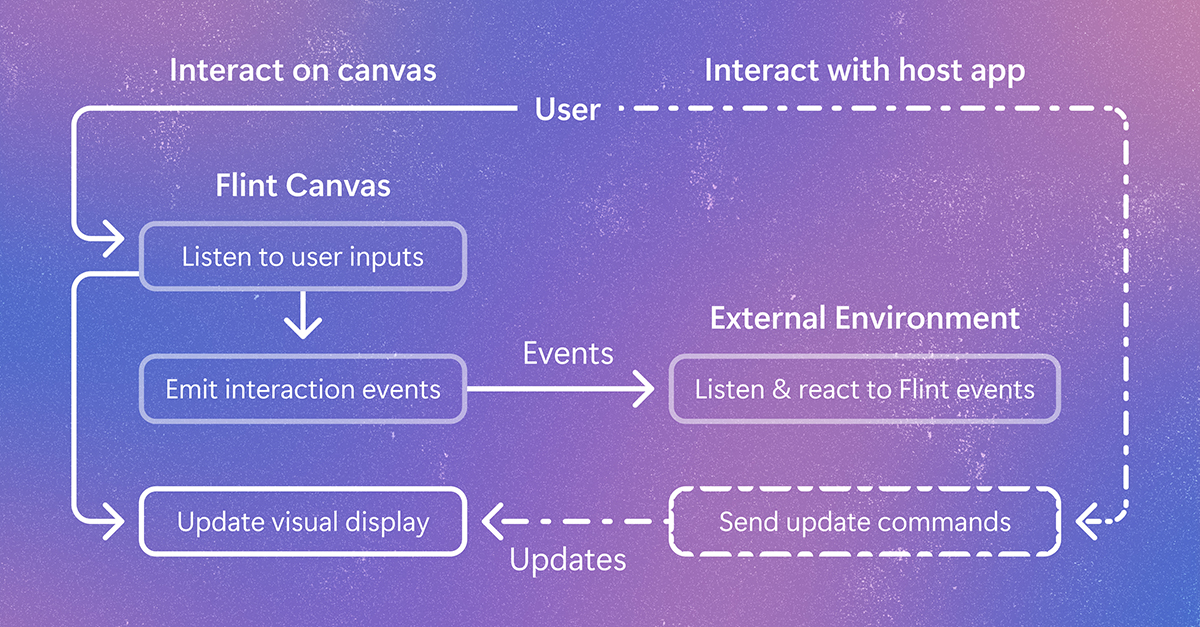
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.