Skip to content

Sympathetic Framing: Evaluating AI Alignment across Sociodemographic Groups

Jul 2026 · arXiv.org · Vol abs/2607.27232 · 0 citations · 62 references
Computer Science

TL;DR

This research offers the most comprehensive evaluation of LLMs' prehension of news framing to date, and finds that the correlation between AI and human evaluations varies across models, ranging from very high to medium, although there are statistically significant differences between groups.

Abstract

Large Language Models (LLMs) are increasingly shaping how we consume information and form our worldview. This raises concerns beyond bias in AI: do LLMs grasp the emotional nuances conveyed via textual framing? In this work, we empirically evaluate how well an array of LLMs aligns with human emotional perception. Considering news headlines covering political and geopolitical conflicts, both human participants (n = 3011, a representative sample of the U.K. adult population, via a YouGov survey) and seven LLMs answered whether headlines evoked sympathy for a specified side in a conflict. We find that the correlation between AI and human evaluations varies across models, ranging from very high (0.789, GPT-5.2) to medium (0.4 ,Mistral Large 2512). Crucially, the leading models are broadly aligned with human judgments across all demographic subgroups, including age, gender, level of education, prior geopolitical knowledge, and participants'predispositions regarding the conflict, although there are statistically significant differences between groups. This research, with its robust design and large, demographically diverse dataset, offers the most comprehensive evaluation of LLMs'comprehension of news framing to date. Findings highlight an important, often-ignored aspect of differential alignment: even when aggregate performance is high, AI alignment is not universal -- it may correspond differently with demographic features and cultural norms. Considering or ignoring the need for differential alignment may therefore have significant implications for the development of ethical and useful AI systems.
View source

Similar papers

#natural language process... Preprint Sep 2026

Framing the Narrative: Ideological Mimicry in Large Language Models

Large language models (LLMs) are increasingly used to answer questions about politically contentious issues, yet evaluations typically treat a model's stance as a relatively stable property. Real users, however, communicate political signals through their terminology, assumptions, and personal context. We investigate w...

Olivia Macmillan-Scott, Michael Jacobs, Nils W. Metternich et al. · 0 citations
Preprint Aug 2026

It's How You Ask: Gender-Associated Linguistic Bias in LLMs

Professional communication is increasingly mediated by LLMs - but do these models serve all users equally? We show that when prompts contain linguistic features more commonly used by women (hedges, tag questions, collective reference), they systematically elicit shorter, less sophisticated, and less formal responses ac...

Katherine Van Koevering, A. Field · 0 citations
#artificial intelligence Preprint Aug 2026

How Identity and Opinion Shape Political Sycophancy in LLMs

A framework that disentangles two distinct triggers of political sycophancy: opinion (aligning with explicit narratives) and identity (stereotyping based on demographic labels) is introduced, highlighting how personalization may amplify identity- or opinion-conditioned shifts in the model's behaviors.

Li-Ni Fu, Chang-Chih Meng, Chien-Hua Chen et al. · 0 citations
2026

From Body to Mind: Analyzing Gender Representation in Spanish Generative Language Models

A rigorous, large-scale analysis of gender bias in a diverse set of 20 publicly available Spanish generative LLMs, finding systematic patterns consistent with pervasive cultural stereotypes, echoing findings from earlier masked language models are uncovered.

Ismael Garrido-Muñoz, Fernando Javier Martínez Santiago, Arturo Montejo-Ráez · 0 citations
#artificial intelligence Preprint Sep 2026

Gender bias across LLMs is common and highly heterogeneous

Bias auditing should be treated as an ongoing, multi-vendor process, rather than a one-time assessment, because gender-related biases are common in LLMs, but their direction and magnitude are highly heterogeneous, to the point that some models behave in diametrically opposite ways to others.

E. Bolzoni, Valerio Capraro · 0 citations

Related blog posts

Microsoft Research Blog Oct 22, 2026

Flint-interactive: A language for creating interactive data visualizations

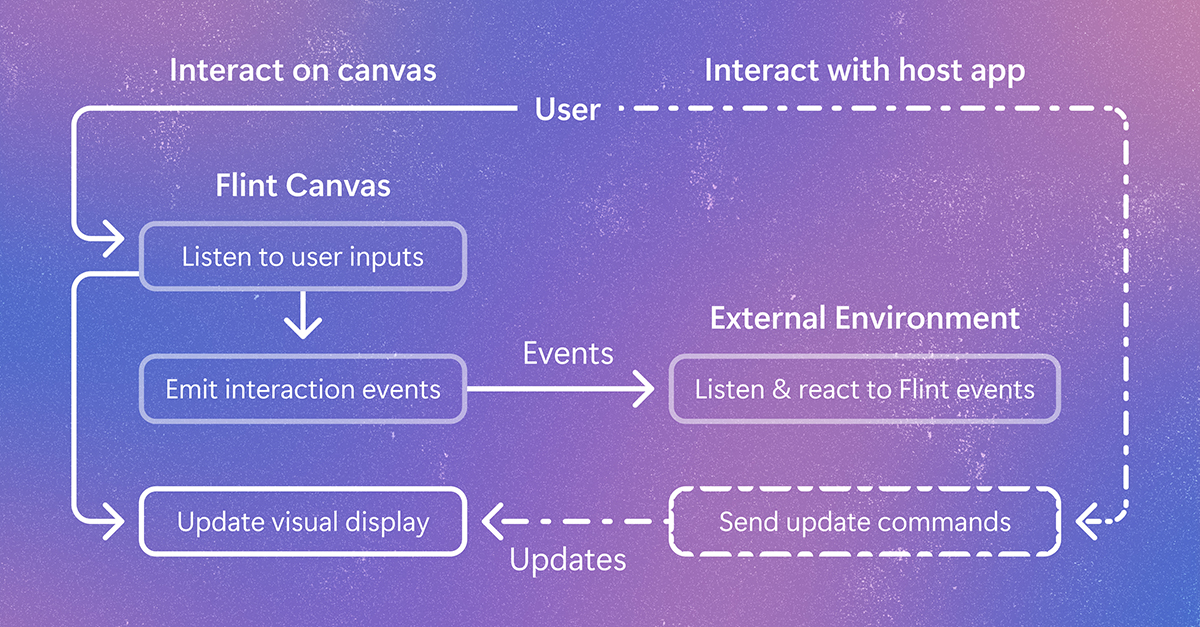
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.

MIT News · Artificial Intelligence Oct 15, 2026

AI model decodes the language cells use to communicate

A new computational approach reveals how cells communicate to assemble into tissues. This could accelerate stem cell engineering, improve disease models, and inform therapies.

Microsoft Research Blog Oct 15, 2026

Proof-based general-purpose computing with Magnetar

Zero-knowledge proofs can verify computing results without rerunning workloads or exposing sensitive data. Magnetar helps bring them into the mainstream with support for standard programming languages, major speed gains, and quantum-resistant security. The post Proof-based general-purpose computing with Magnetar appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.

