Skip to content

Enhancing Clinical Decision Support and Differential Diagnosis with Knowledge Graphs, and Retrieval Augmented Generation in Generative AI

Aug 2026 · 0 citations · 49 references
Biology

TL;DR

A decision-support pipeline combining disease-specific biomarker correlation graphs, ordinary differential equations (ODEs), deep sequence classification, and retrieval-augmented generation (RAG) is developed, with a decoupling between grounding and diagnostic correctness.

Abstract

Diagnostic error carries a burden, while unconstrained large language models (LLMs) remain vulnerable to hallucination and weak integration of quantitative laboratory dynamics. We developed a decision-support pipeline combining disease-specific biomarker correlation graphs, ordinary differential equations (ODEs), deep sequence classification, and retrieval-augmented generation (RAG). For 103 disease classes from a full blood count (FBC) repository, biomarker networks were used as coupling matrices to generate 30 trajectories per disease (3,090 total). A one-dimensional convolutional neural network (CNN) and long short-term memory (LSTM) network classified disease trajectories and six dynamical clusters. A constrained GPT-4o-mini RAG layer used a 19-pattern BMJ Best Practice/NICE corpus to generate differential diagnoses evaluated for diagnostic suitability, evidential grounding, and clinical plausibility. Across five random-seed runs, disease-level accuracy was $0.940 \pm 0.006$ for the CNN (95\% CI 0.933--0.948) and $0.852 \pm 0.019$ for the LSTM (95\% CI 0.828--0.875); the CNN advantage was 8.87 percentage points (95\% CI 6.47--11.27; $t(4)=10.26$, $p=5.1\times10^{-4}$; Hedges'$g=3.67$). Among 100 sampled RAG cases, 96 parsed successfully; evidence was cited in 97.9\%, the true diagnosis was mentioned in 71.9\%, and the composite score was 3.82/5 with a 47.9\% strict pass rate. The central finding was a decoupling between grounding and diagnostic correctness: classifier-correct versus classifier-wrong outputs differed in diagnostic suitability but not evidential grounding. Post-hoc analysis confirmed a 1.02-point diagnostic-score difference (Mann--Whitney $p=0.0024$; Hedges'$g=0.72$), whereas grounding differed by only $-0.02$ points ($p=0.839$; $g=-0.04$).
View source

Similar papers

Review Open access Aug 2026

Deep learning and generative AI for medical imaging and clinical decision support systems: a structured critical review

It is argued that LLM-based CDSS are not supported for routine autonomous use and require clinician supervision, and set out a research agenda centred on validation, governance and human-in-the-loop deployment.

A. Babu, A. J. Nehemiah, V. Jagadeep et al. · 0 citations
Conference Aug 2026

LLM-Augmented Hybrid Representations for Disease Category Classification from Clinical Notes

Clinical notes contain rich diagnostic evidence, but their long, noisy, and heterogeneous form makes automatic disease category classification difficult. We study a DiReCT-derived closed-set disease category classification task and propose an LLM-Augmented Hybrid Representation for lightweight clinical note classificat...

Khanh-Thao Le-Vu, Hung-Nghiep Tran · 0 citations
Open access Aug 2026

DeMoP: A Language-Model-Guided Mixture-of-Experts Framework for Cancer Prognosis

DeMoP, a language-model-guided mixture-of-experts framework that serializes structured patient profiles as natural-language sequences and learns adaptive prognostic representations from clinical variables, copy-number alterations, and gene descriptions, provides a unified approach to heterogeneous biomedical data integ...

Chen Tang, Lei Yu, Qiwei Li et al. · 0 citations
Preprint Aug 2026

MedReaMM: Evaluating Large Multimodal Models on Expert-Level Clinical Diagnostic Synthesis

This work introduces MedReaMM, a benchmark specifically designed to evaluate models'ability to synthesize heterogeneous clinical evidence consisting of detailed patient histories alongside multiple medical images into accurate differential diagnoses under a complete-information paradigm.

Lai Wei, Yu-Chao Chen, Zhenbiao Cao et al. · 0 citations
#natural language process... Preprint Aug 2026

Surgical Alignment in Knowledge Graph Training for Clinical Diagnosis with Large Language Models

A systematic study spanning five KG task formulations, three training paradigms, two KGs, and three base LLMs finds that at the task level, all paradigms improve over the non-finetuned baseline, but methods with comparable in-domain accuracy show substantially different knowledge transfer behavior.

Saksham Khatwani, He Cheng, M. Afshar et al. · 0 citations

Related blog posts

Microsoft Research Blog Jul 13, 2026

Verifying Rust cryptography in SymCrypt, from standards to code

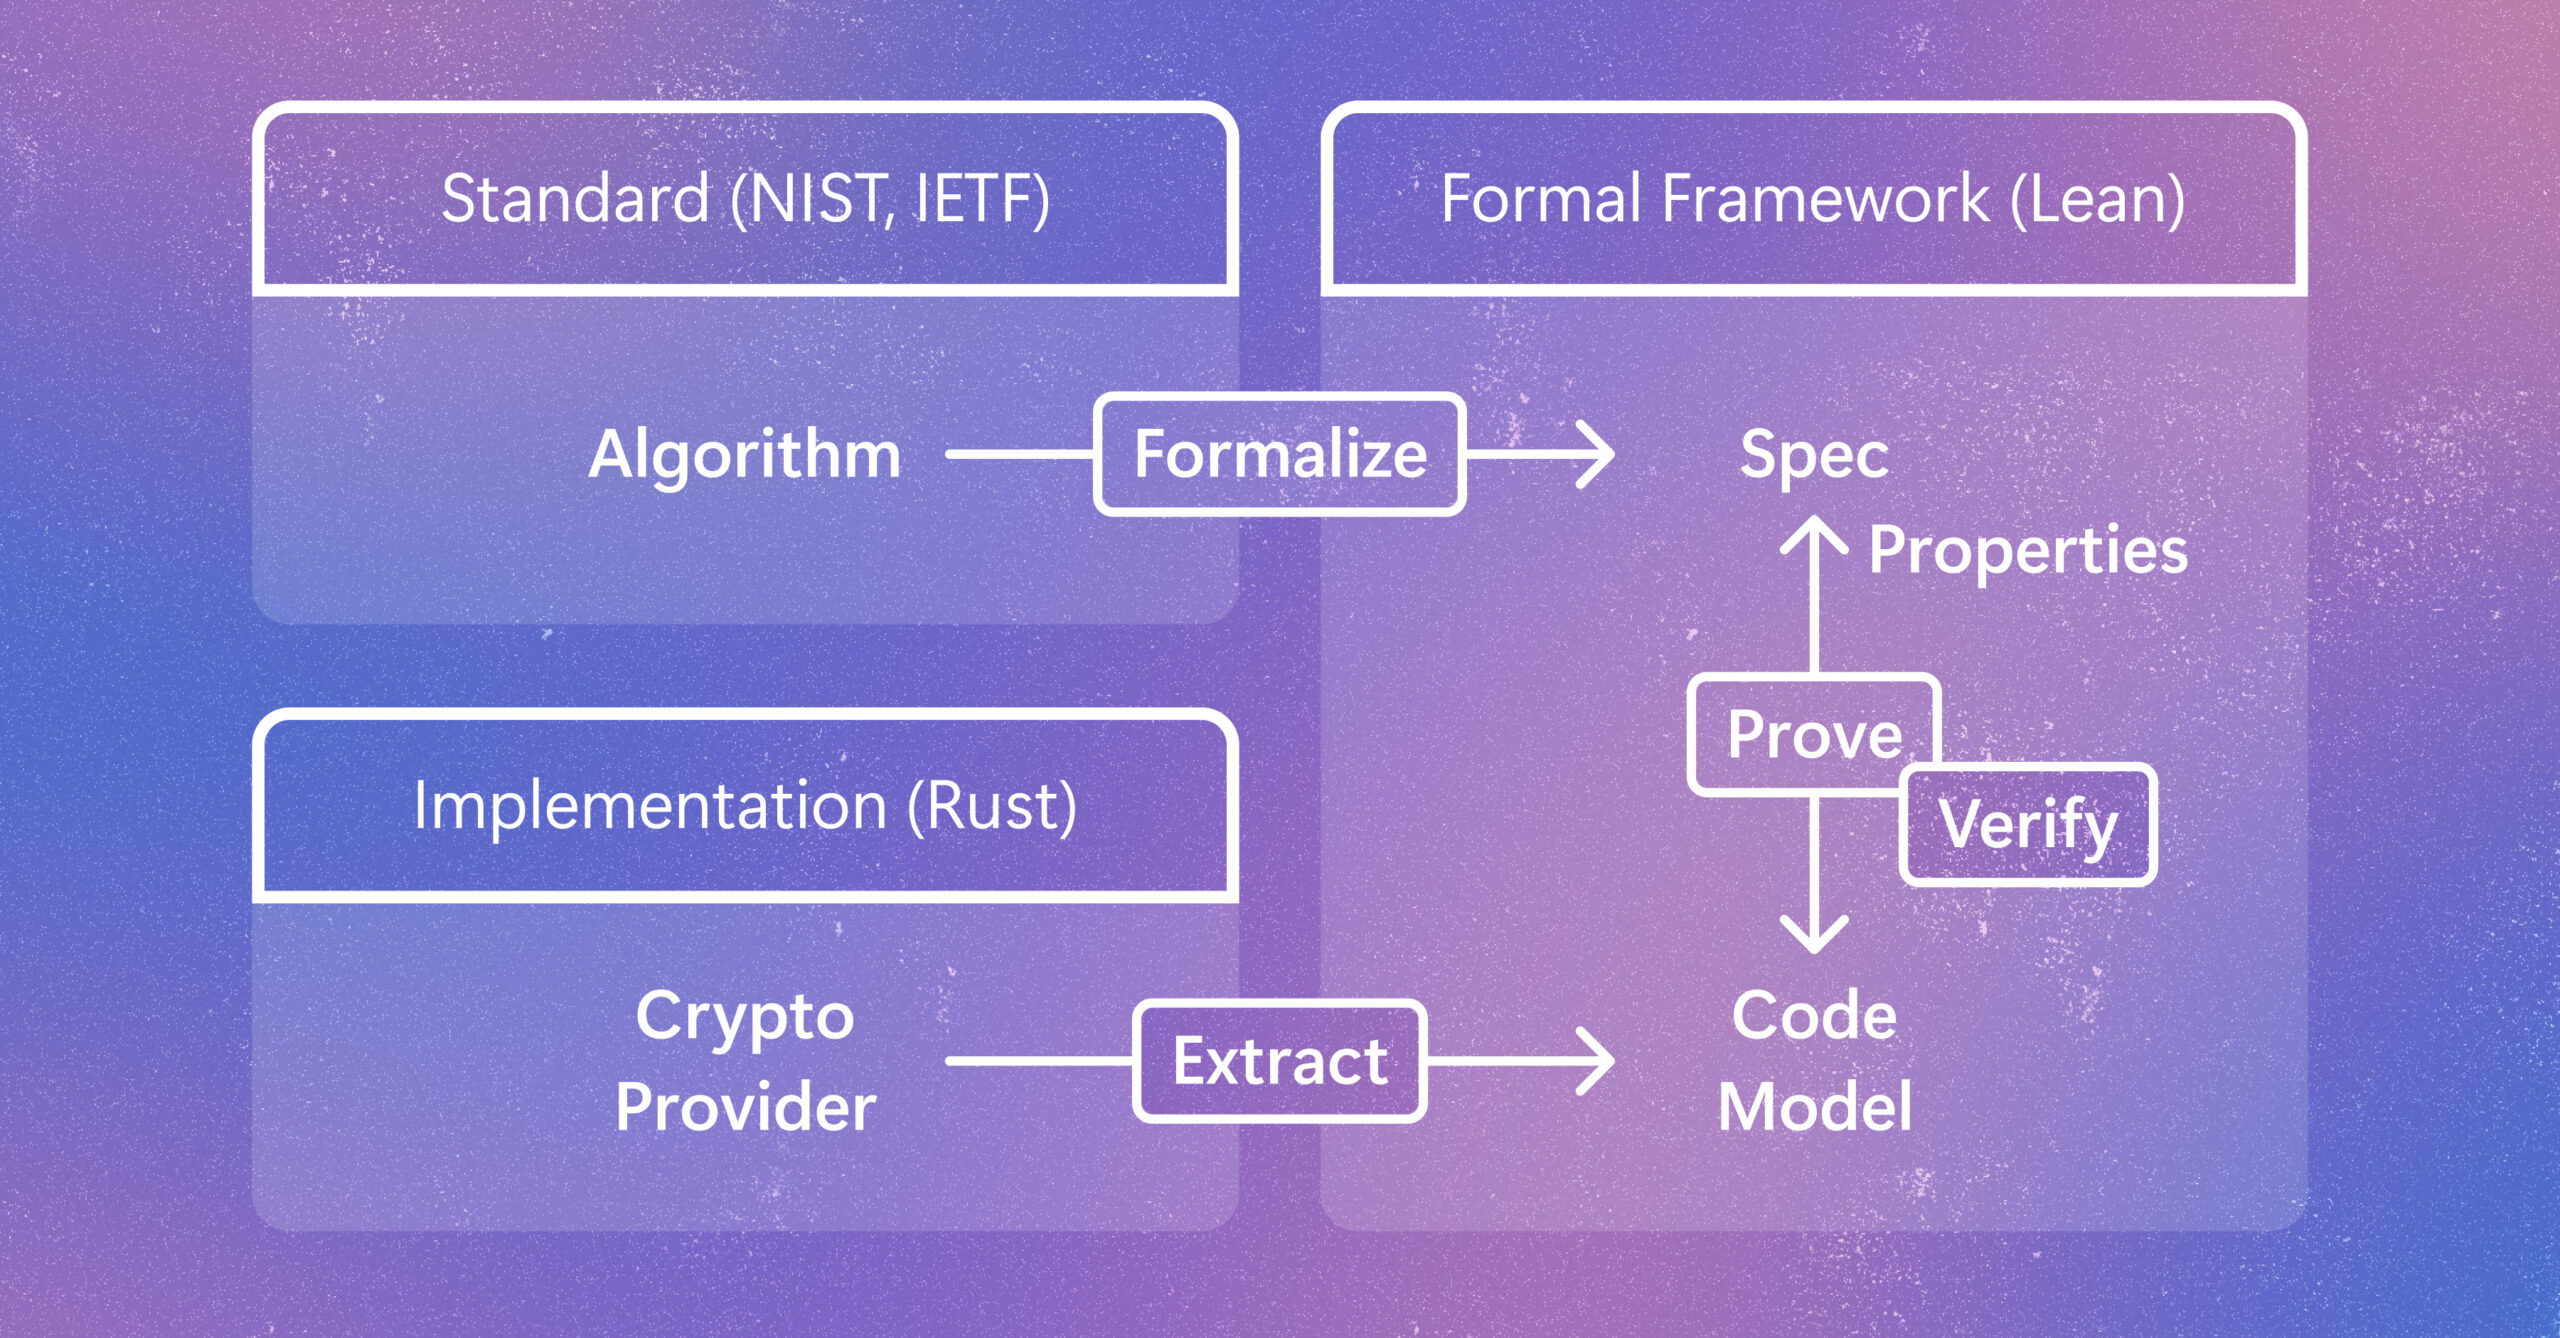
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.