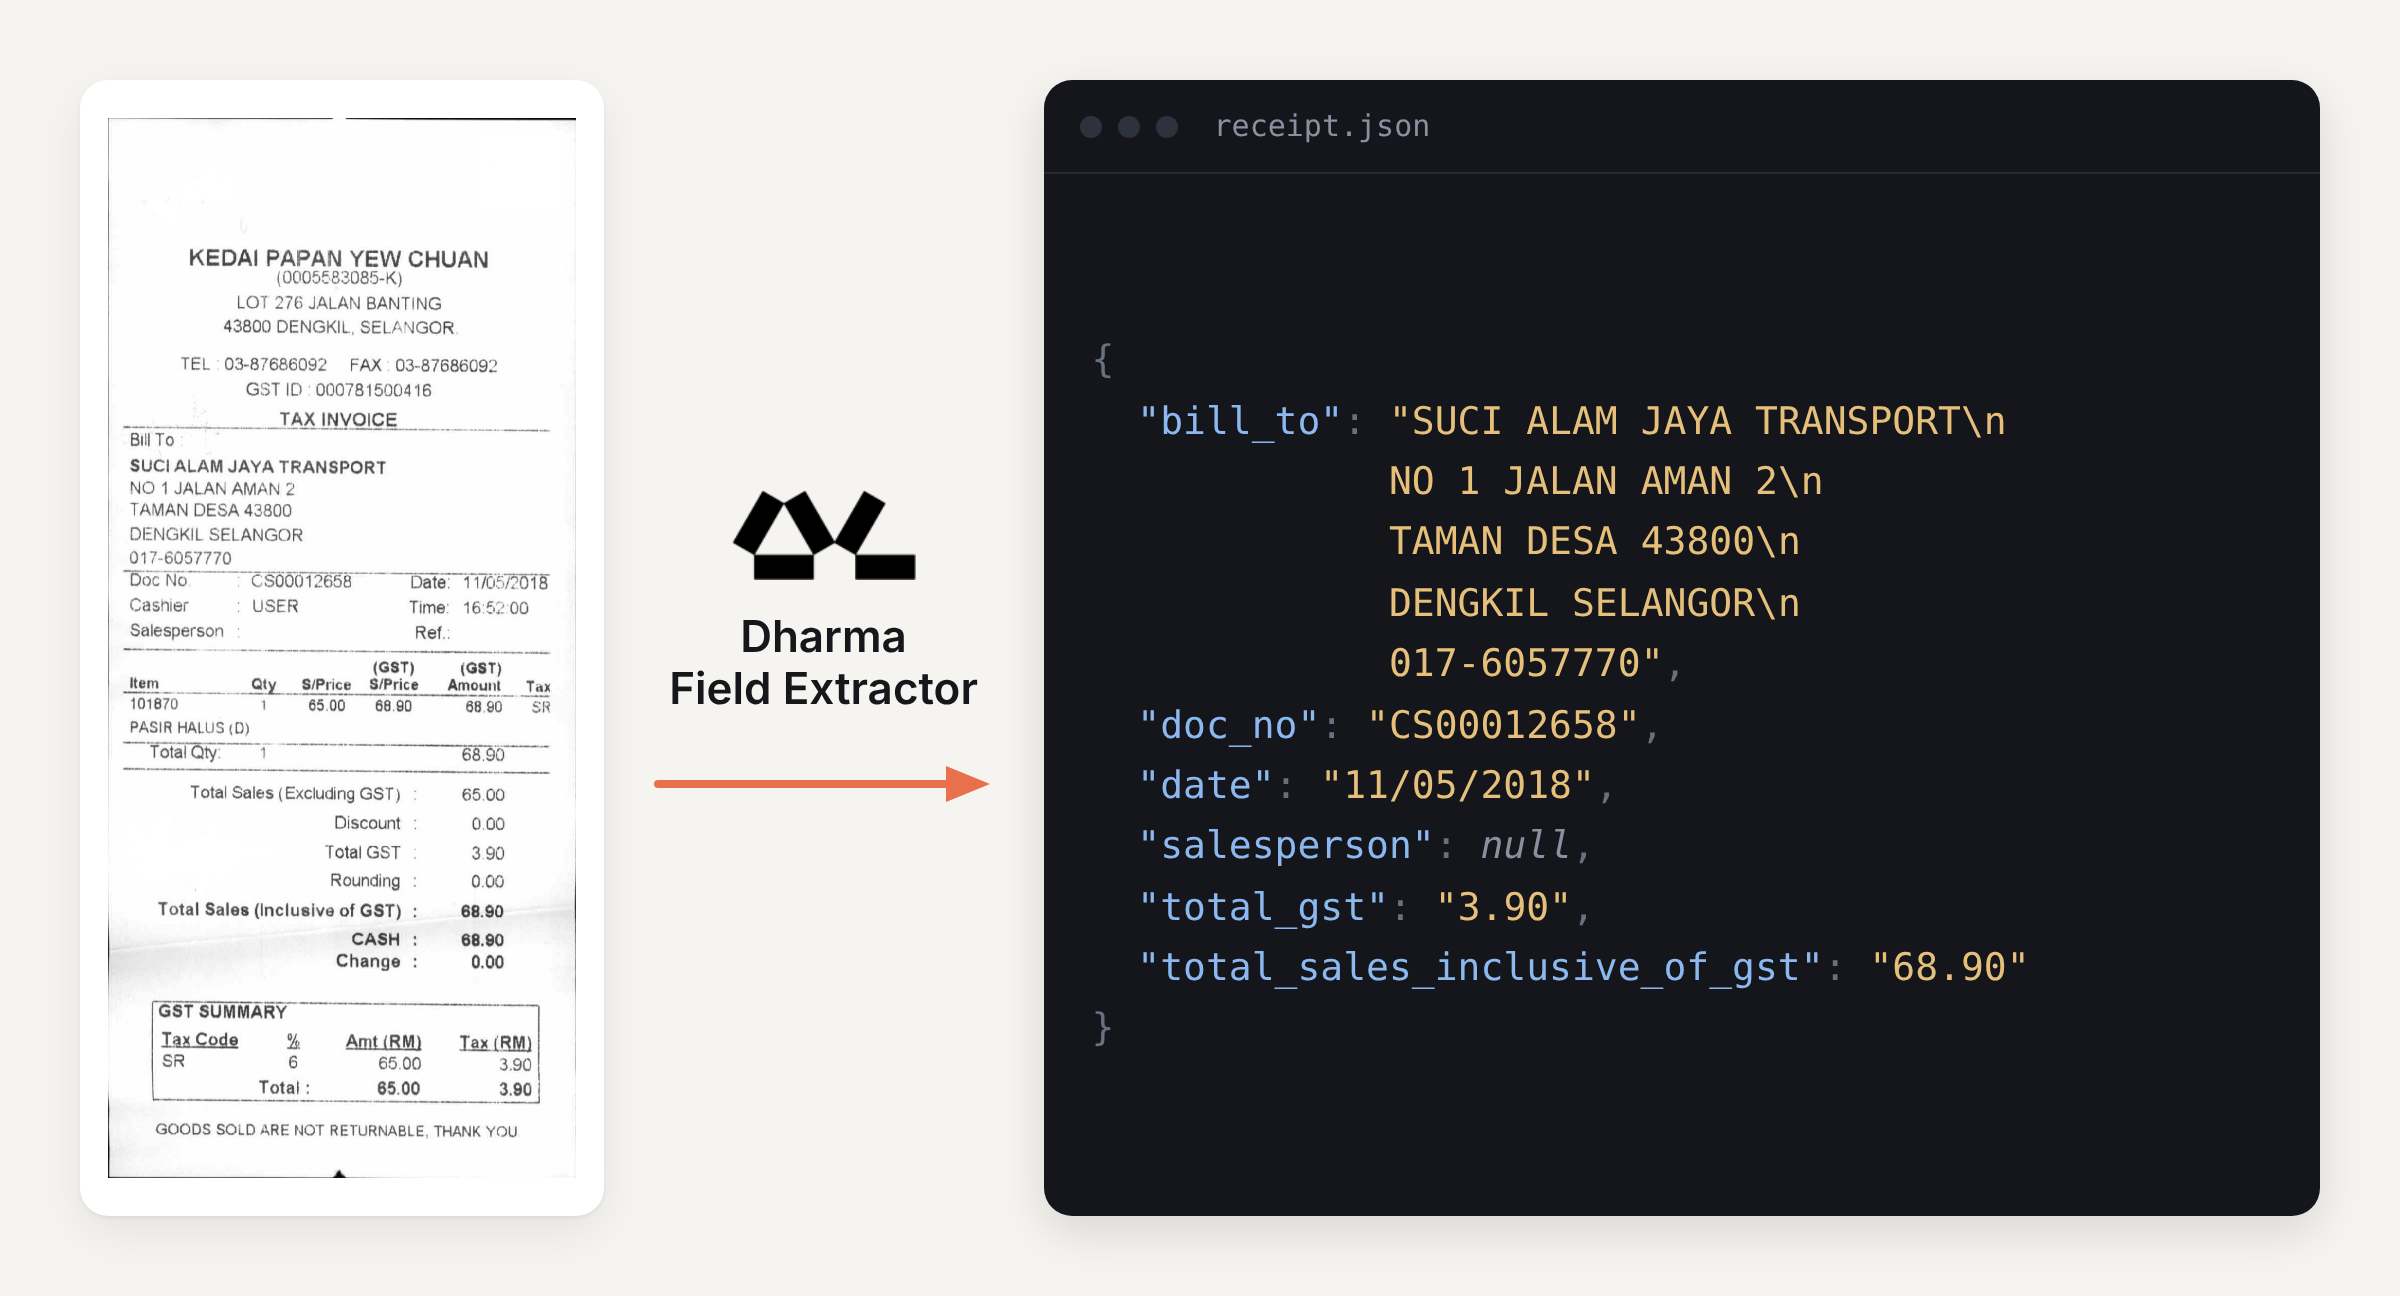
Evaluating the quality of explanations produced by explainable AI (XAI) methods remains challenging because existing approaches often rely on subjective human judgment, limiting reproducibility, scalability, and comparability between studies. We examine whether LLMs can serve as a reproducible and scalable mechanism to...
Yanfei Hu Fleischhauer, Alona Zharova, Nadja Klein et al.· 0 citations
This survey traces attention from Bahdanau-Luong alignment through the Transformer and into vision architectures, and reviews fixed and learned sparse attention, linear attention, IO-aware exact algorithms including FlashAttention, and state-space alternatives including Mamba.
It is argued for shifting the field's focus from methods to models, along two complementary lines: existing tools let us characterize and compare what different models represent and compute, and whether a model can actually be understood by the humans who rely on it.
Julien Colin, Nuria Oliver, Thomas Serre· 0 citations
AgentIdeaBench is introduced, a multidisciplinary benchmark that evaluates scientific ideation under two matched settings, static observation and active exploration, and Scientific World Modeling is explored, a generation-time loop that refines a draft hypothesis through structured thought experiments.
Yunxiang Mo, Tianshi ZHENG, Yi-Sen Gao et al.· 1 citation
Top researchers have good intuition, but do language models have as good intuition about model training as top AI researchers? To measure model intuition of LLMs and humans, we introduce the ArchitectureIQ benchmark. Each question presents a synthetic dataset and several training recipes, and the test-taker is asked to...
Zi-Rui Ren, Shao-Yang Guo, Chen-Cheng Tang et al.· 0 citations
Current evaluation of metaphor explanations relies mainly on holistic quality ratings, revealing little about how explanation quality is structured or where human judgments agree and diverge. We introduce a cognitively motivated framework that decomposes metaphor explanation quality into six theoretically grounded dime...
Ana Naveriani, Jakob Suchan, S. Zoia et al.· 0 citations
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Is your company’s AI sovereign? A practical guide for CIOs on AI vendor lock-in, EU Data Act switching, cloud sovereignty, and testing your exit plan before you need it. The post Sovereignty Is the Option to Leave appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduNov 2, 2026
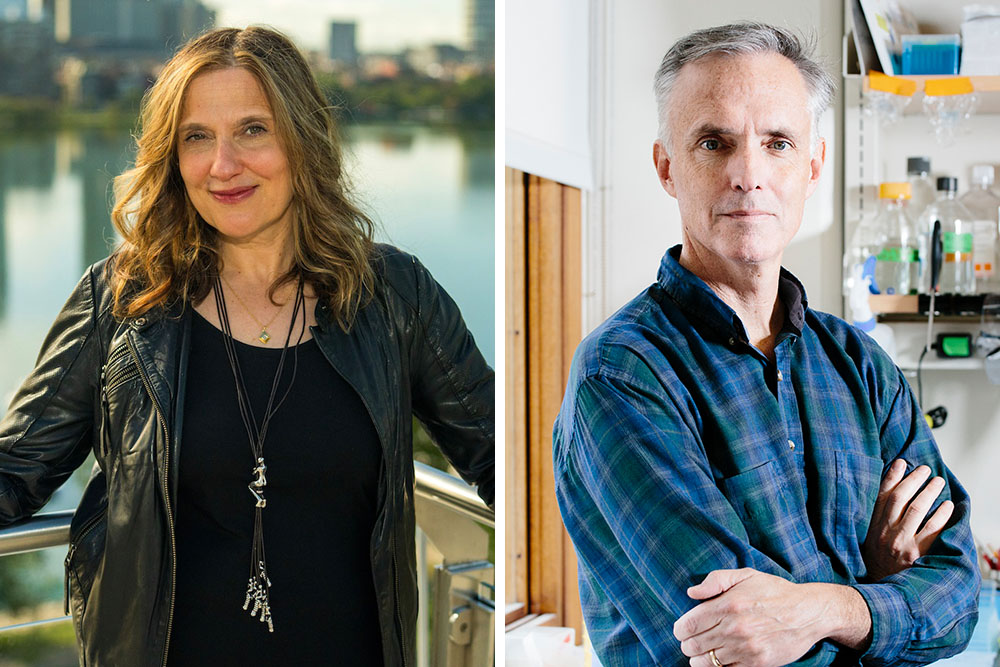
The MIT professors collaborated to identify the first AI-discovered antibiotic, a scientific breakthrough that is widely recognized as a milestone in AI-driven drug discovery.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.