Skip to content

Mutation Testing for Reproducibility Safeguards in Machine Learning Research Software: An Empirical Study

Aug 2026 · 0 citations · 25 references
Computer Science

TL;DR

It is shown that, in this sample, existing validation workflows often did not detect the particular controlled reproducibility-relevant changes introduced by the study, motivating reproducibility-oriented mutation testing as a complementary way to assess whether research-software safeguards constrain experimentally important choices.
Abstract

Reproducibility in machine-learning research depends on experimental choices such as random seeds, dependency versions, data partitioning, and evaluation configuration. Existing repository validation workflows may execute successfully without detecting changes to such choices. We study this problem using MLReproMutate, research software that applies controlled, reproducibility-relevant mutations to ML research repositories and evaluates them against validation workflows already present in those repositories. We conducted an outcome-blind empirical study of 39 frozen repository-operator cases using four mutation classes: random seed, dependency pin, data split, and cross-validation fold count. Repository revisions, mutation candidates, and validation workflows were fixed before mutation outcomes were observed. Primary execution yielded outcomes for 13 of 39 cases; a bounded restoration procedure increased the combined evaluable set to 24. After excluding one confirmed-equivalent mutation, 23 confirmed non-equivalent mutations remained. The selected validation workflows detected 2 of these 23 mutations, corresponding to an observed detection proportion of 8.7%. These results do not imply that the corresponding repositories are irreproducible. Rather, they show that, in this sample, existing validation workflows often did not detect the particular controlled reproducibility-relevant changes introduced by the study. The findings motivate reproducibility-oriented mutation testing as a complementary way to assess whether research-software safeguards constrain experimentally important choices.
View source

Similar papers

Review Aug 2026

Automated software debugging and bug prediction through the use of machine learning and deep learning

The results indicate that traditional ML models, especially random forest and extra trees, are still very effective for metric-based defect prediction, while DL and multi-modal approaches need to be fed with richer software artifacts to reach their full potential.

Amro Mohammad Abed Alfattah Abdin, Mohanad Alayedi, Ahmad M. Jaradat · 0 citations
Open access Jul 2026

Benchmarking large language models for ACMG/AMP variant interpretation and variant calling

ClawBench shows that apparently identical outcomes arise from distinct, independently measurable failure modes, and that trustworthiness in agentic genomics is a property of the pipeline architecture rather than of the model, providing a portable, contamination-resistant unit of attribution for the field.

M. Corpas · 0 citations
Preprint Jul 2026

On the risk of coding before testing: An empirical study on LLM-based test generation workflow

This paper introduces and empirically study the phenomenon of error propagation, where faults in generated code are systematically replicated in associated test artifacts, and examines whether LLM-generated code biases the generation of subsequent tests.

Michael Konstantinou, Florian Tambon, Mike Papadakis · 1 citation
Review Open access Aug 2026

A machine learning framework for predictive interpretation of variants of uncertain significance in hereditary cancer

This reproducible pipeline provides a clinically grounded computational approach to VUS triaging in precision oncology, with external validation supporting its generalizability to independent hereditary cancer gene datasets.

Nayeema Nizamuddin, Soham Biswas, Akshaykumar Zawar et al. · 0 citations

Predictive Test Optimization Without Historical Failure Data

The novel method of co-evolution labeling for predictive test optimization is introduced, deriving test relevance from tests and code changing together in the version history, which nearly matches the failure detection capabilities of failure-based models, while being more resistant to label noise and requiring no test...

Maximilian Jungwirth, RaphaelN ̈ommer, Andreas Stahlbauer et al. · 0 citations
Open access 2023

COMPARATIVE EVALUATION OF CLASS-IMBALANCE CORRECTION TECHNIQUES FOR SOFTWARE DEFECT PREDICTION

This study compared no correction, random oversampling, random undersampling, SMOTE, ADASYN, and class-weighted learning across logistic regression, decision tree, random forest, support vector machine, and neural network classifiers to find accuracy alone is unsuitable for selecting defect predictors.

L. Akpan · 0 citations

Related blog posts

Microsoft Research Blog Oct 12, 2026

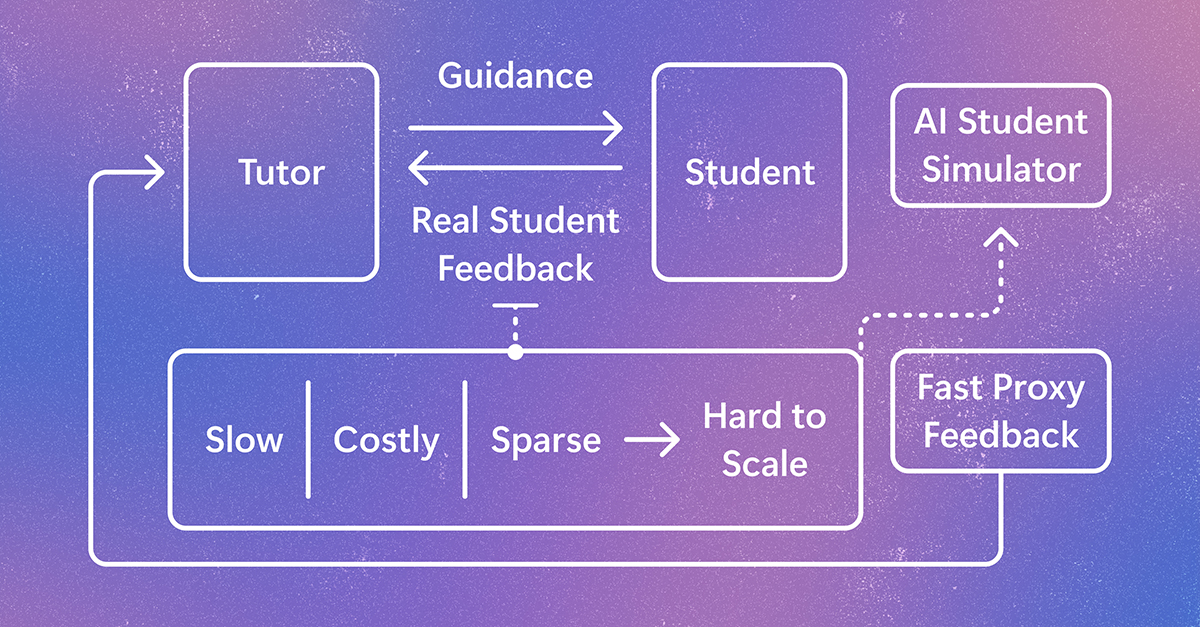
Simulating student learning for better AI tutoring

StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

MIT News · Artificial Intelligence Oct 2, 2026

Documenting the tech worker movement

Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.