This work introduces RePPO, which adapts PPO to jointly optimize a compact population of diverse, high-quality policies using a population-dependent, dynamically shaped reward, and shows that directly optimizing compact populations with RePPO provides a scalable approach to QD-RL across increasingly complex domains.
Saeed Hedayatian, Harsh Shah, Celine Mneimneh et al.· 0 citations
Anticipating short-term hypoglycemic and hyperglycemic risk is essential for proactive diabetes management. However, existing machine learning approaches often use inconsistent evaluation protocols and emphasize predictive performance over reliability. This study introduces an anchor-based benchmarking framework integr...
Pir Bakhsh Khokhar, Carmine Gravino, Fabio Palomba· 0 citations
DNA methylation (DNAM) array-based tumor classification is a powerful clinical diagnostic tool, but models trained on fixed reference cohorts can produce faulty predictions for tumor types not represented in the training distribution. We propose an end-to-end deep representation learning-based out-of-distribution (OOD)...
Md Zahangir Alom, Quynh T. Tran, Breuer Alexandar et al.· 0 citations
This work examines whether a targeted LLM training approach can transfer distinct RE skills to open models via inverse basic-block execution: given an x86-64 basic block and a desired output register state, the model predicts the input register values that produce it.
Ritika Poddar, Aidan Fennelly, Deirdre Murphy et al.· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Offline-to-online reinforcement learning uses offline pretraining to accelerate subsequent online learning. While many methods assume the offline dataset remains available throughout fine-tuning, there are many settings where this is not the case. Prior work attributes failures in this setting primarily to critic recal...
Sami Nur Islam, Johan Obando-Ceron, Doina Precup et al.· 0 citations
Structure predictors like ESMFold fold proteins using neural network computation and have transformed structural biology. However, the driving mechanism from amino-acid (AA) sequence to 3D structure is insufficiently understood, and biological meaning remains locked in the dense network. Sparse autoencoders (SAEs) have...
Bo-Han Liu, Xiao-Han Fan, Wenqian Ye et al.· 0 citations
Across five benchmarks spanning sparse, dense, featureless, featureless, and attributed regimes, Concorde establishes state-of-the-art early retrieval precision, nearly doubling P@10% over leading baselines in sparse settings.
The Persona Selection Model (PSM) posits that post-training selects a persona the model learned during pre-training. Work on subliminal learning has shown that models can impart covert signals (like "love of owls") into semantically unrelated outputs like strings of numbers, and that students trained on these outputs i...
Grokking is a delayed transition from memorization to generalization in deep neural networks (NNs). We examine whether scaling and renormalization group (RG) theories can describe this dynamics, establishing a quantitative physical framework for neural generalization transitions. For modular addition on a two-layer NN,...
Min Chen, Jun-Qin Wang, Ze-Guan Wu et al.· 0 citations
Semiparametric Bayesian networks (SPBNs) are flexible probabilistic graphical models for representing joint distributions of continuous variables through lower-dimensional conditional probability distributions (CPDs). Existing SPBN models use kernel density estimators (KDEs) for non-parametric CPD modeling, but their o...
Victor Alejandre, Pedro Larra\~naga, Concha Bielza· 0 citations
Financial institutions operating under data-residency constraints are restricted to open-weight models small enough to locally host, which trail frontier systems on multi-step quantitative reasoning. On-policy distillation narrows such gaps by supervising a student on its own rollouts, but traditional OPD requires a st...
This work introduces Rollback, a policy improvement paradigm that turns world models from passive simulators into counterfactual engines, and builds a scalable training system that unifies distributed world-model search with asynchronous real-robot execution, forming a self-reinforcing cycle.
Jia-Yi Luo, Yang Zhang, Li-Liang Chen et al.· 0 citations
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
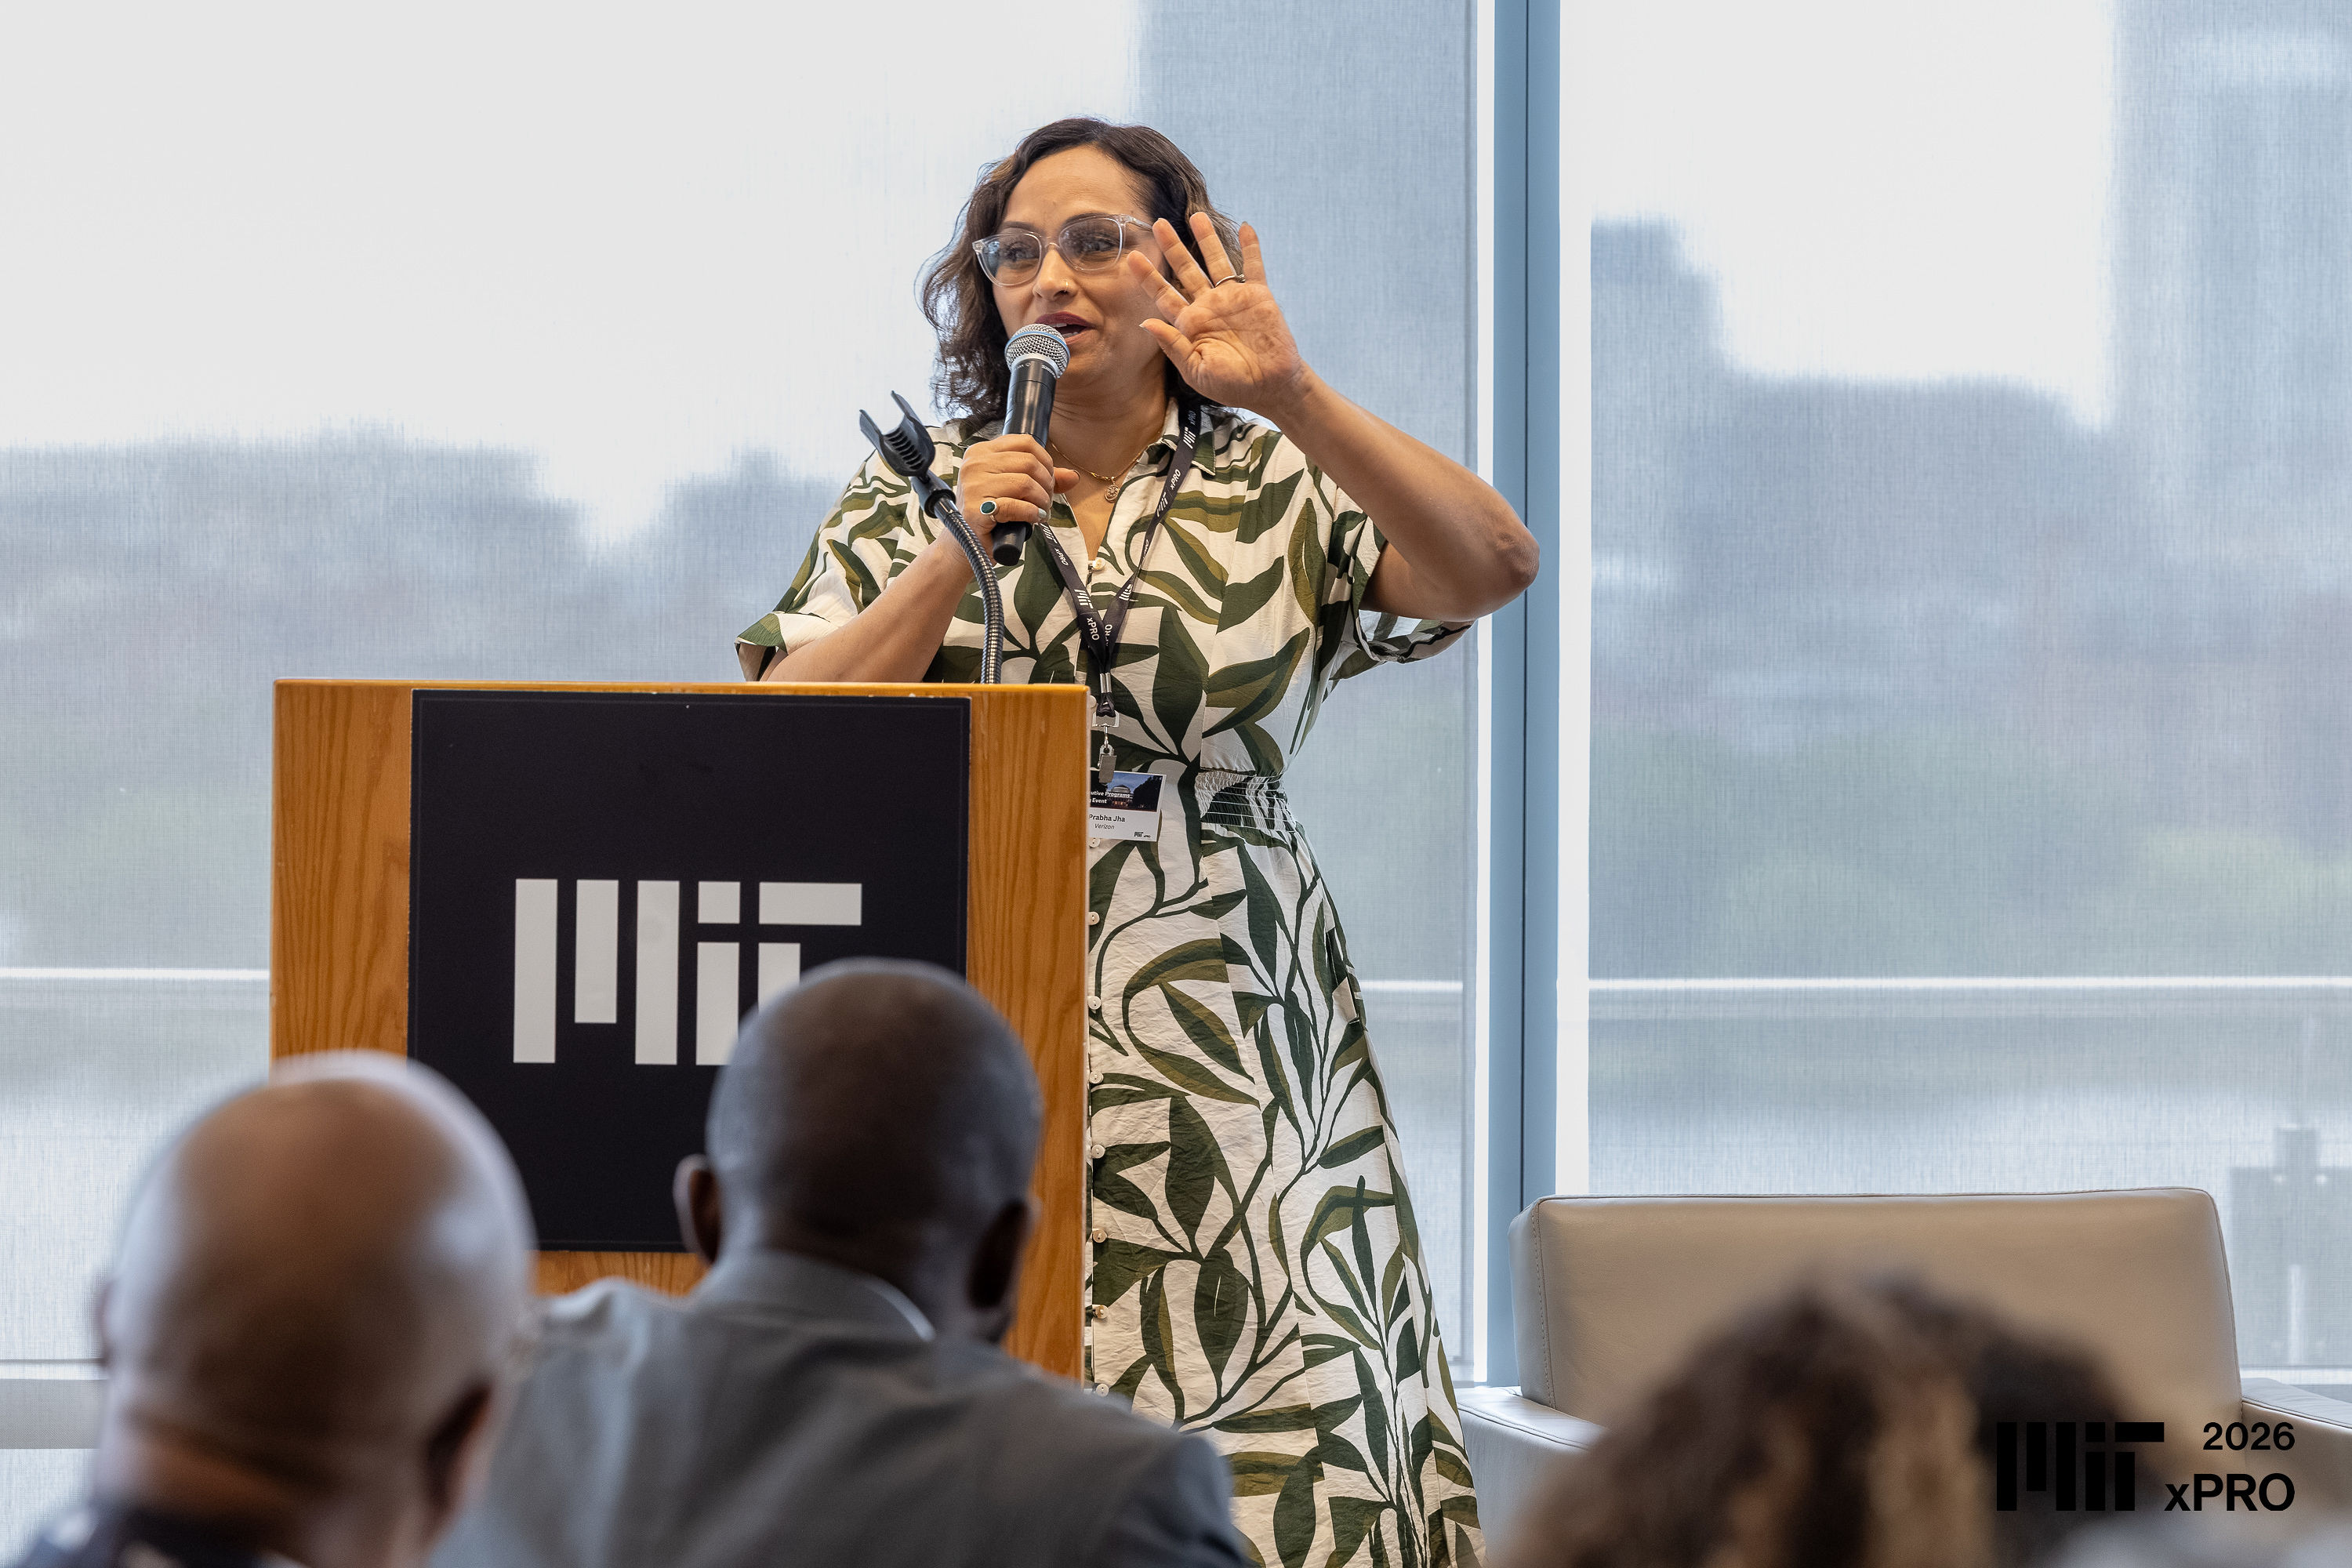
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.