Computationally expensive simulations and real-world observations often provide data at a lower temporal resolution than downstream tasks require. Averaging observations at fixed grid points can introduce errors, and motion estimates alone do not determine how the physical field values change. In this work, we study wh...
Pu Ren, Michael W. Mahoney, N. Benjamin Erichson· 0 citations
Contextual dueling bandits learn from pairwise comparisons, the same feedback used to fine-tune language models from human preferences. Standard algorithms explore aggressively and can show users two poor options. We study conservative contextual dueling bandits, which require that, at every round, the cumulative score...
Rohan Deb, Mohammad Ghavamzadeh, Arindam Banerjee· 0 citations
HeteGCD is proposed, a new statistics-aware dual-prototype learning perspective for generalized category discovery on heterophilous graphs that combines feature-based similarity with distribution-based consistency to support category discovery.
Xuan-Zhi Xi, Tong-Ze Zhang, Zhi-Li Qin et al.· 0 citations
Modern language models are trained on far more language than children experience, but we know much less about learning from small, naturalistic datasets. We train small GPT-2 models on transcripts of speech with children from dense home recordings (BabyView) and on synthetic child-directed dialogue (TinyDialogues), var...
Steven Y. Feng, Michael C. Frank· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Diffusion vision-language models (DVLMs) process their entire input at every denoising step. Since visual tokens make up 89-97% of this input on the benchmarks we study, most of the decoding computation is spent repeatedly processing the same image. Visual token pruning methods partially relieve this burden by removing...
Donghyeon Cho, Joowon Kim, Seungho Shin et al.· 0 citations
Dream-COP is introduced, in which a policy agent learns executable policies through dreaming in this experience world to guide a discovery agent in generating and refining COP programs, and policy replay provides feedback on the quality of the programs revealed and the search steps used, to guide policy selection more...
Kuan Xu, Jian-Ming Wang, Ni Zhang et al.· 0 citations
Mamba-2 compresses all context into a fixed-size recurrent state that dominates decoding memory and bandwidth. Existing compressors quantize state values or prune state coordinates, scoring each channel independently in the native basis. We examine trained Mamba-2 states and find that energy is almost rank-one, but the...
Automated polysomnography after ischemic stroke is challenging because of altered sleep-related neural activity and concurrent respiratory disturbances. Existing stroke-specific approaches mainly address sleep-stage classification, leaving joint analysis of sleep architecture and respiratory events underexplored. Moreo...
Md Wahiduzzaman Suva, Esm E Moula Chowdhury Abha, Md Imtiaj Alam Sajin et al.· 0 citations
The proposed AutoProfiler, a feedback-driven framework for learning a deterministic profiling tree from optimization feedback, suggests that hardware profiling should evolve from static metric collection toward profiling reasoning, making profiling itself a new dimension for improving kernel optimization.
Yi-Han Wang, Pei-Yu Liu, Run-Yu Chen et al.· 0 citations
The NextEval solver is introduced, an agent-based DFO solver which integrates the capabilities of a large language model (LLM) to guide the sequential selection of evaluation points, and a benchmark protocol for comparing agent configurations on shared DFO tasks using the same numerical tools under matched evaluation b...
Shuo-Tian Chen, Li-Geng Cui, Cun-Xi Huang et al.· 0 citations
This work introduces RoboAuto, a framework for robot program search that explicitly organizes physical understanding at the object, scene, and interaction levels through three components and shows that the knowledge base transfers across simulators and embodiments, and that program search performance scales with its si...
Bu-Zhao Liu, Jia-Ning Ye, Xiu Yuan et al.· 1 citation
On-policy distillation (OPD) improves language-model post-training by letting the student learn from its own sampled trajectories under teacher supervision, aligning the training process with inference-time behavior. However, the rollout policy in OPD is usually treated as fixed: each round samples directly from the cu...
Si-Rui Chen, Yun-Zhe Qi, Hao-Bo Xu et al.· 0 citations
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
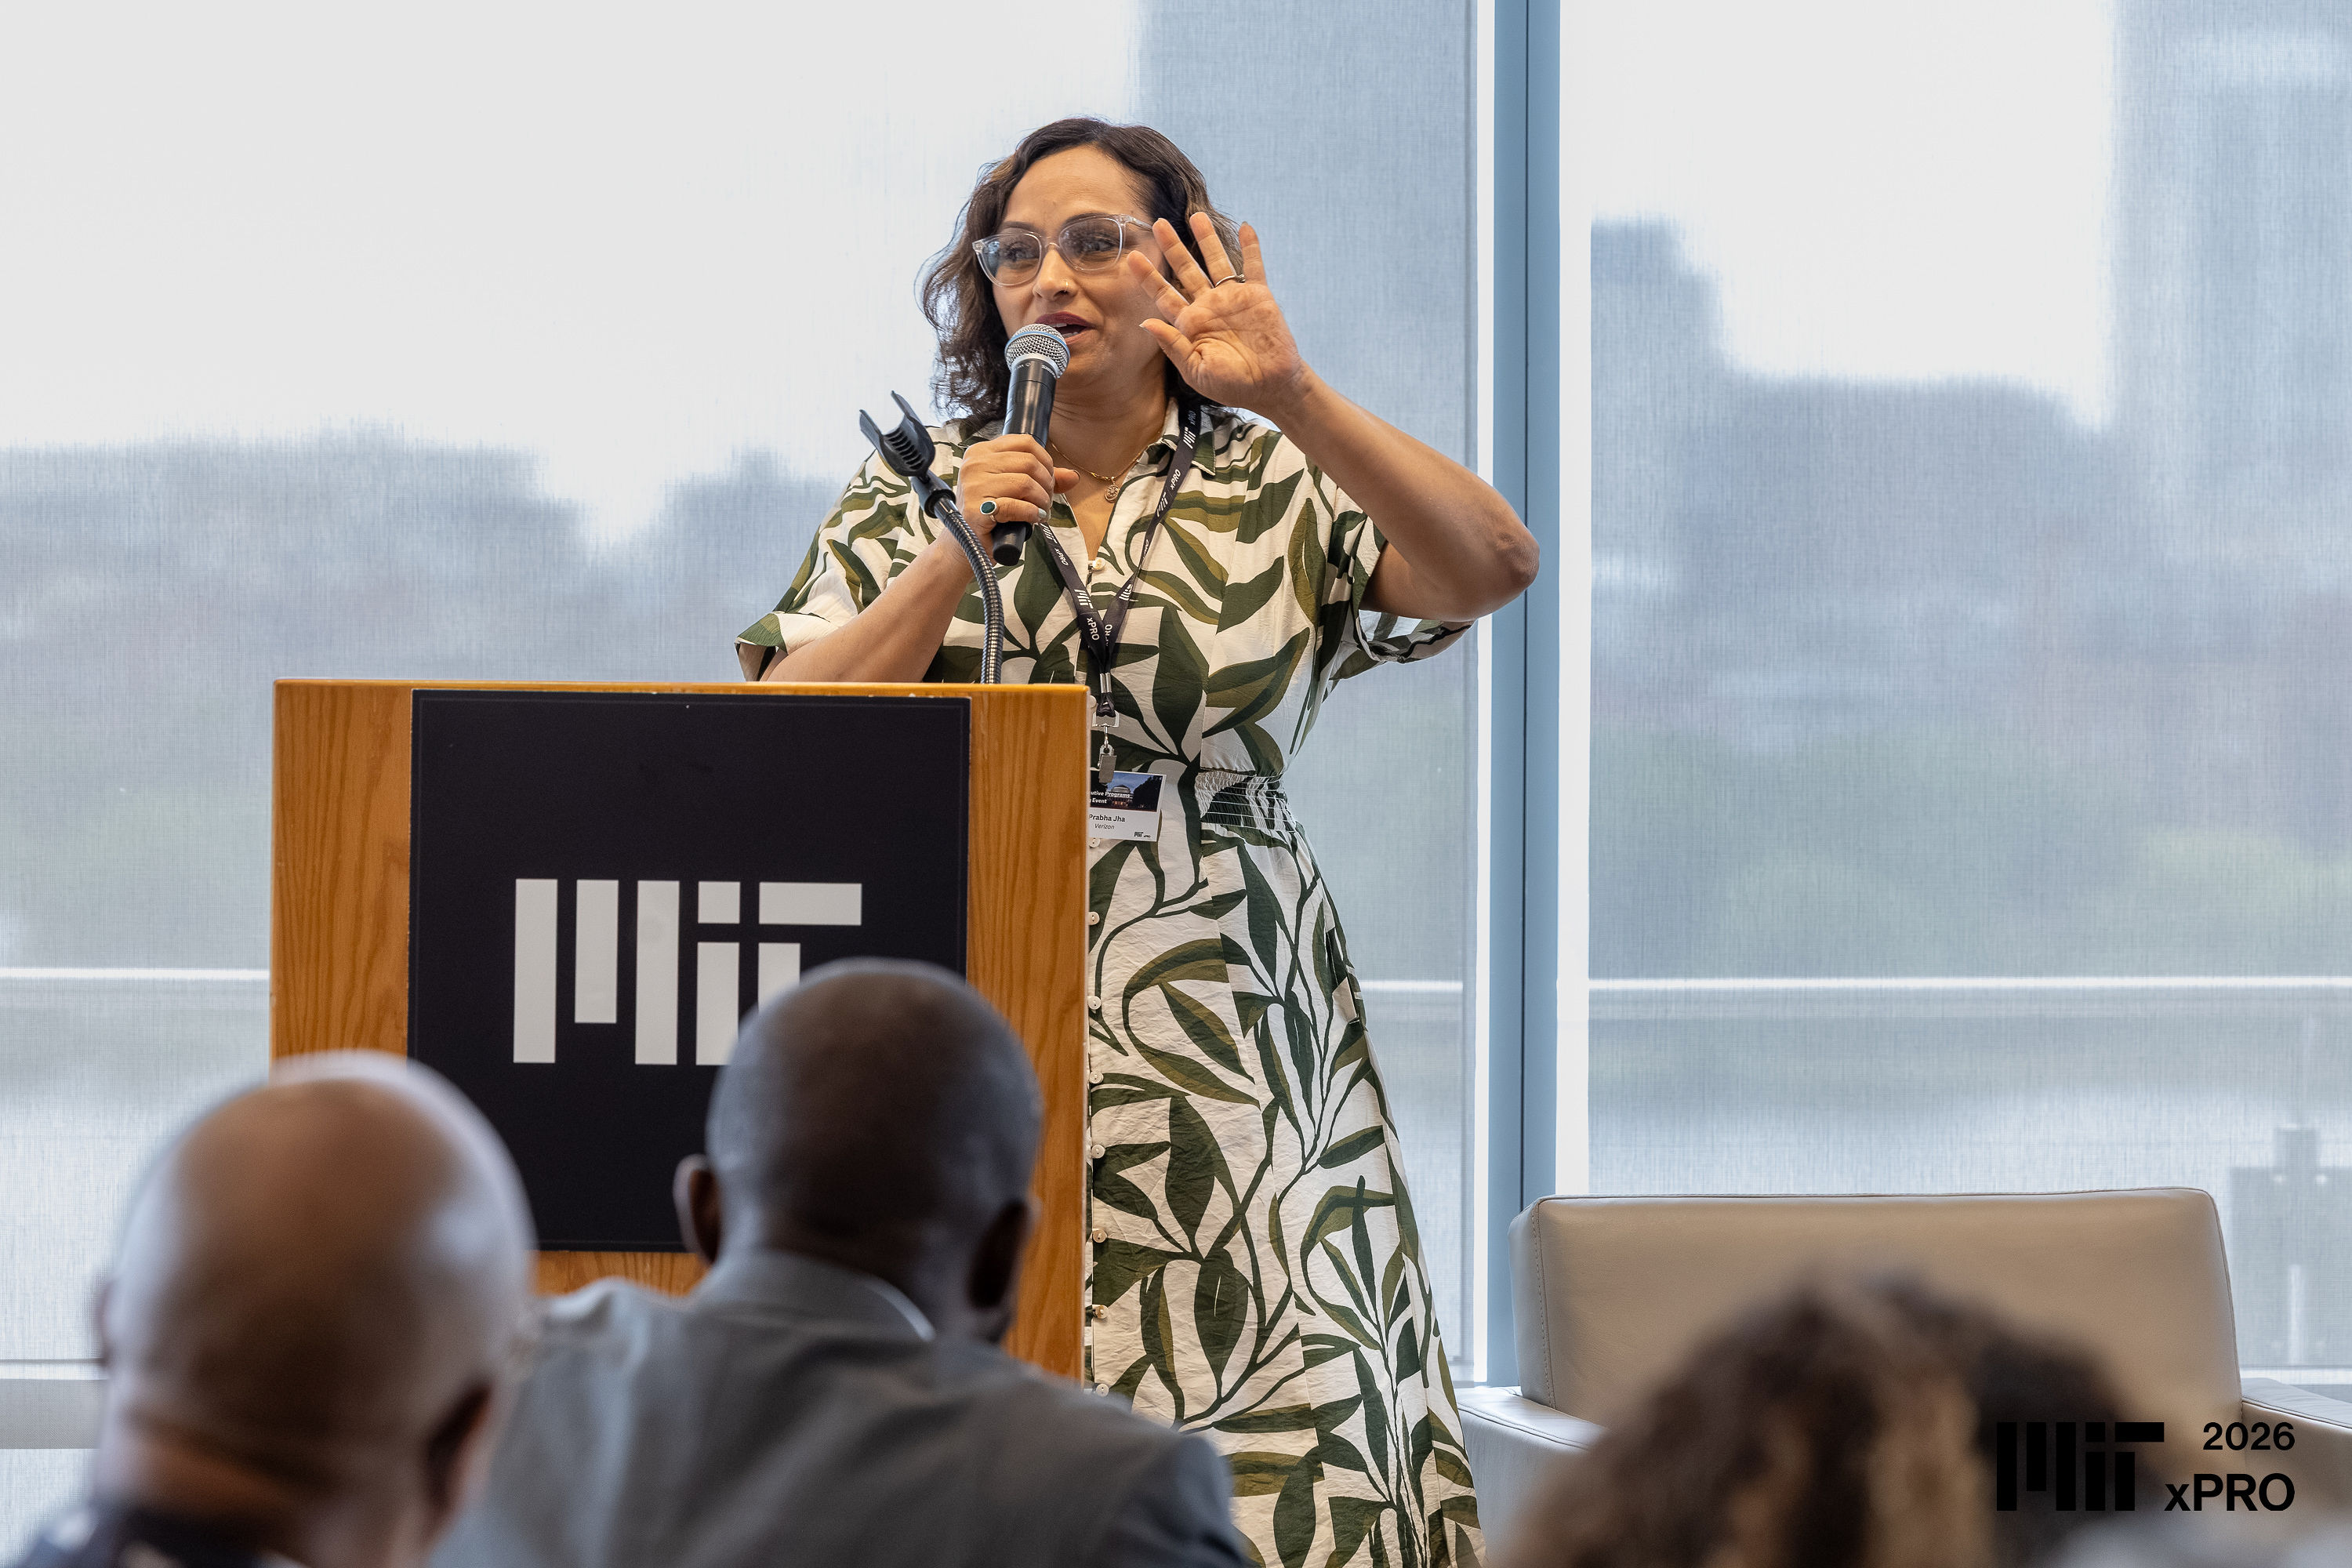
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.