Contextual decision making uses observed covariates to guide decisions under uncertainty. Two natural approaches are predict-then-optimize (PtO), which learns the conditional expected objective, and generate-then-optimize (GtO), which learns conditional uncertainty and optimizes using generated scenarios. We study when...
L. J. Hong, Wei-Huan Huang, Xin-Ya Li· 0 citations
Adapting pretrained Transformers to downstream tasks produces task-specific updates that are expensive to reproduce for every model variant. Reusing these updates across different depths and widths is challenging because their parameters have incompatible shapes and do not share a canonical coordinate system. We introd...
Filippo Rinaldi, Aniello Panariello, Giacomo Salici et al.· 0 citations
Masked latent prediction methods such as I-JEPA aim to learn predictable features, but what determines which information they retain is less clear. We built a simulator in which every factor behind an image is known, so a probe can measure how readable each factor remains after training. We trained small encoders (0.7M...
Learned representations often encode sensitive attributes, such as gender or race, that may be undesirable or unsafe to retain. Concept erasure aims to remove this information while preserving task-relevant content. Existing methods remain incomplete: linear methods provide guarantees only against linear probes, while...
Idan Simai, Shauli Ravfogel, Uri Shaham· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Thompson sampling is a widely used strategy for sequential decision-making under uncertainty, offering a principled way to balance exploration and exploitation. This strategy involves maximizing a target objective under a single sample drawn from the current belief over unknown quantities. Conventionally, this optimiza...
Spectroscopic instruments with limited wavenumber coverage require accurate scan positioning or multiple measurements to complete the material analysis. This often requires prerequisite knowledge about the material under diagnosis to measure the spectral regions with distinguishing peaks. In our study, we simulate a Ba...
Adithya Ashok Chalain Valapil, Aishwarya Venkataramanan, Joachim Denzler· 0 citations
Single-stage fine-tuning is pervasive, yet catastrophic forgetting persists when the source pre-training data is inaccessible. Data weighting affords a natural lever to modulate sample influence. Yet existing weighting methods lack a principled mechanism to explicitly arbitrate knowledge retention against new-task adap...
Large language models serve applications with diverse inference budgets, but training and maintaining separate models for each budget incurs substantial costs. Recent Looped Transformers enable flexible inference computation through parameter reuse, but maintaining strong performance across different inference budgets...
Yudong Zhang, Wei Ding, Kaili Zheng et al.· 0 citations
Crate-DTI, a construct-aware dataset derived from the 1 July 2026 BindingDB export, with IC50, Ki, Kd and EC50 processed independently, supports endpoint-specific classification and regression while allowing users to select molecular representations, protein representations and evaluation splits.
Lina Abou-Abbas, Nour Mhanna, Hasan Bazzi et al.· 0 citations
Experimental results demonstrate the applicability of the proposed edge-cloud methodology for integrating Continual Learning with Out-of-Distribution (OOD) Detection and Concept Drift Detection in IoT applications and its potential to support model adaptation while mitigating catastrophic forgetting.
Charalampos Davalas, Dimitrios Michail, Christos Diou et al.· 0 citations
Adversarial sharpness penalty per iteration of a base optimizer, known as sharpness-aware minimization (SAM), is an accepted technique to improve generalization in deep learning. Recently, Muon has emerged as a dominant optimization algorithm for training large language models (LLMs). It achieves lower sample complexit...
Geetika, Shivani Singh Chauhan, Gauranshi Gupta et al.· 0 citations
Graph structure learning (GSL) adapts propagation graphs to prediction tasks, but the relative predictive value of feature-derived priors and learned relations can vary across nodes. We propose DualGSL, a prior-guided framework for transductive node classification that learns node-specific weights for combining predict...
Yuxia Sun, Yutszyuk Wong, Huihong Chen et al.· 0 citations
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
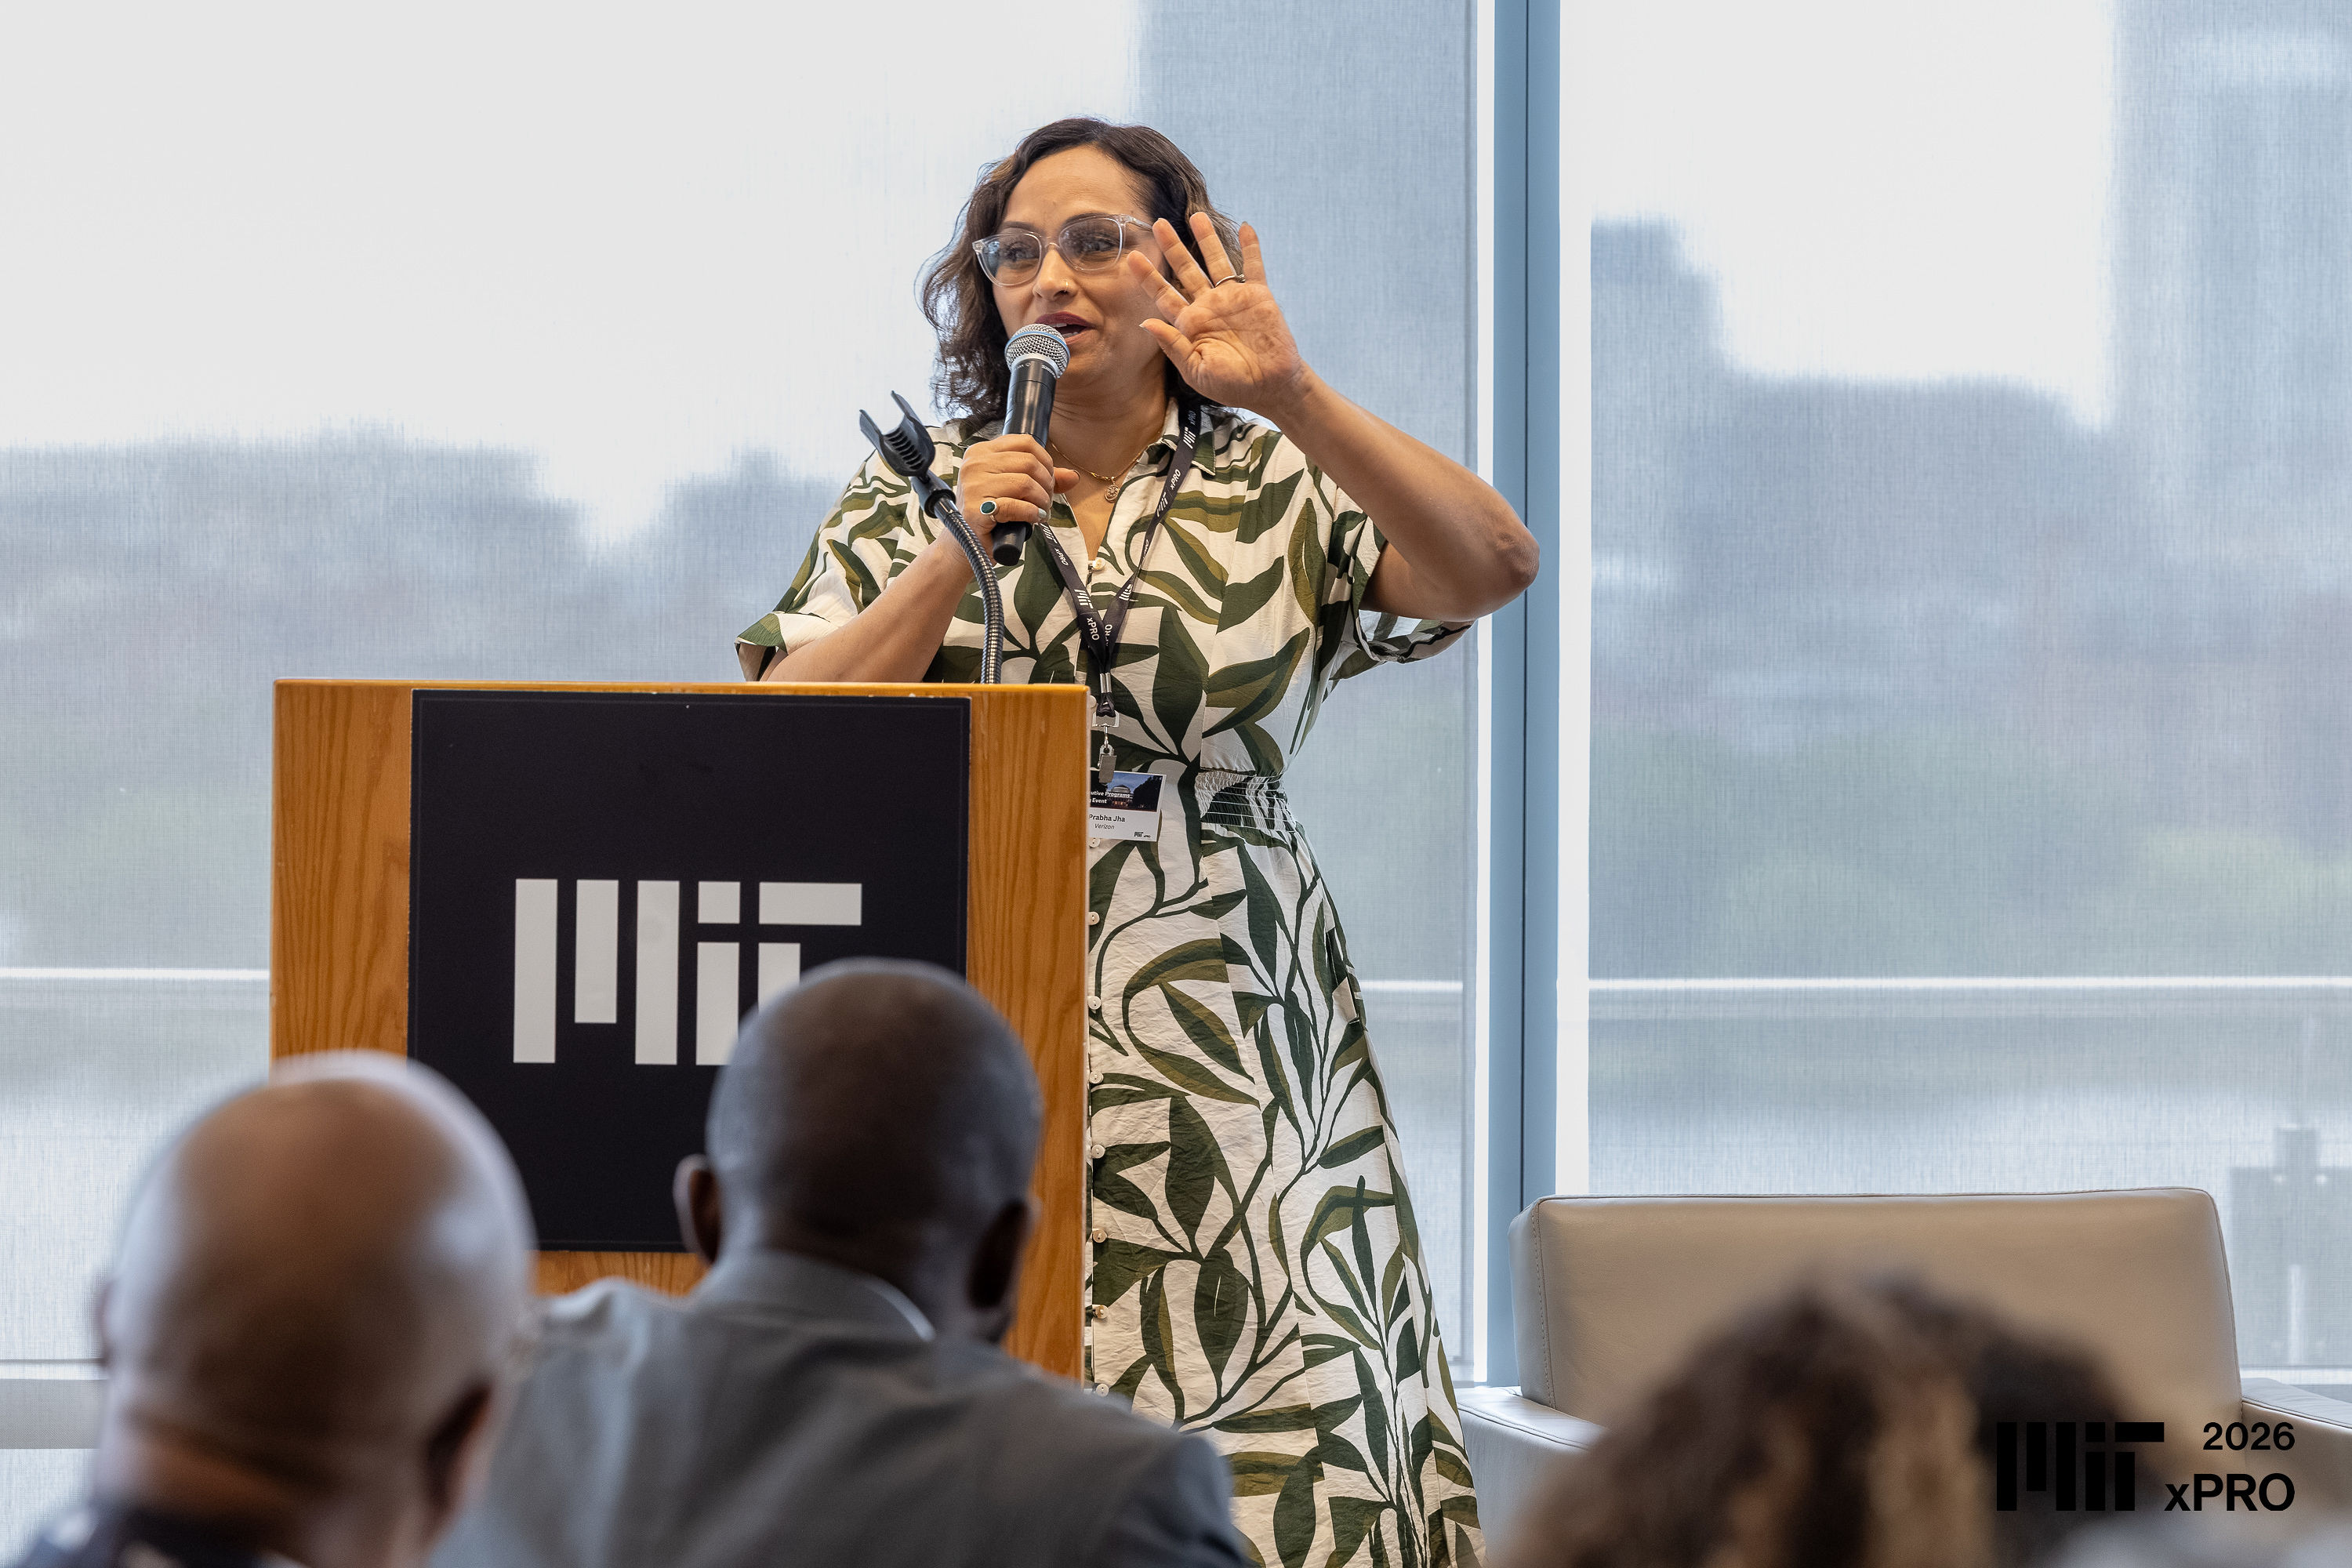
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.