The recurrent neural network transducer (RNN-T) remains a practical choice for streaming speech recognition, but training requires large intermediate tensors. We present Flash RNN-T, a joint and loss implementation combining specialized kernels with optional tiled recomputation over the full alignment space and vocabul...
Information-theoretic measures, such as Mutual Information (MI), play a crucial role in understanding non-linear relationships between random variables and are widely used across scientific disciplines. Yet, their use on real-world discrete data remains challenging. Existing methods typically rely on embedding discrete...
Alberto Foresti, Giulio Franzese, P. Michiardi· International Conference on...· 3 citations
In the classical principal-agent setting, the principal delegates some task to the agent, who receives a payment conditioned on the outcome of the task, which in turn benefits the principal. To align their objectives, the principal designs a contract that incentivizes the agent to take actions beneficial to the princip...
Elif Y{\i}lmaz, Jakub T{\l}uczek, Victor Villin et al.· 0 citations
A Wasserstein GAN equipped with a progressive Lipschitz penalty and an adaptive kernel with promising performance of the WGAN-CLP with an adaptive kernel framework in forecasting sequence alterations across the voltage and energy time-series datasets.
Najmieh Sadat Safarabadi· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
The Recursive Time-Series Model is introduced, which combines a learned convolutional temporal tokenizer, single-state weight-tied refinement, and a pooled classification readout, and the resulting classifier combines competitive accuracy with a shared refinement module whose parameter count is independent of computati...
Georg Tenzing, Anna Tegon, Luca Benini et al.· 0 citations
Low-rank adaptation (LoRA) has become the standard method for parameter-efficient fine-tuning of large pretrained models, yet theoretical explanations for why low-rank updates suffice remain incomplete. Most existing analyses rely on the Neural Tangent Kernel (NTK) regime, which linearizes the network around the pretra...
Long Nguyen-Chi, Quynh Nguyen, Thanh Nguyen-Cung et al.· 0 citations
Modern deep learning systems increasingly rely on high-dimensional vector operations, in which large input and parameter vectors are repeatedly stored, transferred, and processed. Although substantial research has focused on reducing neural-network model size through pruning, quantization, knowledge distillation, and e...
Pretrained models are often reused across downstream tasks, motivating the question of whether this transfer learning procedure can provide a substantial performance improvement, namely, in terms of the scaling law. We address this question in the prototypical setting of high-dimensional regression, where (i) a pretrai...
Yalda Shabanzadeh, Di-Yuan Wu, Marco Mondelli· 0 citations
The High Resolution Imaging Science Experiment (HiRISE) onboard the Mars Reconnaissance Orbiter (MRO) acquires imagery of Mars at 25--30 cm/pixel, supporting studies of martian geology, climate history, and landing-site characterization. Its 14-detector focal plane assembly includes several overlapping detectors that e...
A. Suphi, Ben Moseley, G. S. Collins et al.· 0 citations
Real-time inference on small devices needs low activation memory without extra latency, which makes operator order the most valuable memory lever: it is free in time. We show that the usual way of deploying a better order, handing it back to the compiler and regenerating code, is unreliable. In PyTorch Inductor the reg...
Ivan Fomin, Ivan Koryabkin, Boris Sheludko· 0 citations
The joint reconstruction of the initial pressure and spatially varying sound speed in photoacoustic tomography from boundary measurements is considered. A regularized data-driven framework is proposed in which the unknown fields are represented in finite-dimensional wavelet spaces and fixed nonlinear features generated...
Machine learning with limited data is susceptible to overfitting, especially with modern deep neural networks. Prior to the introduction of AlexNet, reconstruction-based pretraining with auto-encoder and denoising auto-encoder were found to be beneficial, partially due to the limited size of the training sets at the ti...
Qinyu Li, Yee Whye Teh, Chris Holmes et al.· 0 citations
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
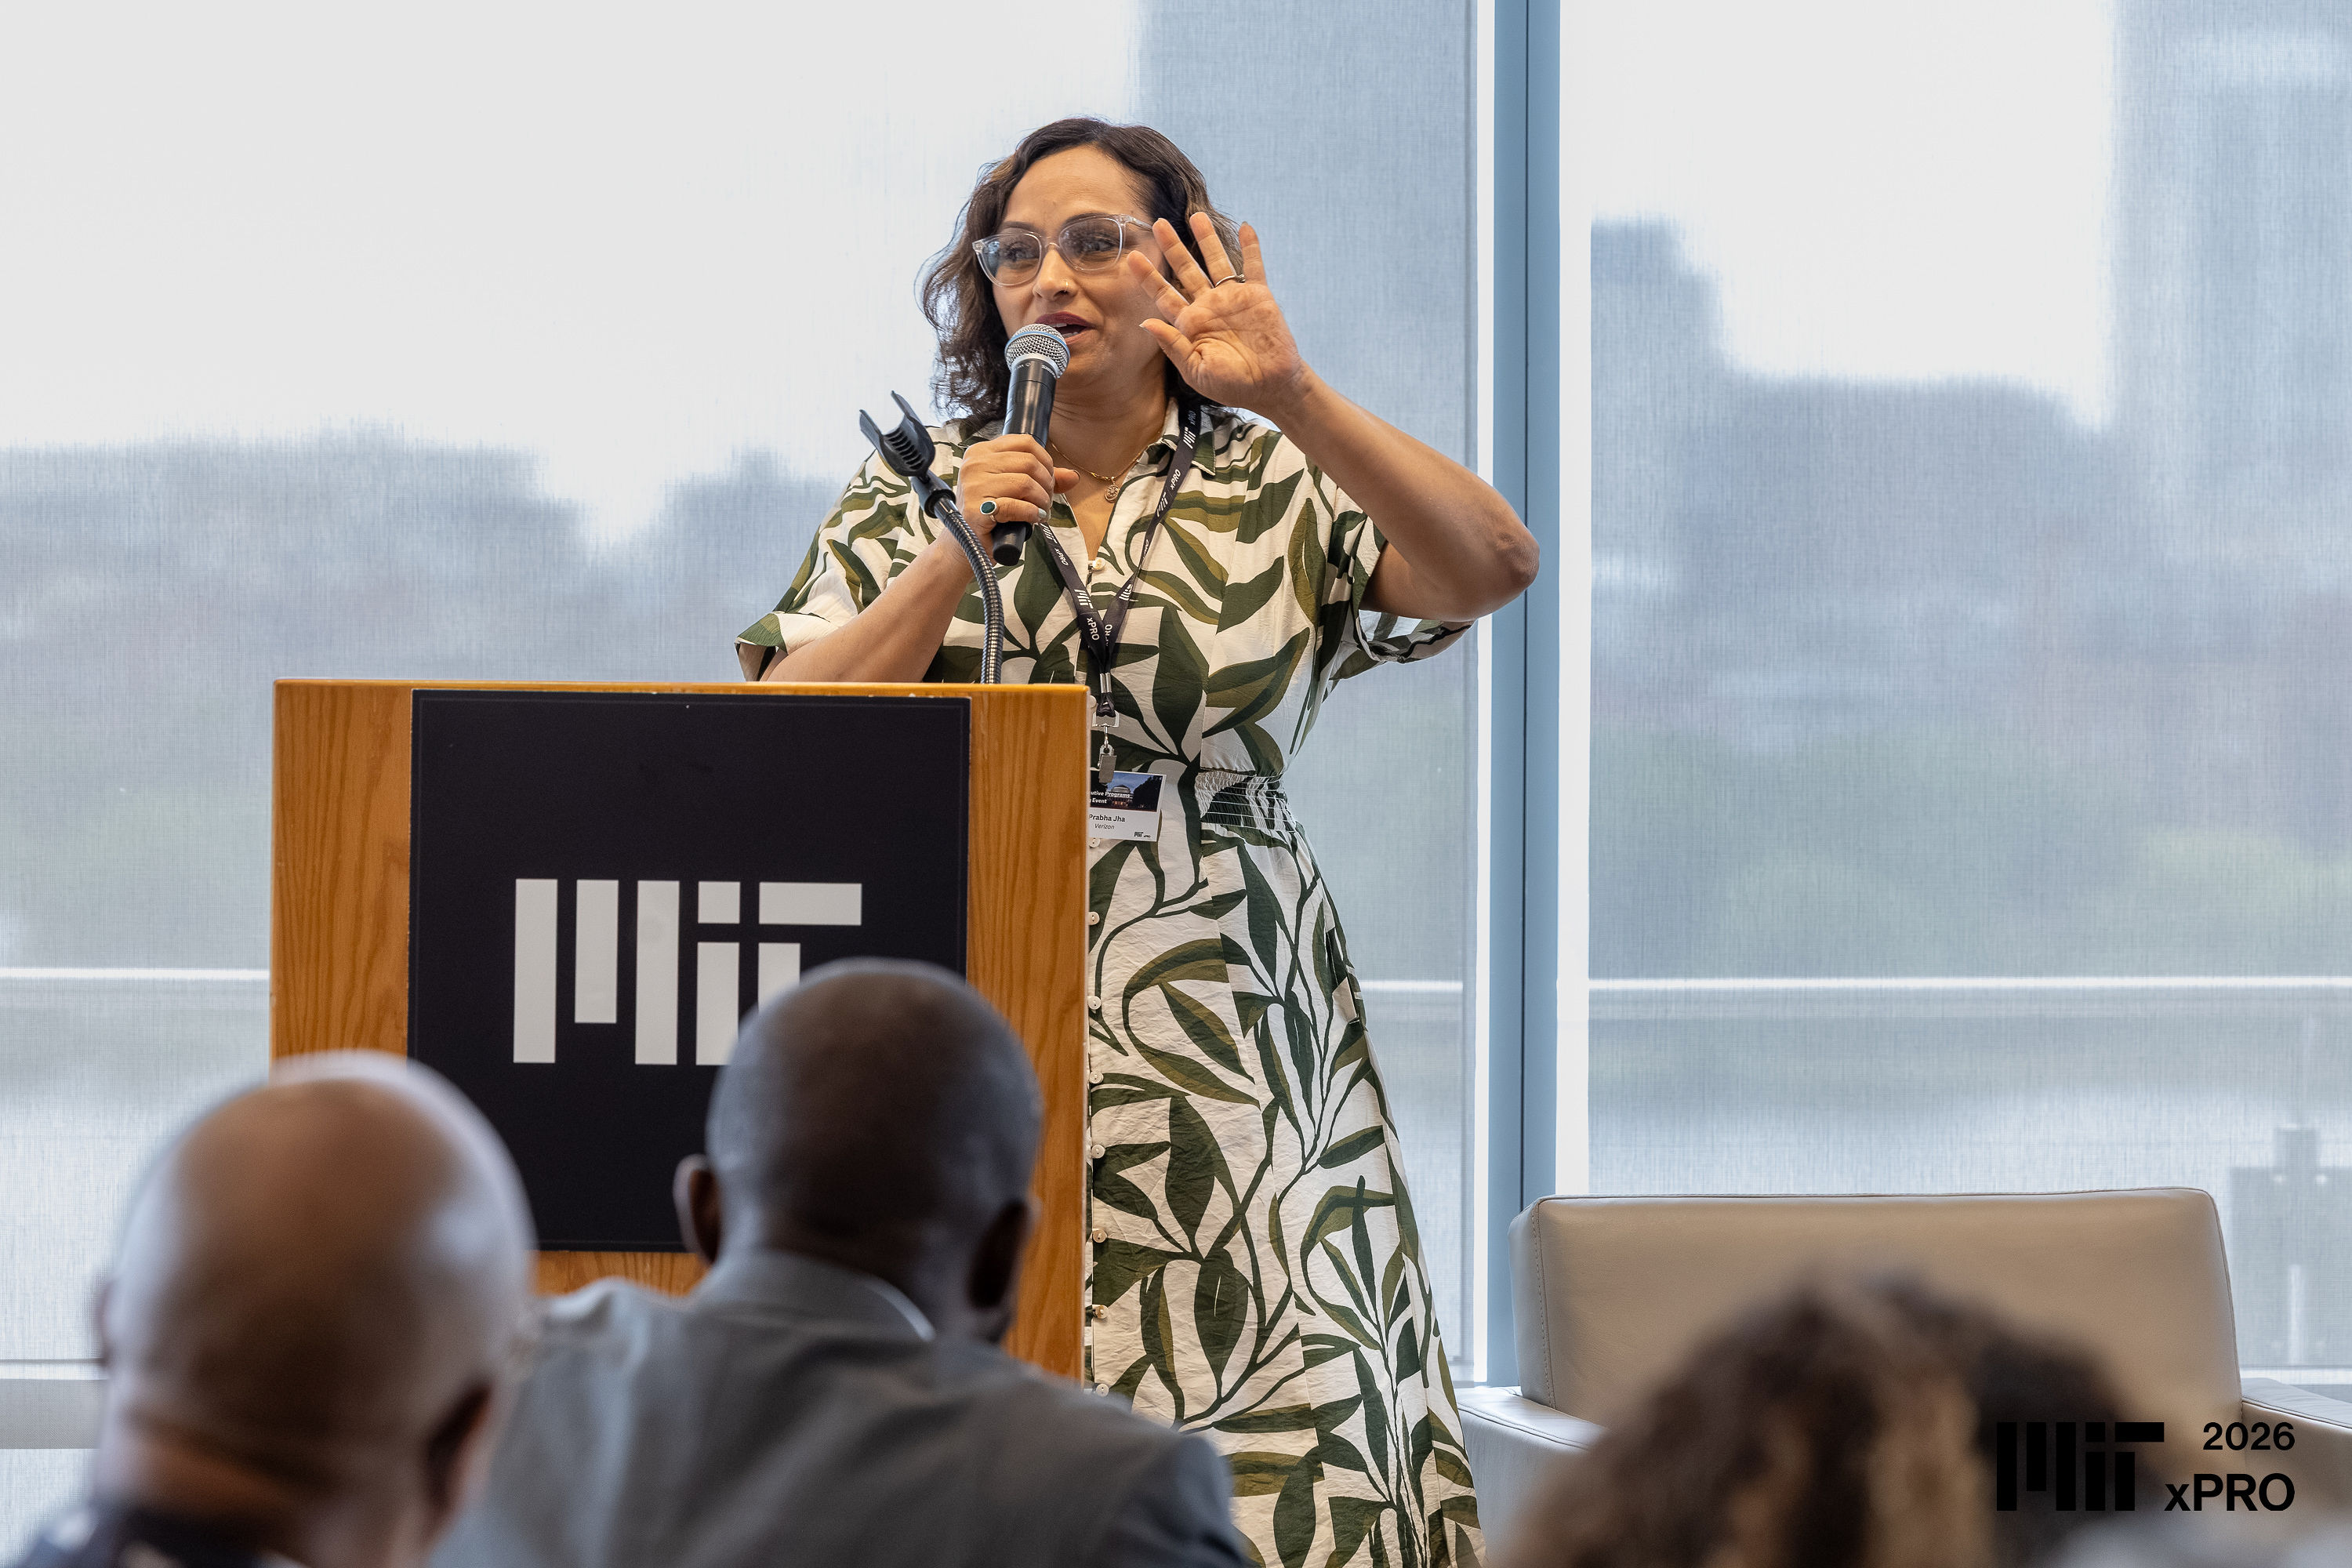
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.