Diffusion models achieve high-quality image generation but remain computationally expensive due to iterative denoising across many timesteps. Existing acceleration methods mainly reduce per-sample latency, but gains along this axis are becoming saturated. We instead explore an orthogonal throughput-oriented direction b...
Minkyu Kim, Baekseung Kim, Junhoo Lee et al.· 0 citations
Distribution shifts pose a fundamental challenge to robust multimodal learning. Existing methods typically promote invariance by suppressing environment-dependent variations, implicitly applying a uniform treatment to shifted information. However, shifted information can have different predictive consequences: some con...
Block Influence (BI) ranks Transformer blocks for depth pruning from their input-output cosine change, but the ranking depends on the calibration distribution. We study whether English calibration transfers to Indian languages in Qwen2.5-1.5B-Instruct, Llama-3.2-1B, and Gemma-2-2B. English, Hindi, Marathi, and Tamil us...
Test-time scaling can improve the performance of large language models by generating multiple answers to a question and aggregating them. Weighted ensembles extend this idea by drawing answers from several models, with the weights determining how often each model is used. Learning these weights from a training dataset...
Zhi Zhang, Arash A. Amini· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Healthcare institutions routinely accumulate high-dimensional computed tomography (CT) volumes, but only a fraction can be annotated by experts. We present L2GSSL, a local-to-global self-supervised learning framework that leverages unlabeled volumes by decomposing pretraining into intra-slice and inter-slice representa...
Classical PAC-Bayesian generalization theory places prior distributions over Euclidean parameter space $\Theta \subseteq \mathbb{R}^D$, causing relative entropy to scale with network dimension $D$. For modern overparameterized neural networks where $D \gg n$, this parameter-counting dependency yields vacuous generaliza...
Generative low-light enhancers recover plausible texture but may hallucinate structure; restoration networks preserve structure but can leave regions under-enhanced, and neither advantage is spatially uniform. Therefore, we formulate selective generative enhancement as a decision problem: determine where overriding a f...
Qiyi Xie, Wei Chen Ng, Suyang Xi et al.· 0 citations
Pretrained latent spaces trade compression, reconstruction, and the learnability of the coordinates a downstream generator has to work in, which complicates adapting these spaces to different domains or tasks: continued training is expensive, and without a new alignment objective it often fails to improve downstream ge...
Felix Nützel, Mischa Dombrowski, Luca Hagen et al.· 0 citations
Reinforcement learning with verifiable rewards (RLVR) math corpora are routinely screened for benchmark overlap, but the reliability and data-loss costs of cleaning policies remain underexamined. We audit sixteen open RLVR math corpora comprising 1,673,514 corpus-specific training items against six benchmarks containin...
Traditional backdoor attacks inject artificial trigger patterns into training data, causing models to misclassify triggered inputs while maintaining normal behavior on clean samples. Since these artificial triggers are absent in clean datasets, standard knowledge distillation (KD) typically eliminates them, leading to...
Junhoo Lee, Baekseung Kim, Seungyeon Kim et al.· 0 citations
Synchronous data-parallel training usually assigns every rank the same number of records, even when record costs vary by orders of magnitude. For variable-length models, this converts input variation into idle time because each step waits for its most expensive rank-local batch. We present Batch Cost Lookahead (BCL), a...
Tao Huang, Chen Zhu, Antonio Alonso et al.· 0 citations
We characterize the multiplicative half-Cauchy process through its log-scale random-walk representation, establishing shrinkage, expansion, and critical regimes, almost-sure summability, local rebounds, and effective dimension. We also derive a semi-analytic calibration rule linking interpretable prior probability stat...
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
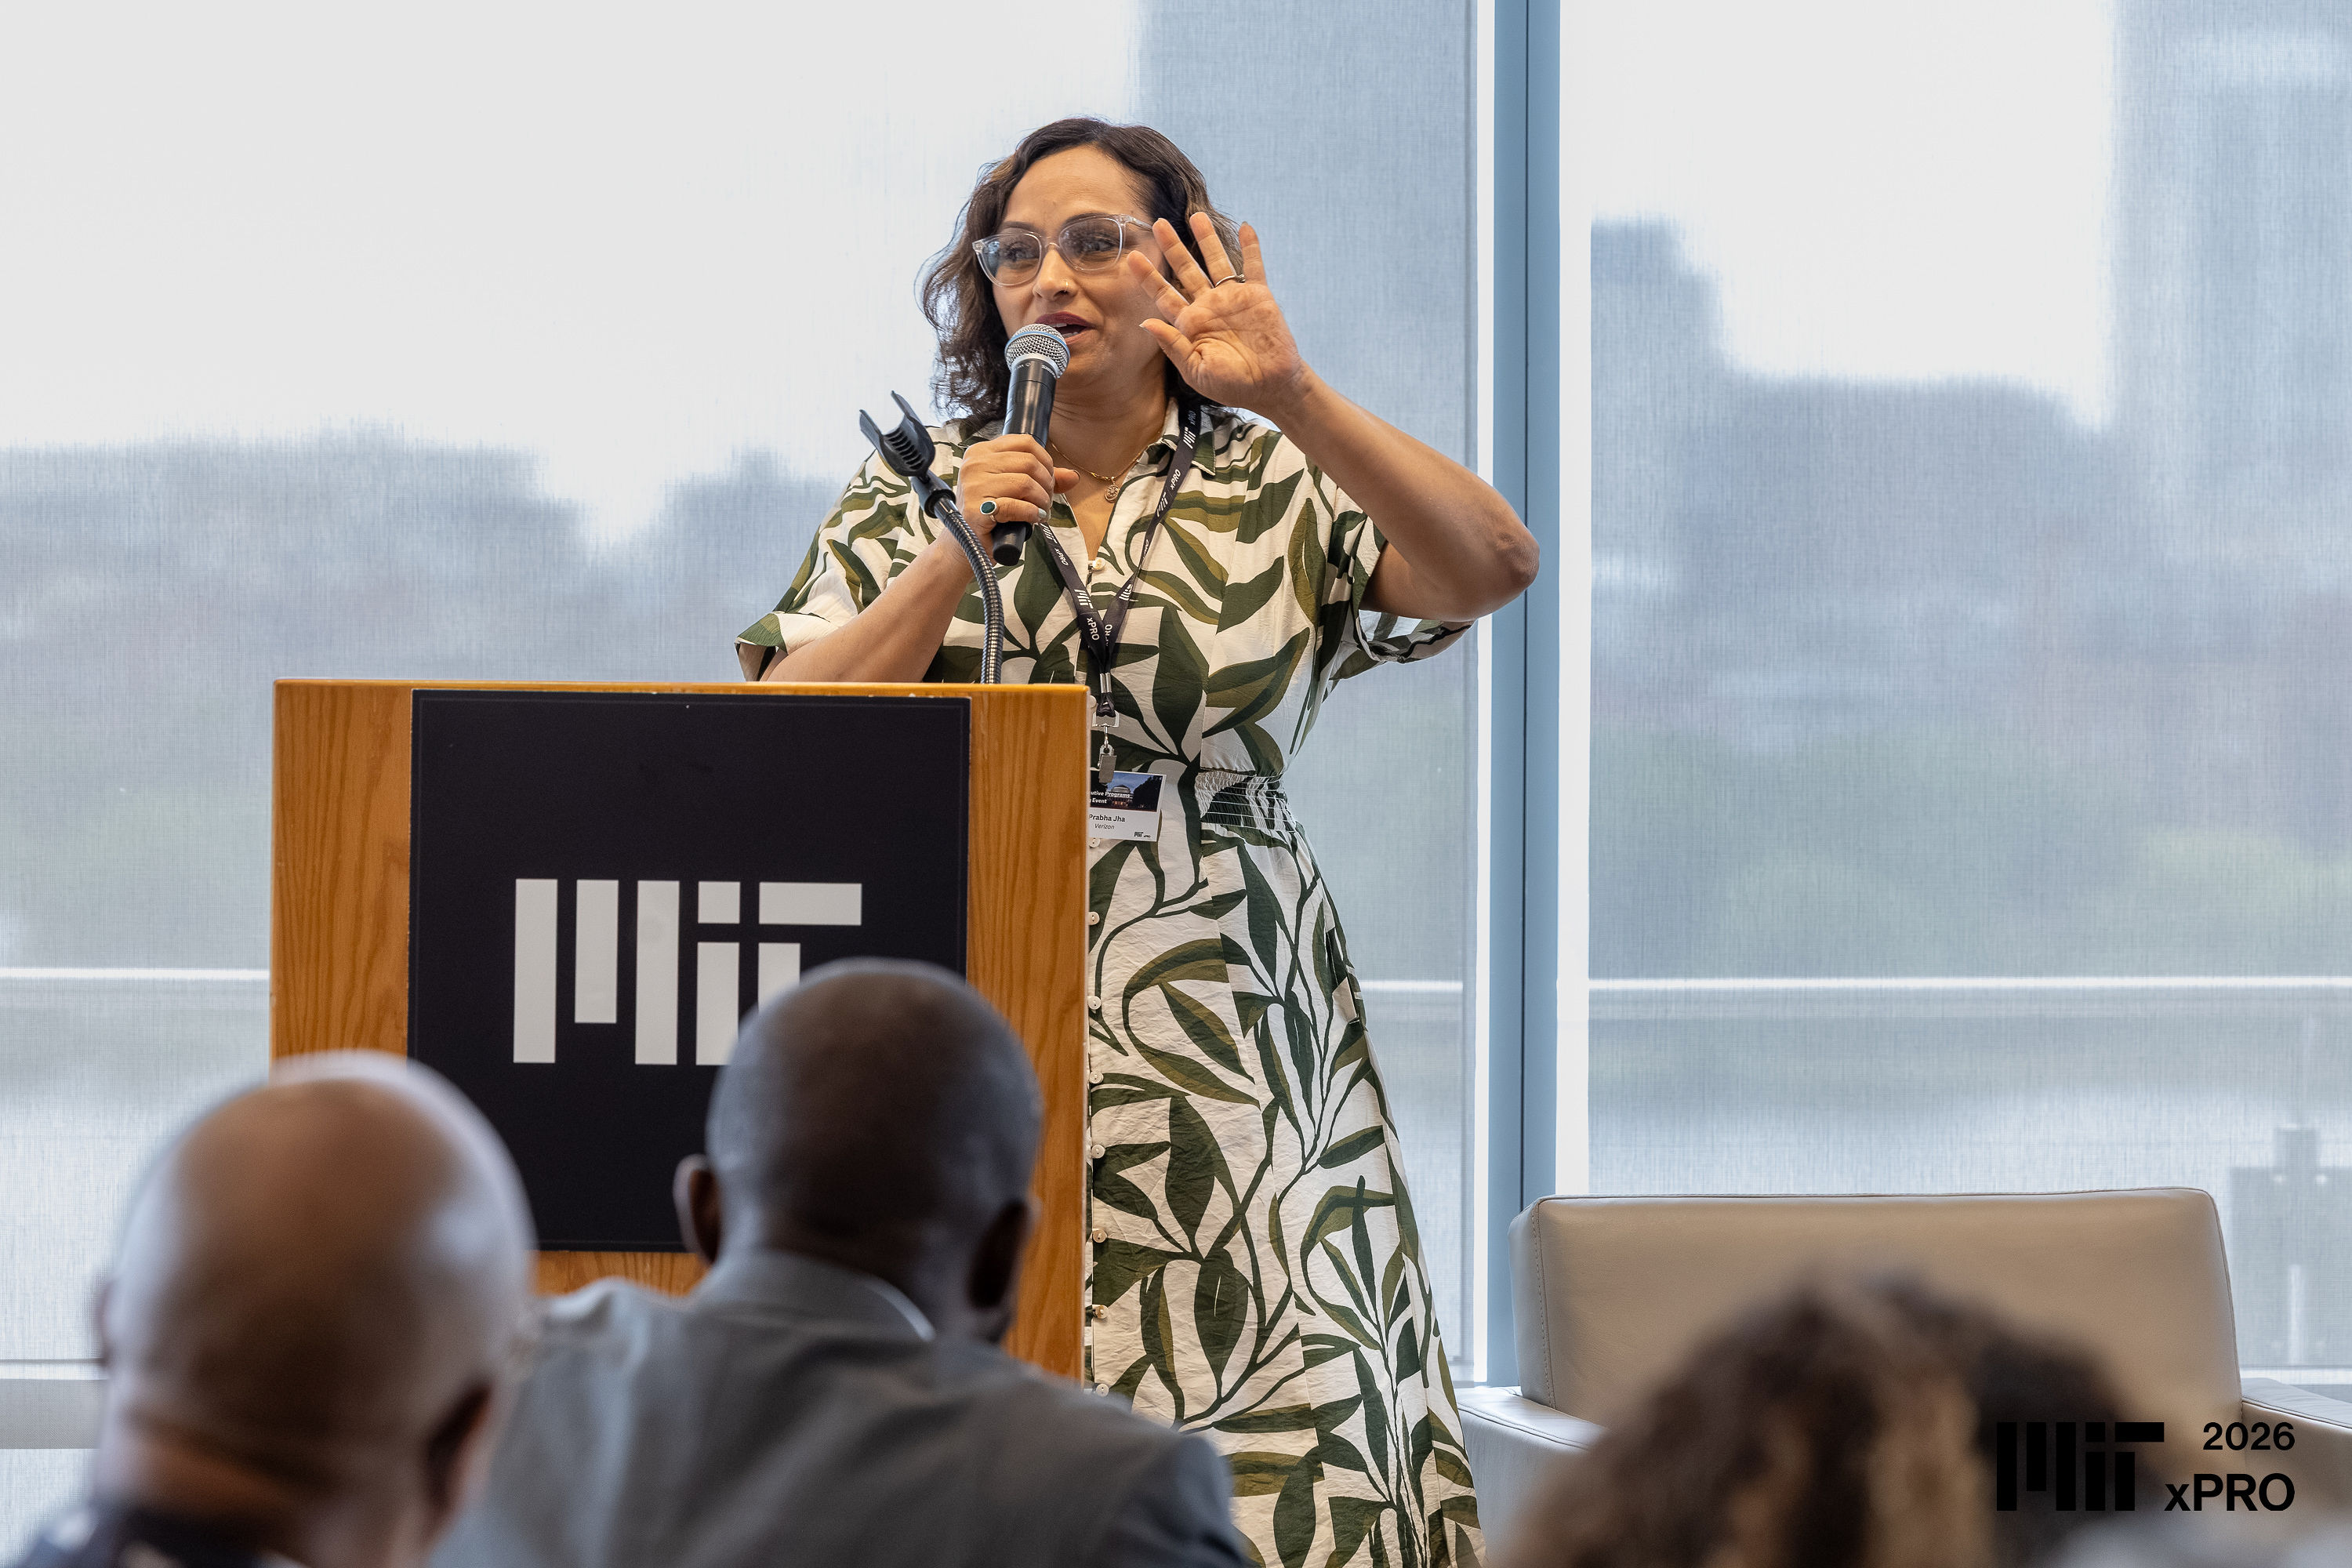
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.