This work proposes SFRBE--RaNN, a two-stage adaptive trial-space construction that combines safeguarded SFR with RBE capture factors to derive a finite-horizon error bound involving baseline best approximation and empirical consistency, together with a conditional random-search success-probability bound.
Discrete diffusion models have become a powerful framework for modeling complex discrete distributions across a range of applications. While theoretical convergence guarantees depend on consistency between the target and training distributions, such a case rarely holds in practice, making score mismatch a central chall...
Ren-Xiang Huang, Yu-Chen Liang, Ying-Bin Liang et al.· 0 citations
Extracting insights from textual data while protecting user privacy is increasingly important. Existing methods produce private insights in diverse forms for different analytical purposes, making their utility difficult to assess and compare. In this work, we formulate differentially private (DP) insights as reusable r...
Kai Chen, Gui-Si Ni, Albert Cheu et al.· 0 citations
We propose a general framework for non-interactive locally differentially private (LDP) learning of structured univariate distributions that can be approximated by piece-wise polynomials. This gives the first sample-efficient LDP learners for several distribution classes, including mixtures of log-concave distributions...
Mohammad Afzali, Hassan Ashtiani, Sivan Sabato· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
In stochastic (strongly) convex optimization, establishing last-iterate convergence guarantees for first-order methods has recently garnered increasing attention, as this not only deepens the theoretical understanding of these algorithms but also aligns more closely with practice. Notably, people have demonstrated that...
We study whether the classical momentum-based acceleration that improves the condition-number dependence of gradient descent from $\kappa$ to $\sqrt{\kappa}$ for strongly convex, smooth objectives extends to Gaussian variational inference (GVI) for strongly log-concave, log-smooth target distributions. With exact Gauss...
Jaesung R. Park, Uijeong Jang, Yi-Fan Chen· 0 citations
A multimodal dog-fingerprinting framework combining visual identification, multiple-object tracking, and canine vocal fingerprinting to associate bark events with individual dogs while maintaining persistent profiles is presented.
Aryahvishwa Babu, Kingsley Jin, Li-Lin Wang et al.· 0 citations
To use language models to help us make decisions we would like to understand the rationale behind the language model's outputs. In principle, the language model provides its rationale as part of its text output. However, the sheer volume of text makes this hard to use in practice. In this paper, we are interested in ex...
David Reber, James Reber, Ari Holtzman et al.· 0 citations
Reordering multiple-choice options can change a model's answer, an effect studied as selection bias (a preference for certain option letters) and as order sensitivity (changes in answers across option orderings). We connect these perspectives through the pooled selection-rate standard deviation (pooled SD), which measu...
We report Monte Carlo simulations of a continuous spin variant of the Blume-Capel model. We compute the phase diagrams in the crystal-field-temperature plane, as a function of the softness of the spins. We show that normalizing flows, a class of generative models capable of direct sampling without autocorrelation, are...
Ejaaz Merali, Ryan Larson, Ehsan Khatami et al.· 0 citations
Generative modeling across related distributions raises a question: how can shared structure support accurate generation for a target distribution with limited observations? We develop a statistical framework for diffusion transfer that analyzes a shared pooled score together with a target-specific offset. Under Besov...
Huitao Yang, Oscar Hernan Madrid Padilla· 0 citations
State-of-the-art text-to-music models increasingly rely on scaling model capacity, data, and compute, while still learning musical structure directly from dense audio. Yet melody, rhythm, harmony, and structure can be represented compactly in symbolic form. We introduce MIDI-REPA, a representation-alignment framework t...
Song Yu, Fang-Duo Tsai, Yi-Hsuan Yang· 0 citations
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
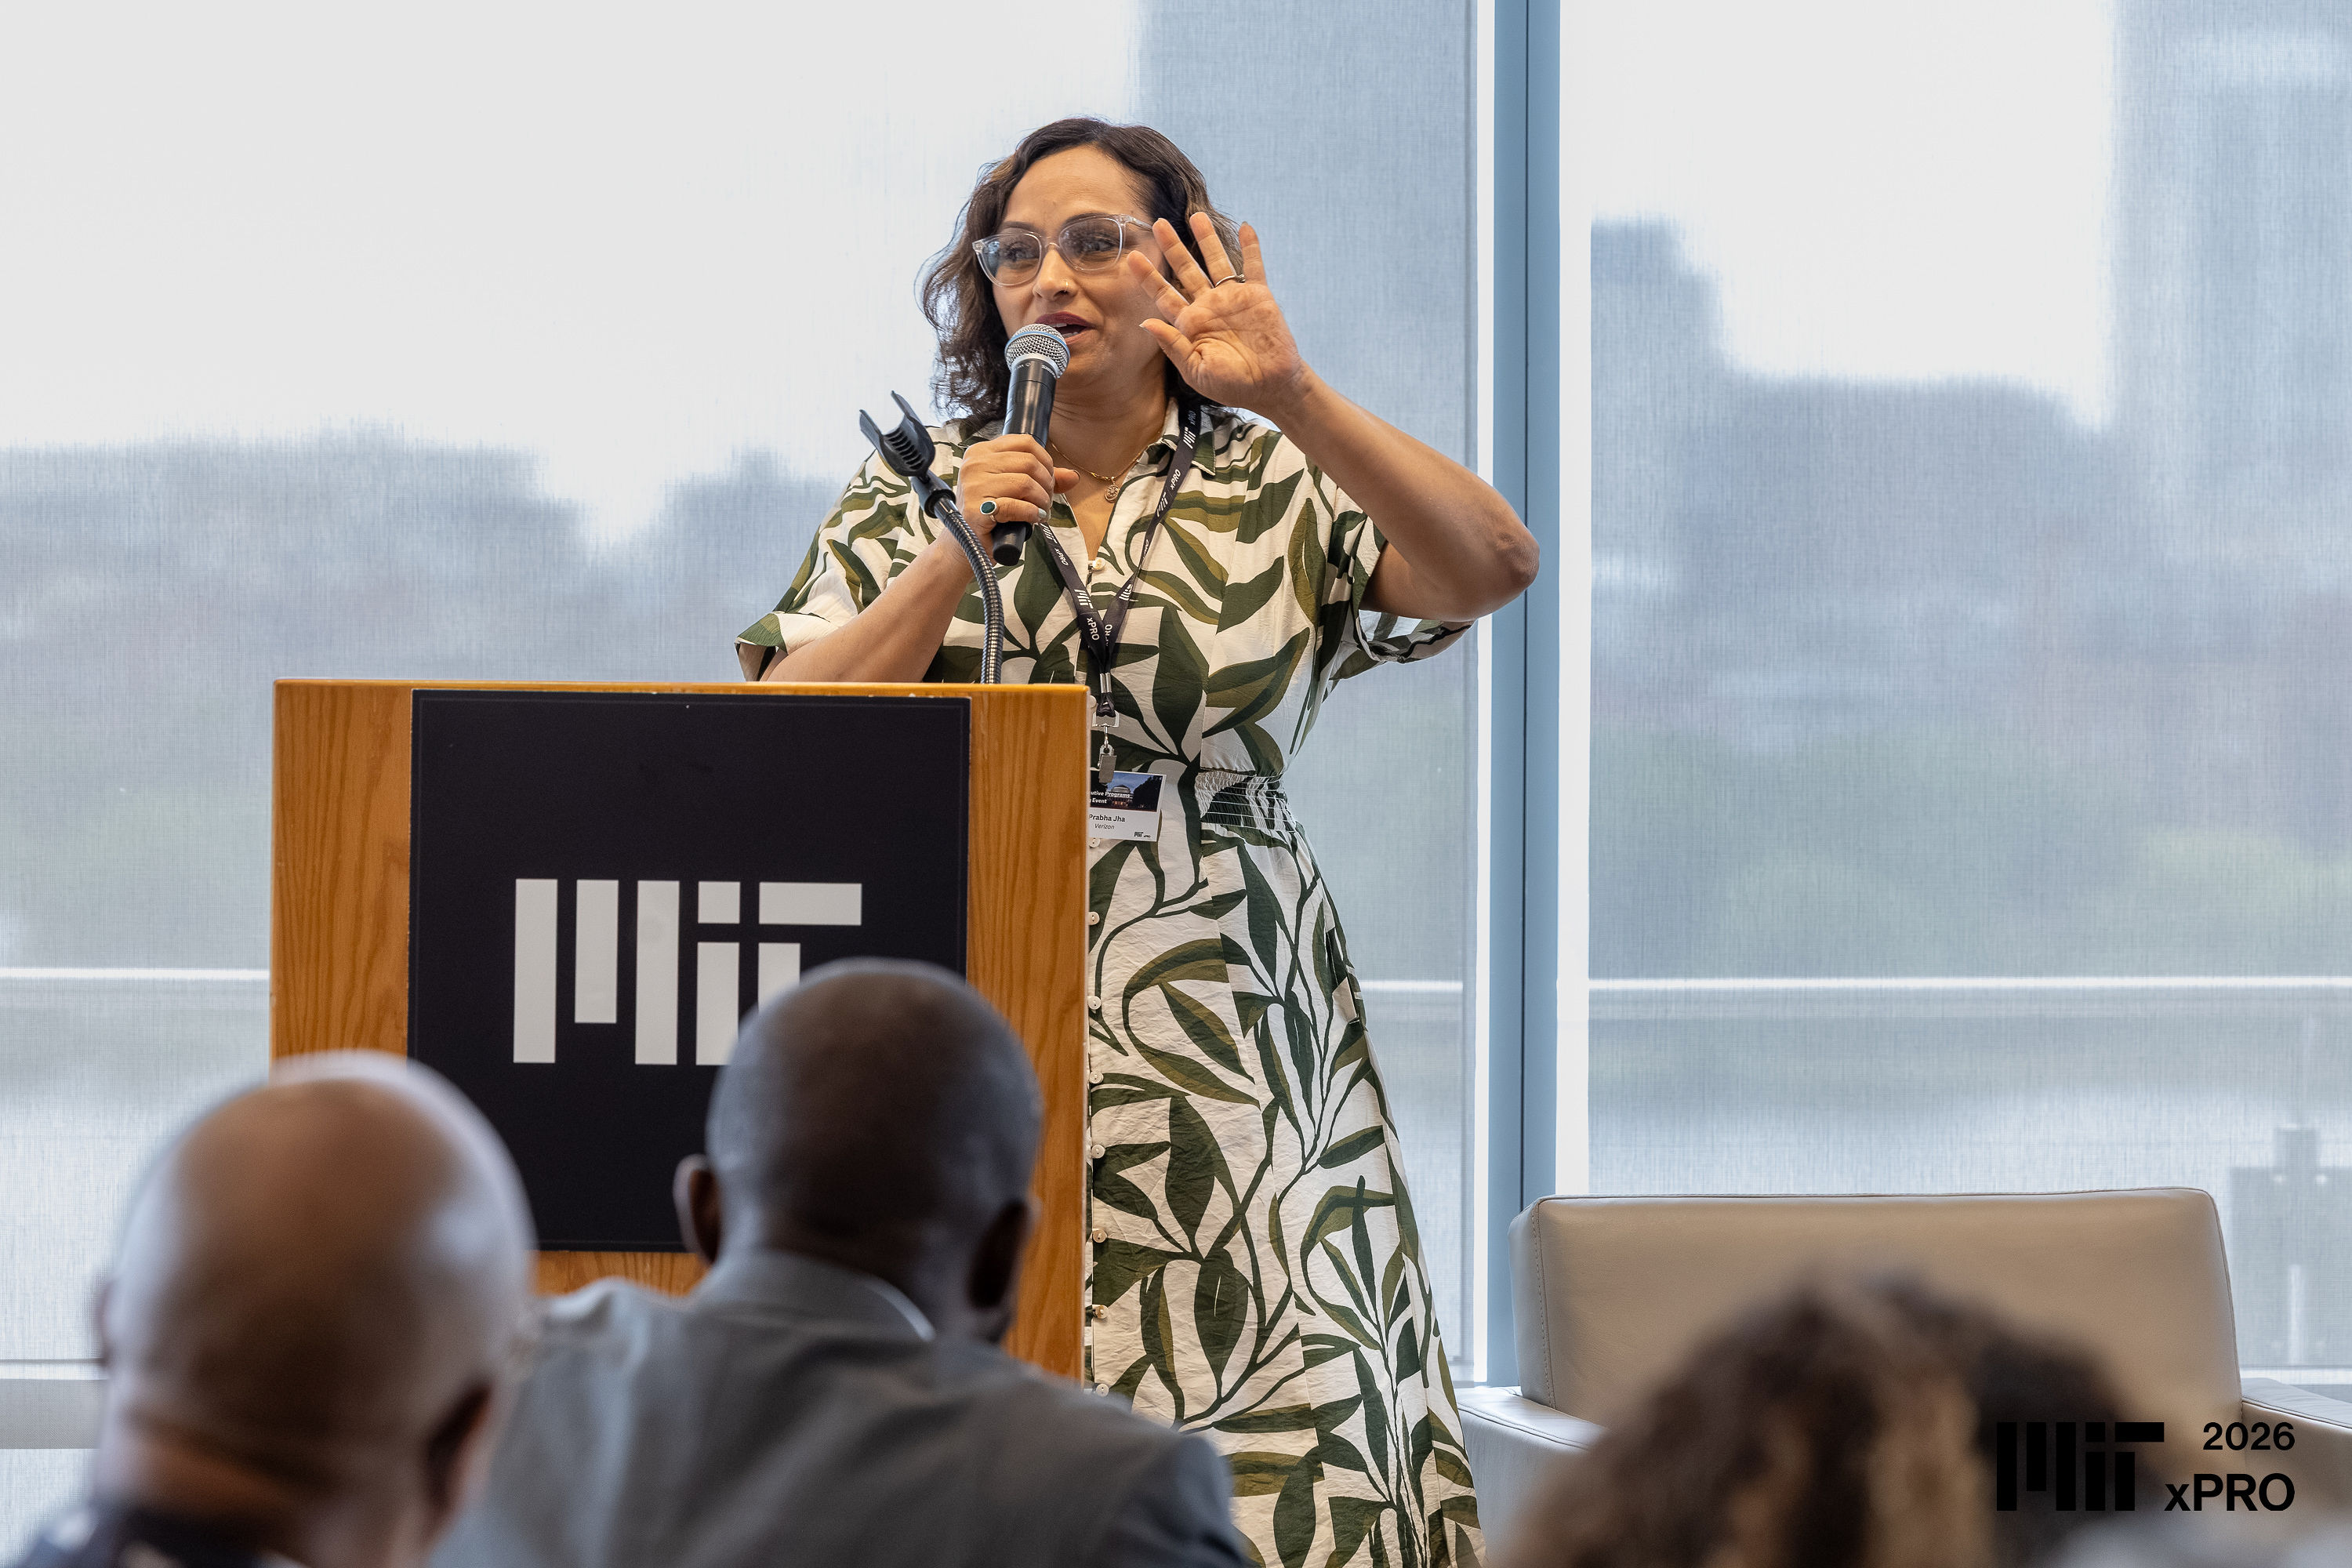
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.