This work proposes a steering agent that supervises execution on the fly and steers the system back on track when drift occurs, and jointly train the two paths with reinforcement learning, combining a pairwise ranking objective with group-relative policy optimization (GRPO).
Le-Yang Shen, Ya-Xin Gong, Yang Zhang et al.· 0 citations
Not all facts a language model can recall support further learning equally well. We distinguish active facts, which support generalization beyond their own recall, from inert facts, which can be recalled but do not support such generalization in a given task. We study this distinction by constructing new relations from...
Large language models (LLMs) acquire new skills through fine-tuning, but it can destroy capabilities they already have: catastrophic forgetting remains a central obstacle to continual learning in LLMs. Recent works connect forgetting to how far, and along which directions, fine-tuning moves the weights. On-policy metho...
Arnav Chavan, Kusha Sareen, Rishabh Tiwari et al.· 0 citations
An informed prior is built that targets preference queries at the features that need resolving, and each query is accompanied with an explanation that focuses the human's attention on exactly those features.
Helena A. Merker, Nick Walker, Andreea Bobu· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Reasoning over long document contexts remains a challenge for large language models (LLMs). Standard retrieval methods are inherently reactive, bottlenecking agents with complex, cross-document reasoning at inference time, while precomputed structures like knowledge graphs often fall short because they rely on rigid he...
Anikait Singh, Teresa Zhang, Yoonho Lee et al.· 0 citations
This work builds LinguaGuardBench from the 1,220 labelled steps of TS-Bench AgentDojo-Traj, translating only the user instruction into German, French, Turkish, Swahili and Amharic, and keeps every tool call, observation and label byte-identical, so any change in a verdict is attributable to language alone.
On-policy distillation consolidates specialist models into one student at the price of rollouts, teacher passes and gradient steps for every teacher. We show that the consolidation does not need training: with forward passes only, the capabilities of separately tuned specialists can be aggregated into one model that is...
Bang Yang, Jia-Jun Fan, Zhao-Yu Zhu et al.· 0 citations
Real desktop automation is neither purely visual nor purely programmatic. Agents must understand user-facing interfaces while efficiently manipulating files, scripts, and system state. However, native GUI/code coordination cannot be obtained by prompt-level tool composition. In our preliminary experiments, naively addi...
Bowen Yang, K. Jin, Zichen Ding et al.· 0 citations
Agent memory benchmarks evaluate whether an agent's responses reflect correct knowledge, measuring downstream question-answering accuracy as a proxy for memory quality. We show this evaluation paradigm is incomplete: it conflates memory correctness with retrieval and generation quality, producing both false positives w...
Sebastian-Antonio Toma, Jean de Kernier, Mike Ply et al.· 0 citations
Current humanoid dexterous manipulation remains largely confined to end-effectors and simple grasps, falling short of humans'ability to engage the entire body by bracing and sliding bulky objects against the arms and torso. We introduce Whole-Body Dexterity (WBD), a general framework that uses the robot's body and appe...
Conor Mc Gartoll, An Dang, Pranay Thangeda et al.· 0 citations
Most existing agentic reinforcement learning methods assume single-session trajectories, where interaction proceeds within one continuously accumulated context. However, agentic techniques such as context compaction and subagent forking may produce trajectories spanning multiple sessions, creating a mismatch between th...
Yilong Xu, Minrui Xu, Xinyu Zhou et al.· 0 citations
Reinforcement learning agents optimize exactly the reward signal they are given, which can diverge sharply from an intended true objective when that signal is only a proxy for it; this failure mode is known as specification gaming. Existing evidence for this failure mode is largely observational, with comparatively few...
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
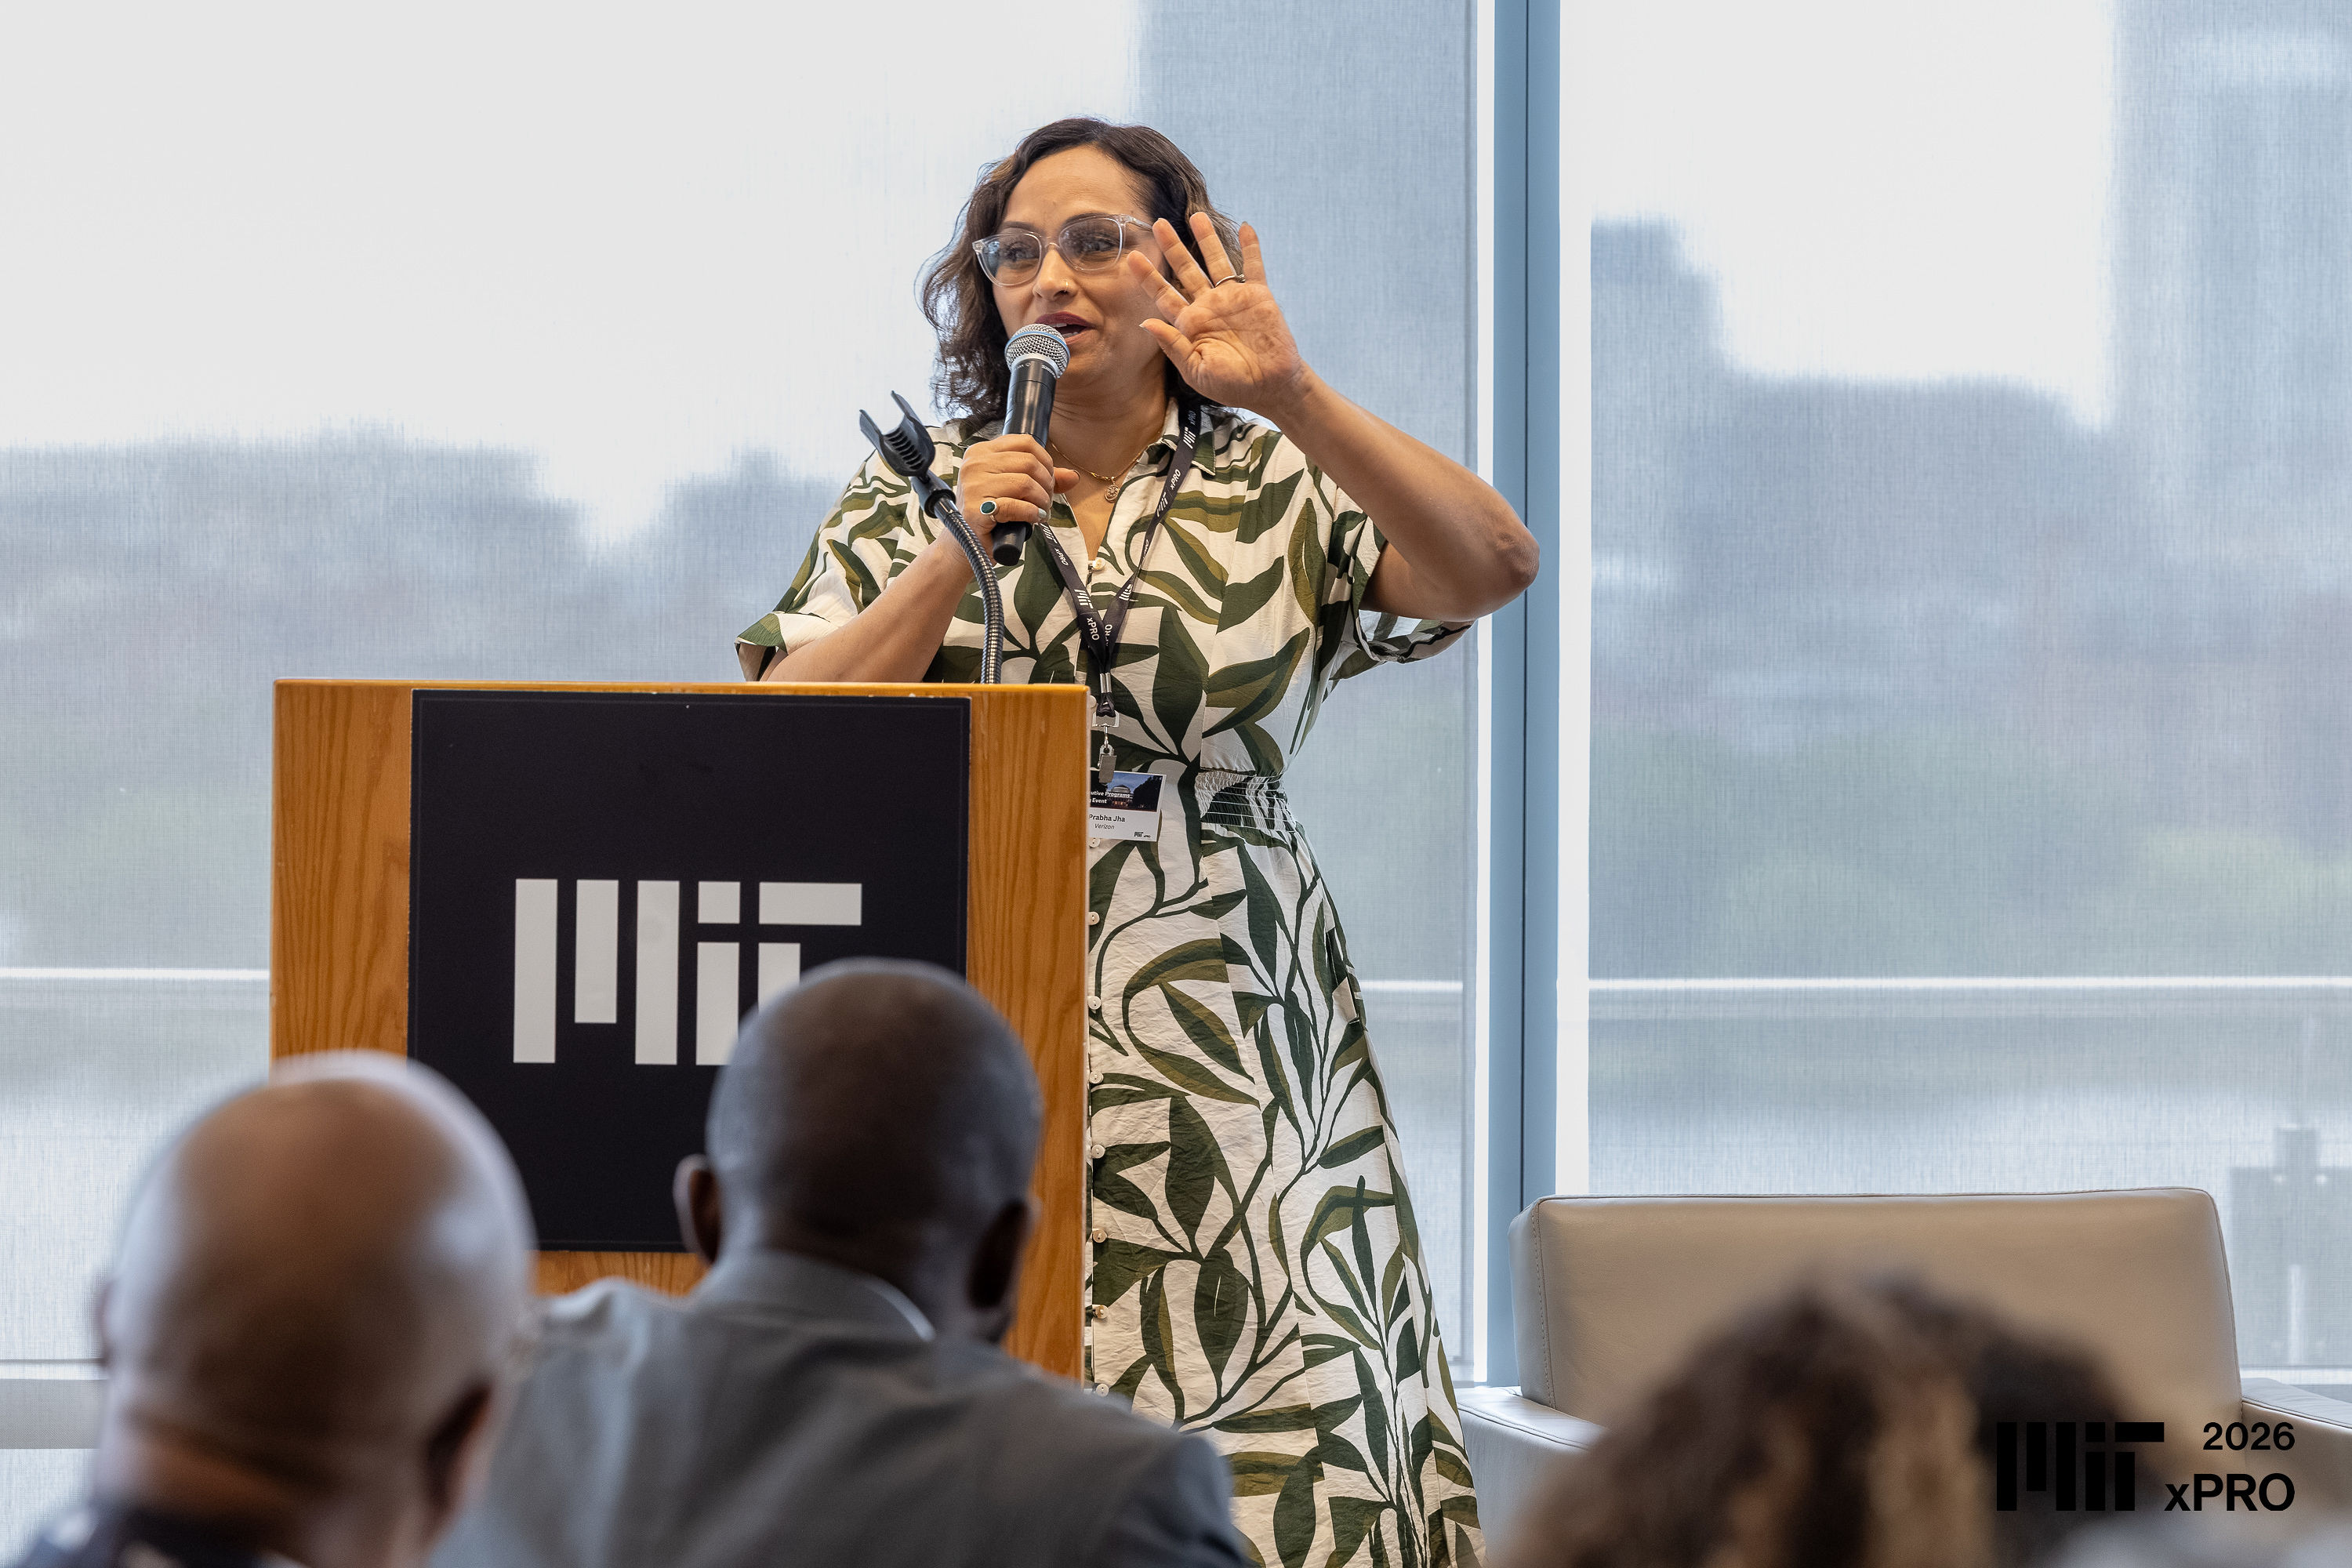
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.