Reward generation is a central component of reinforcement learning, preference optimization, and self-improvement in large language models (LLMs). Existing approaches have demonstrated that an LLM can evaluate its own outputs and use the resulting judgments to improve its behavior. However, self-rewarding systems may s...
Jincheng Zhang· Zenodo (CERN European Organi...· 0 citations
Large language models (LLMs) can generate candidate answers, evaluate their quality, and use evaluation signals to improve subsequent responses. However, self-evaluation may reinforce a model's own biases and errors, whereas evaluation by other models may introduce evaluator disagreement, capability mismatches, and cor...
Jincheng Zhang· Zenodo (CERN European Organi...· 0 citations
The increasing complexity of real-time electricity markets and fluctuating load demands challenges traditional economic dispatch methods, which often fail to balance cost efficiency and system reliability. This study presents a Deep Reinforcement Learning (DRL) framework for real-time power dispatch, enabling adaptive...
Ekeriance Evanson Dominic, Cherukei Agbara· Iconic research and engineer...· 0 citations
This paper presents AURA (Autonomous Urban Reconnaissance Array), a ROS 2-based drone swarm system designed to restore emergency WiFi communication in post-earthquake disaster zones. The system deploys five coordinated UAVs that autonomously establish a selfhealing mesh network. The architecture integrates PX4SITL with...
Hussein Khadra, Constandinos X. Mavromoustakis, George N. Mastorakis et al.· Zenodo (CERN European Organi...· 0 citations
Bias amplification, the tendency of trained models to be more biased than the data that produced them, is well documented in supervised learning. We study it in policy-gradient reinforcement learning, where there is no static dataset: each episode belongs to a latent group that shapes the reward but is invisible to the...
Juan Ignacio Fiore, Matthieu Jonckheere· Zenodo (CERN European Organi...· 0 citations
This study introduces sPPO-CR, a policy-gradient deep reinforcement learning (DRL) algorithm for multi-objective (MO) and multi-condition multi-objective (MCMO) optimization. The method builds on a simplified single-step variant of Proximal Policy Optimization (PPO) and incorporates a Chebyshev-based reproduction mecha...
Dasun Shalila Balasooriya, Alan Blair, Ben Wilks et al.· ACM Transactions on Evolutio...· 0 citations
Abstract Millimeter-wave reconfigurable intelligent surface (RIS) panels restricted to 1bit or 2-bit discrete phase shifts must synthesize arbitrary beam patterns from a solution space that grows exponentially with the number of reflecting elements. Existing two-dimensional finite-impulse-response filter analogies comp...
Praween Kumar Nishad, Govind Prasad· Engineering Research Express· 0 citations
Abstract Multi-qubit gates are crucial to realizing quantum algorithms. Direct implementation of these gates will facilitate a reduction in circuit depth. However, existing model-based methods rely on precise characterization of the system Hamiltonian as well as execution of the control fields, which present challenges...
Xinxin Zhu, Yangyang Fei, Liu FuDong et al.· Machine Learning Science and...· 0 citations
Large language models (LLMs) can be improved through self-generated feedback, reward-guided optimization, self-play, and interactions among multiple agents. However, a system that consistently relies on one reinforcement mode may fail to exploit complementary learning opportunities. Self-reinforcement enables an indivi...
Jincheng Zhang· Zenodo (CERN European Organi...· 0 citations
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
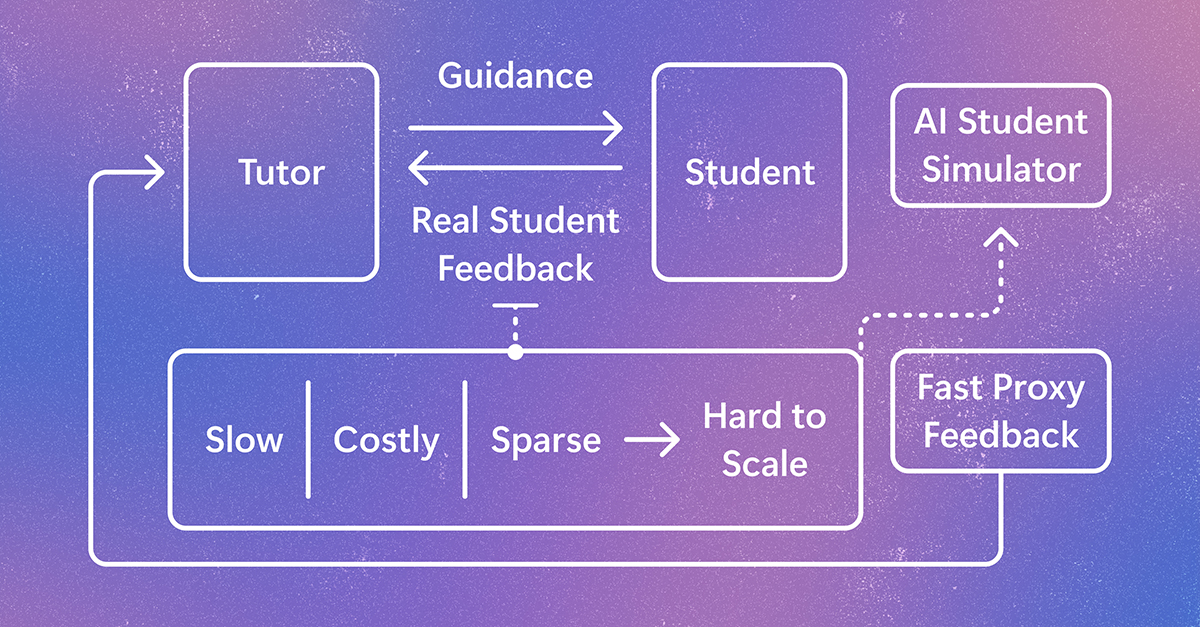
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.