This case study documents a CRA preparedness pilot for one such product, SEUXDR, an AI-augmented security monitoring product with a large-language-model active-response component on the open-source CYBERFORT platform, and offers practitioners a replicable starting point for translating CRA legal text into operational p...
Georgios Koutidis, Nikolaos Kekatos, Marina Korgiala-Karyda et al.· 0 citations
SCSM constructs pairs of pretraining views from the same group of unlabeled traces through Segmentation, Combination, Scaling, and Masking, which produces diverse observable patterns while preserving the underlying packet events and local traffic dynamics of real trace fragments.
Xian-Wen Deng, Rui-Jie Zhao, Ming-Wei Zhan et al.· 0 citations
IndexAct is proposed, an interface for Index-Native Corpus Interaction that separates candidate-set refinement from text inspection, and achieves higher evidence coverage with a smaller average live context than terminal-based corpus interfaces, and maintains answer accuracy as the corpus expands.
Deogyong Kim, Sunghwan Kim, Sangam Lee et al.· 0 citations
BARE-AI, a runtime framework that detects, localizes, and mitigates BFAs during inference, and introduces AI Performance Counters, lightweight hardware monitors in the accelerator datapath that capture per-layer activation statistics such as sparsity, entropy, kurtosis, and spectral shift.
Habibur Rahaman, Swastik Bhattacharya, Sanjay Das et al.· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Large Language Models (LLMs) have disrupted the balance between content production and quality assurance that sustains knowledge commons, leading many to prohibit or restrict their use. But what happens when a community instead appropriates an LLM-powered tool for its own needs? We investigate this question through Wik...
Inhwa Song, Sohyeon Hwang, Teddi Yoo et al.· 0 citations
Fine-grained emotion recognition supports therapy tools and social robots, but it needs facial data, which raises privacy and data-protection concerns. EmoNet-Face-HQ answers that with generated portraits, expert-rated over a $40$-category taxonomy far finer than the usual six to eight basic emotions. Under the protoco...
T. Hallmen, Fabian Deuser, Robin-Nico Kampa et al.· 0 citations
QRAKEN is a training-free, ontology-agnostic neurosymbolic pipeline grounding generation in empirical graph evidence rather than schema expectations, supporting the value of empirical patterns beyond schema exposure.
Remo Grillo, L. Klic, Giovanni Colavizza· 0 citations
LLM tool-use agents operate in dynamic environments where many actions carry operational risk. However, most safety mechanisms react only after errors manifest. Existing pre-emptive approaches either fine-tune the agent on chain-of-thought deliberation or compile natural-language guardrails into runtime checks, but the...
Yun-Ju Kang, Seonghyeon Cho, Irene Li et al.· 0 citations
Large language models (LLMs) are increasingly relied upon to support ambient documentation and clinical reasoning. Here we examine the impact of a failure mode shared between these two applications by assessing their sensitivity to information incidental to the patient encounter. In 576 patient-clinician dialogues, we...
K. Vishwanath, Brandon Ye, A. Alyakin et al.· 0 citations
LLMs are increasingly deployed as autonomous agents in social environments, making it critical to study their ability to faithfully simulate human interactions. Central to this is grounding agents in realistic user personas, yet existing datasets rely on fictional personas and are limited to a handful of languages, lac...
Dennis Fucci, Andrea Bacciu, Dong Liu et al.· 0 citations
Language models frequently generate outputs in unintended languages or scripts, a phenomenon known as off-target generation. While existing research has focused on language selection, the dimension of script knowledge remains understudied: before any linguistic understanding can occur, users must recognize the graphic...
David Kletz, Sandra Mitrovic, Ljiljana Dolamic et al.· 0 citations
We present a fully offline speech-to-speech translation pipeline that runs on a Jetson Nano (4 GB) and corrects its own weak translations without retraining. A Whisper-tiny ASR feeds an Opus-MT translator; multilingual BERT cosine similarity acts as a Quality Estimation (QE) gate, triggering a secondary-pass correction...
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
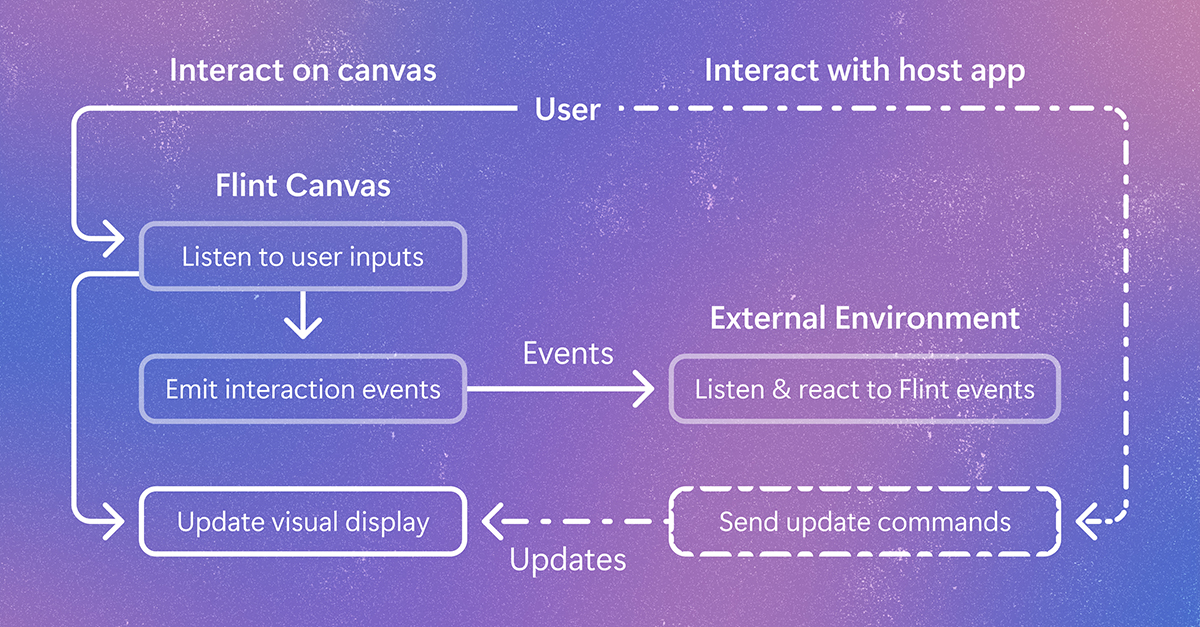
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.