Small language models are inexpensive to serve and can run on private infrastructure, but base models are often not good enough at multi-turn tool calling, and fine-tuning them needs per-API data that rarely exists. Existing synthesis methods are too expensive for high-scale fine-tuning, as they often require mock oper...
Aaron Fainman, Gabriela Kadlecová, Maciej Gryka et al.· 0 citations
Speculative decoding accelerates inference for a large language model (LLM), referred to as the \emph{target model}, by first using a smaller model, referred to as the \emph{draft model}, to generate candidate tokens and then verifying them with the target model for acceptance or rejection. Prior studies primarily focu...
Yi-Chi Zhang, Zhi-Qi Wang, N. Gong et al.· 0 citations
Automatic assessment of communication quality in dyadic counseling conversations is bottlenecked by data: expert-rated corpora are small and expensive to grow. We study cross-domain transfer of expert overall-impression prediction across three German corpora of simulated counseling (two general-practice medical, one sc...
Small language models (SLMs) are attractive as local agent controllers because they reduce remote inference, latency, and deployment footprint, yet structured tool errors can cause an agent step to fail. Existing routers typically select a model once per query. However, agents expose sequential decision points whose di...
Abolfazl Younesi· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
User behavior simulation is the computational modeling of user interactions within information systems through the use of simulated agents in place of live users. It supports system testing and evaluation, decision-making and forecasting, and user experience design. Existing simulators rely on hand-crafted rules or dom...
Ni-Er Wu, Hong-Zhi Yin, Hui Li et al.· 0 citations
Model-guided directed evolution seeks to identify high-fitness protein variants under limited oracle budgets. Protein language models (PLMs) provide rich representations for this task, but task-agnostic zero-shot scores can be misaligned with a target assay, while supervised search in high-dimensional embedding spaces...
Si-Yuan Ma, Can-Ran Xiao, Zi-Kai Xiao et al.· 0 citations
Endpoint accuracy on abstract-reasoning benchmarks does not reveal whether a language model has acquired a transferable rule or fit distribution-specific regularities. We study this distinction in small language models on the ARC-TGI benchmark, which organizes abstract grid transformations into controllable task famili...
Nur A. Zarin Nishat, Jens Lehmann, Andrei C. Aioanei et al.· 0 citations
We ask whether specific attention heads, and more finely specific neurons inside those heads, are responsible for recognizing that a language model's context contains network infrastructure information (a hostname paired with its IP address), and whether that responsibility can be validated causally rather than by corr...
M. Kadir, Md. Mohashin Hossain, Daniel Sonntag University of Oldenburg et al.· 0 citations
Low-rank quantization error compensation (LQEC) recovers the accuracy lost under aggressive weight quantization by attaching a closed-form rank-$r$ adapter beside each frozen quantized weight, without any training. We show that existing compensators are limited by two shared simplifications. They calibrate symmetricall...
Seobin Song, Geonho Lee, Janghwan Lee et al.· 0 citations
Model merging offers a promising solution for combining multiple fine-tuned checkpoints into a single model through parameter arithmetic. However, finding optimal merging coefficients requires an extensive search that becomes prohibitively expensive as models scale in both size and number, due to high memory requiremen...
Shih-Cheng Huang, Zhi Rui Tam, Chieh-Yen Lin et al.· 0 citations
Autoregressive large language models (LLMs) have rapidly advanced in capability, but their increasing scale comes with substantial computational and memory costs at inference time. Knowledge distillation (KD) offers a practical solution by transferring knowledge from a large teacher model to a smaller student model via...
Byeonghu Na, Donghyeok Shin, Yeongmin Kim et al.· 0 citations
LoRA fine-tuning adapts small language models (SLMs) to heterogeneous instruction data within a low-rank update subspace, making it vulnerable to three structural problems: conflicting gradients that cancel, static data selection that cannot track evolving learning dynamics, and subspace saturation that causes later up...
Hong-Yu Cao, Yan-Chi Liu, Kun-Peng Liu et al.· 0 citations
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
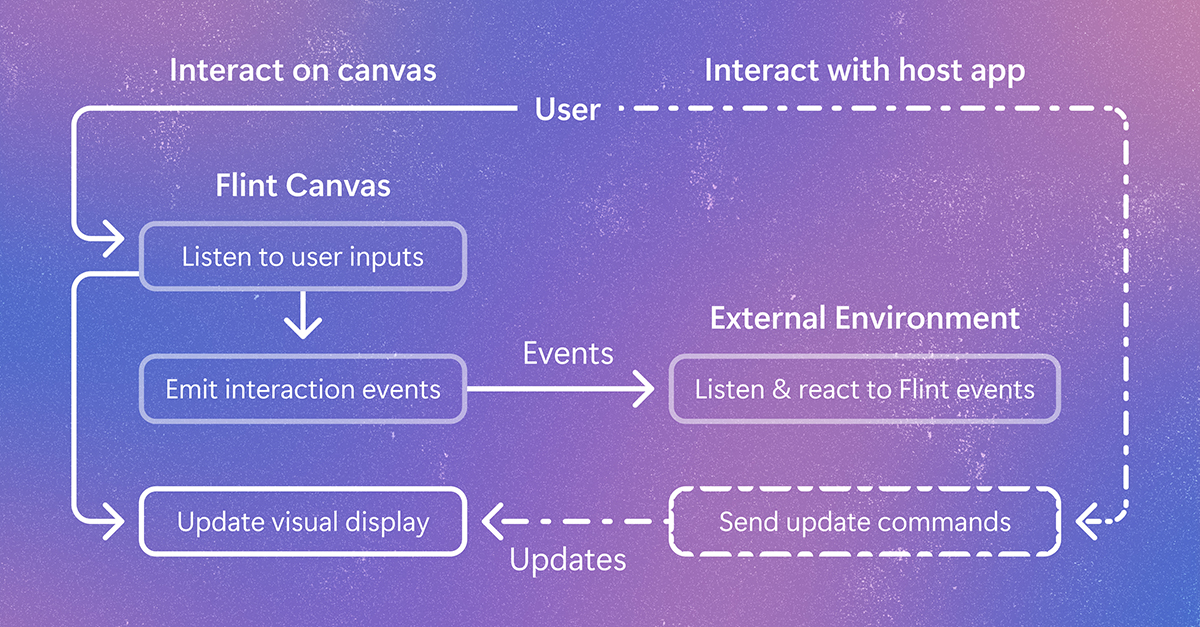
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.