NiceTryGPT is an open-source libre-software minimal-diff workflow for reducing cheap LLM shortcuts in existing Capture the Flag challenges while preserving the intended vulnerability class, learning objective, prerequisite knowledge, and human difficulty band.Version 0.2.0 includes reproducible before/after demonstrati...
Alessandro Greco· Zenodo (CERN European Organi...· 0 citations
Model compression — quantization, pruning, and knowledge distillation — is widely adopted on the premise that a smaller model costs less energy to run. This review examines the measurement layer beneath that premise and finds it less settled than its adoption suggests. Drawing on a purposively assembled corpus of 53 wo...
Shohinur Pervez Shohan· Zenodo (CERN European Organi...· 0 citations
Validation software for the use of DICOM RT DVH files at 1 cGy resolution as an intermediate caching layer between DICOM-RT source data held in a PACS and downstream clinical data repositories. Contains the DVH computation and caching modules, the dose-volume parameter extraction code, the six-phase experiment runner a...
R.D. Talstra, Rogier Janssen, D. Lipman et al.· Zenodo (CERN European Organi...· 0 citations
TTP-WorkBench Artifact TTP-WorkBench is a framework and benchmark for executing and comparing ten tools from prior work that extract MITRE ATT&CK tactics, techniques, and procedures from cyber threat reports. The artifact contains standardized tool adapters, container build specifications, curated prior-work data, and...
Sean Tyler Frankum, Evangelos Froudakis, Athanasios Avgetidis et al.· Zenodo (CERN European Organi...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Reproducibility release accompanying the manuscript: "Model Rankings in Drug–Target Affinity Prediction Vary Across Evaluation Regimes: A Controlled Multi-Seed Study of Model-Comparison Reliability" This release contains: frozen split indices and cryptographic hashes; source code for the three primary fusion models; co...
The virtual world is infinitely cheap. Software can dream up anything. It can generate endless trajectories and explore speculative high-entropy hypotheses, without a single gear in the material world coming to harm. This is the architecture's fail-open space. It is an accelerator tube filled with raw intensity, where...
Torjusen Marius Egerhei· Zenodo (CERN European Organi...· 0 citations
This monograph establishes the formal mathematical, computational, and architectural specification for Door 28 (Security: The Security Port and Sovereign Governance), the root cryptographic barrier and systemic immunity gateway of the realization monorepo. While Door 27 governs distributed Byzantine peer consensus, Doo...
Torjusen Marius Egerhei· Zenodo (CERN European Organi...· 0 citations
We establish the observer as a physical node within the causal graph and resolve the conceptual relation between relativity and quantum mechanics. The Mens Protocol defines the observer as a self-referential sampling operator embedded in the same finite-bandwidth causal graph that it observes. The Stride-10 sampling wi...
Yu Zhang· Zenodo (CERN European Organi...· 0 citations
NiceTryGPT is an open-source libre-software minimal-diff workflow for reducing cheap LLM shortcuts in existing Capture the Flag challenges while preserving the intended vulnerability class, learning objective, prerequisite knowledge, and human difficulty band.Version 0.2.0 includes reproducible before/after demonstrati...
Alessandro Greco· Zenodo (CERN European Organi...· 0 citations
Disruptive Cognitive Operations and Inner Ecology Action-Research Lessons Learned from a Dis|mis Administrative Incident This book is an action-research study of lessons learned from a dis|mis administrative incident. It uses the incident as a situated case through which to examine how administrative uncertainty, infor...
SⵙL¥DMAN· Zenodo (CERN European Organi...· 0 citations
This record provides version 0.5.0 of the reproducibility package for “Quasienergy Protection Does Not Imply Readability: Detector-Relative Access to Memory in a Periodically Driven Open Qubit” by Matthias Jakob. Version 0.5.0 is the corrected successor of version 0.4.0 (DOI: 10.5281/zenodo.22070504). It corrects the t...
Matthias Jakob· Zenodo (CERN European Organi...· 0 citations
Training can change more than what an artificial system answers. It can also change how the system weighs evidence, trusts sources, generalizes rules, reports internal states, and represents the very variables an auditor later attempts to compare. This paper studies the resulting problem as **Formative Epistemic Audit...
Hongju Liu· Zenodo (CERN European Organi...· 0 citations
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
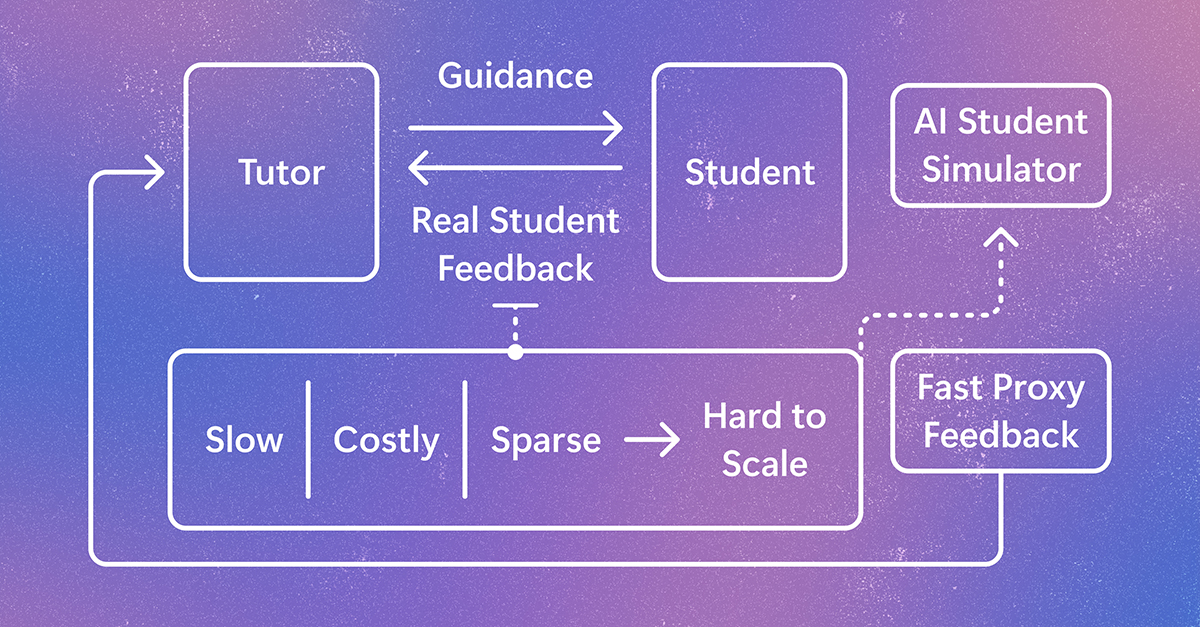
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.