Reinforcement learning (RL) is widely utilized in large language model training to improve targeted capabilities, yet how RL reshapes a model remains poorly understood. Prior attempts to explain how RL works largely offer behavioral perspectives, leaving open what RL gives a model at the representation level: can RL create genuinely novel features, and which existing features does it enhance or suppress? Recent developments in mechanistic interpretability suggest sparse autoencoders (SAEs) as a promising lens to decompose internal activations into human-interpretable features; however, they cannot be directly applied to tracking change across training. In this work, we introduce Fixed-SAE Track, a framework that trains one shared SAE per considered layer on activations pooled across the base model and all RL checkpoints, holding every feature direction fixed so that representation shifts are rigorously defined through the activations of interpretable SAE latents, including the detection of emerging novel features. Validated across multiple datasets and RL algorithms, we find that RL-induced drift is small, gradual, concept specific, and concentrated in late layers, mainly enhancing the sampling rates of a small set of ladder tokens, formatting scaffolding such as step breaks and answer delimiters, rather than reshaping problem content. Steering these features into the base model recovers around 80% of RL's performance gain, suggesting that RL primarily elicits capabilities the model already possesses, much as steering does. We further design a synthetic benchmark with features known by construction to test whether RL can instill genuinely novel features. We believe Fixed-SAE Track provides a principled approach to tracking representation shifts and offers representational evidence for understanding how reinforcement learning changes the inner representation of LLMs.
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.
Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al.· IEEE Transactions on Softwar...· 178 citations· ⚡14
This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.
Carmine Giardino, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 175 citations· ⚡19
Software startup companies develop innovative, software-intensive products within limited timeframes and with few resources, searching for sustainable and scalable business models.
M. Unterkalmsteiner, P. Abrahamsson, Xiaofeng Wang et al.· e-Informatica Software Engin...· 157 citations· ⚡17
Adaptive AI agents can help make BIM data more machine-readable by navigating IFC models, interpreting inconsistent information, and mapping it to defined standards. In this blog, Alok Rawat shares findings from a real-world pilot in construction workflows. The post Adaptive AI Agents in Construction Workflows appeared first on GPT-Lab.
What does it take to trust AI-driven HVAC optimization? Our AI Model Factory combines agents, machine learning, reinforcement learning and deterministic checks in a governed workflow designed for messy, real-world building data. The post We built an AI factory for HVAC control appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduAug 18, 2026
A new method for surgically removing training examples from a model reveals that as datasets grow, the link between what a model learns and what it produces dissolves.
Microsoft Research Blog· microsoft.comJul 30, 2026
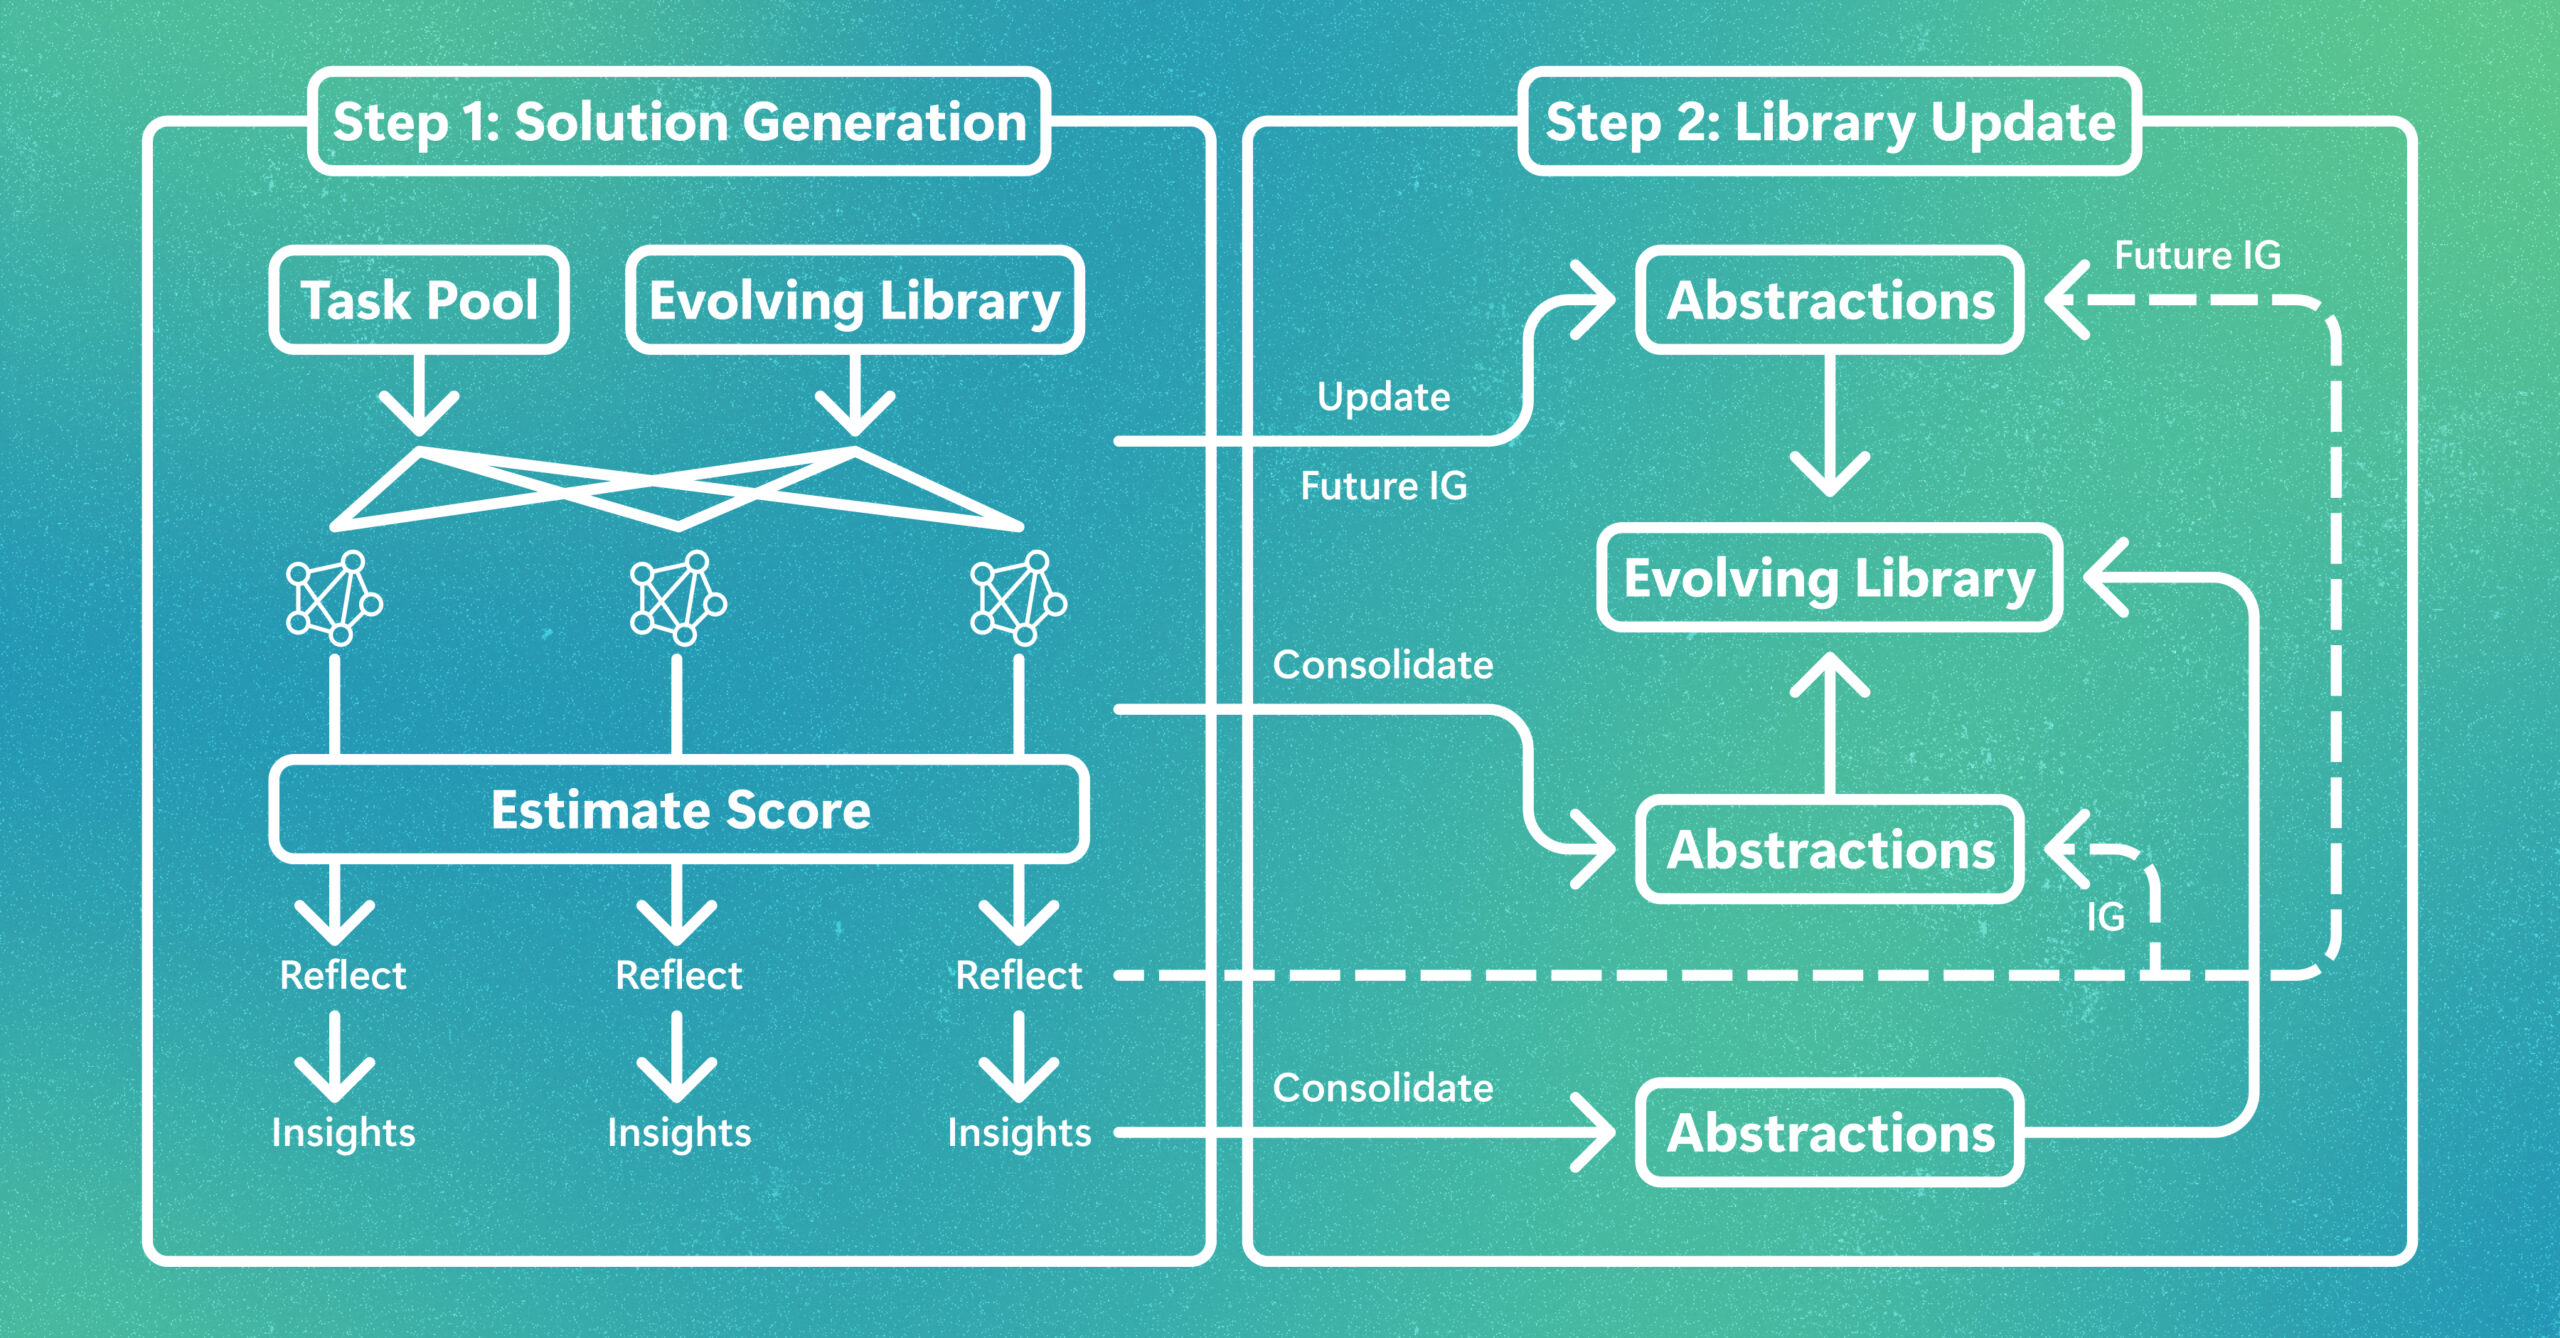
LLMs do not get smarter just by remembering more. EvoLib turns experience into evolving knowledge, taking reusable skills and insights that help models learn and adapt across tasks long after deployment. The post EvoLib: Turning experience into evolving knowledge appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.