This work examines what structure is supplied by the game or workflow, what AI learns or produces, which capabilities and artifacts transfer across settings and roles, and what evidence supports the claims and identifies cross-role connections.
Abstract
Foundation models, alongside advances in learned game-world models, are reshaping AI across the game lifecycle. Beyond playing games, recent systems model players and game dynamics, support design and development, adapt player-facing experiences at runtime, and evaluate resulting artifacts. Yet these directions have evolved largely separately, obscuring which capabilities transfer across settings and which remain tied to particular games, engines, interfaces, or player populations. We organize the literature into six roles according to the immediate use of AI output: playing and acting; modeling players and games; designing games; building and maintaining games; generating and adapting at runtime; and testing and evaluating games. For each role, we examine what structure is supplied by the game or workflow, what AI learns or produces, which capabilities and artifacts transfer across settings and roles, and what evidence supports the claims. We identify cross-role connections: trajectories train world models, learned environments provide experience for agents, design specifications drive executable implementations, and play or testing feedback guides revision. However, control schemes, rules, engine interfaces, state representations, and player contexts often remain setting-specific, so downstream claims require validation in the target setting. Evaluation is most standardized for bounded game playing and selected learned environments, while persistent state in learned worlds, repeated software revision, validated player modeling, sustained runtime adaptation, and representative automated testing remain less established. The central challenge is to reuse or transfer outputs and capabilities across roles while re-establishing evidence for effectiveness in the game-specific contexts where they are used.
Adaptive game systems are evolving rapidly, yet the combination of Dynamic Difficulty Adjustment (DDA), a technique that modifies a game’s challenge level based on player performance, and Explainable Artificial Intelligence (XAI), which makes AI decisions transparent and understandable, remains largely unexplored. DDA...
Benjamin Murphy, A. Bourazeri· ACM Computing Surveys· 0 citations
Recent advances in Large Language Models (LLMs) have demonstrated remarkable capabilities in web front-end execution, with browser-based game generation emerging as a particularly prominent frontier. While previous efforts frequently rely on complex multi-turn workflows or focus on static game evaluation benchmarks, th...
Haoyue Yang, Jing-Yao Li, Zhen Wu et al.· 0 citations
This technical report details the infrastructure behind Game Arena and describes the three pilot game environments: Chess, Poker, and Werewolf, enabling a systematic study of models's strategic planning, adaptation, and robustness under uncertainty.
Bovard Doerschuk-Tiberi, Yao Yan, Justin Chiu et al.· 1 citation
Results characterize current agent capabilities across game-development activities and support combining runtime evidence with visual assessment, as well as identifying requirement omissions and gameplay logic errors as predominant implementation problems.
Xiao-Yun Chen, Lai Wei, Jing-Ping Wang et al.· arXiv.org· 2 citations
Recent large language models (LLMs) can operate as coding agents that build complete games from natural language requests. Game development is especially demanding because program logic, visual and audio content, interfaces, interaction and playability must function together in one executable artifact. Measuring this c...
Kun Chen, Hao-Rong Hong, Pei-Zhong Gao et al.· 6 citations
Adversarial games have driven advances from heuristic search to reinforcement learning, yet learning and adapting strategies from limited samples remain challenging. AI agents offer an alternative by turning game experience into revisions of executable policies. Building on heuristic learning (HL), we formalize Adversa...
Kai-Sen Yang, Qing-Le Liu, Ke-Jin Wang et al.· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comNov 12, 2026
What's new in research at Microsoft? Host Anson Ho explores the latest, including AI-powered universal translation, a breakthrough in a 31-year-old mathematics challenge, and advances making AI coding agents faster and more efficient. The post Microsoft Research Focus – Edition #98 appeared first on Microsoft Research.
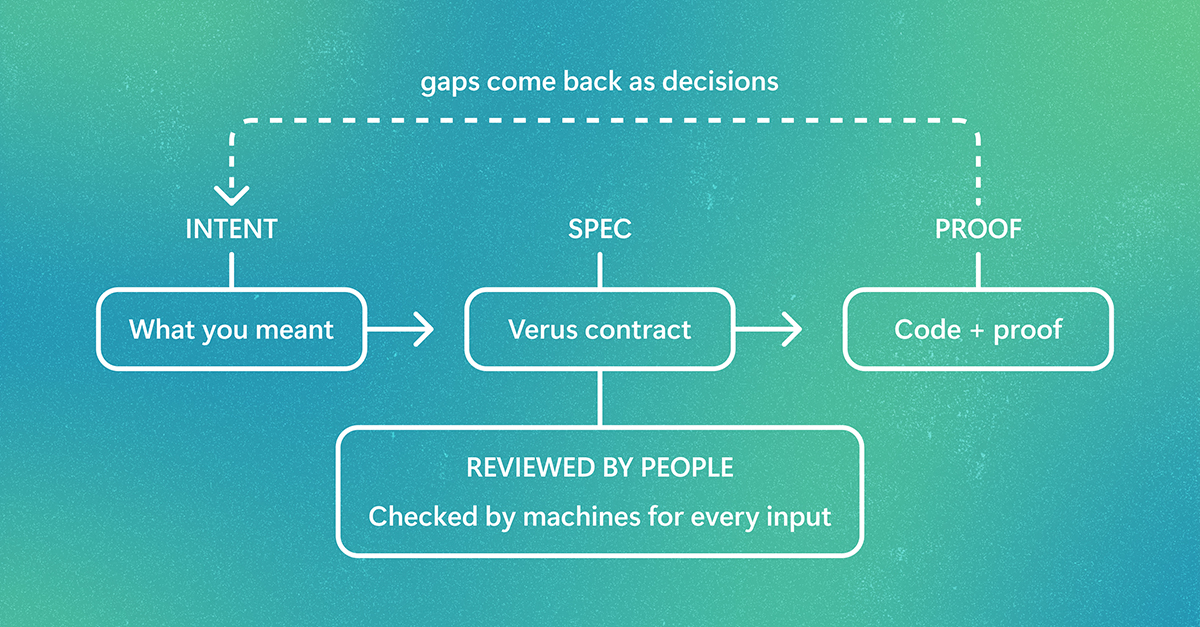
AI agents can generate code at a scale that’s hard for humans to review line-by-line. PDD Kit helps ensure the code is doing what the developer intended by creating formal specifications and testing against them. It converts developer intent into a Verus specification, proves AI-generated code meets it for every input, and uses tests where proofs aren't practical. Developers review intent, not every line. The post Formally verifying agent-written full-stack web apps with PDD Kit appeared first o…