HALTER, a Harness for Autonomous Long-horizon Task Evaluation and Reset, which restores the scene by planning over a library of learned atomic reset skills, so demonstration cost scales with the size of that library rather than with the number of terminal states.
Abstract
Robot manipulation policies are improving quickly, and real-robot evaluation remains the standard evidence for that progress. It still relies on a human to reset the scene between rollouts, which consumes operator time and leaves the initial state distribution unspecified, so results reproduce poorly. A recent system, AutoEval, automates both reset and scoring, but only for single-step tasks, because a long-horizon rollout can terminate in combinatorially many configurations that no single learned reset policy covers. We present HALTER, a Harness for Autonomous Long-horizon Task Evaluation and Reset, which restores the scene by planning over a library of learned atomic reset skills, so demonstration cost scales with the size of that library rather than with the number of terminal states. HALTER builds a spatial scene graph online from point clouds and vision foundation models, and an LLM reasons over this graph to score the rollout, plan the reset, and verify that the reset succeeded, without collecting labeled success images for any task. On four long-horizon tasks on a Franka arm, HALTER restores the scene in 76% of episodes, against 52% for AutoEval and 65% for a motion-planning reset, and it estimates the completed-skill fraction correctly in 90% of episodes, against 76%. Its reset-verification verdict is correct in 91% of episodes, compared with 78% for AutoEval. It also cuts the operator time of an evaluation campaign by 72% relative to manual reset. We further measure compositional generalization on three held-out tasks, where HALTER resets 74.7% of episodes against 1.3% for a per-task reset policy, and we ablate the scene representation and the graph update rate.
Robots must often continue a task after a target moves, the viewpoint shifts, or an obstacle appears, even though their earlier observations and committed actions reflect the previous scene. Many simulation robustness benchmarks fix external conditions at reset, leaving this temporal challenge underexamined. We introdu...
Yun-Bei Zhang, Zi-Jian Jin, Yuan-Zhe Liu et al.· 0 citations
Results show that initial-state performance does not determine recovery performance and policies exhibit different recovery strengths across scenarios, and RoboRecover establishes recovery from execution-induced intermediate states as a distinct dimension of robot policy evaluation.
Yang Li, Chen Zhao, Zhuo-Ran Wang et al.· 1 citation
Improvements show that an explicit graph world model harness can substantially improve the reliability and efficiency of long-horizon embodied planning across compact and frontier hosted LLM capabilities.
Rui-Yang Wang, Hao-Lun Hsu, S. Mehta et al.· 0 citations
SAGE (Symbolic Action-Gating and Editing), a single-LLM planner built from two lightweight mechanisms: a domain-agnostic symbolic gate that blocks precondition-violating actions with typed reasons as a runtime safety monitor, and a local edit that regenerates only the failed sub-goal's suffix, keeping completed and unt...
T. Bui, Jongsul Moon, Youngouk Kim et al.· 0 citations
Foundation-model policies for robotic manipulation are advancing rapidly on task success, but rigorous evaluation of whether they succeed safely is still lacking. We introduce ManiGuard, a specification-grounded framework for evaluating and improving the safety of foundation-model manipulation, comprising the ManiGuard...
Yi Peng, Philip Wang, Simon Sinong Zhan et al.· 2 citations· ⚡1
Hierarchical planning frameworks combine skills from multiple robot control policies for long-horizon task execution, where determining when to terminate the current skill and advance to the next subtask is essential. Existing approaches often rely on pre-designed completion signal checkers that are hard to obtain in r...
Jinbang Huang, Yuan Hu, Zhi-Yuan Li et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduJul 30, 2026
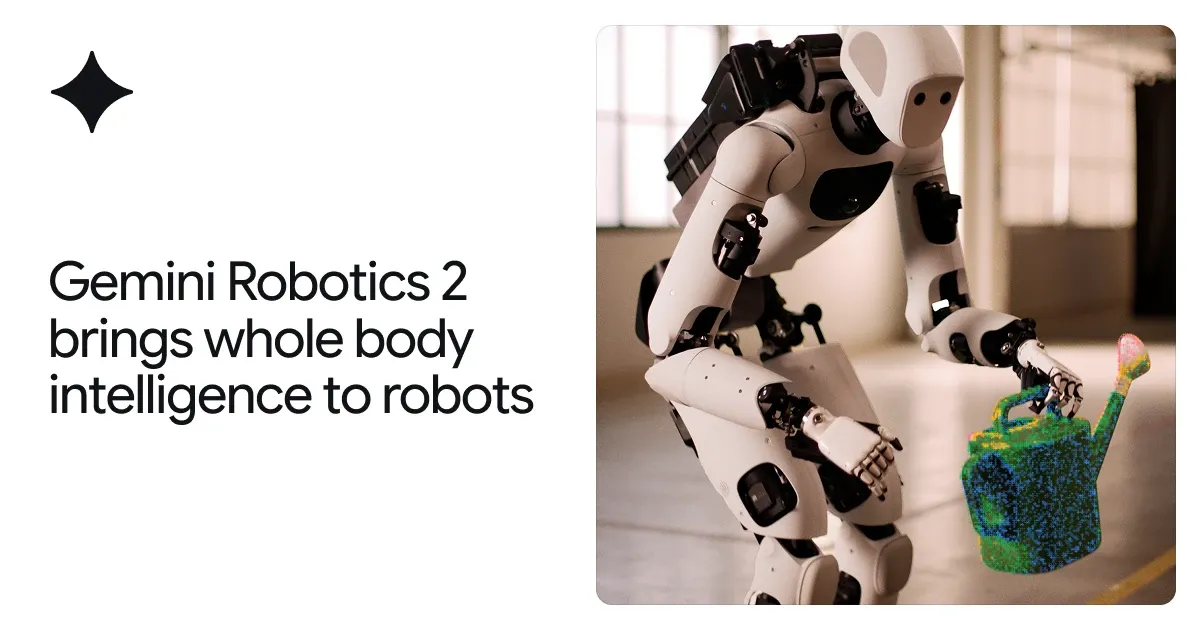
From feet to fingertips — we are teaching robots intelligent whole-body control, fine dexterity, and teamwork to complete a broad range of complex tasks.